Connect Langfuse MCP to your AI agents, securely.
One secured endpoint for every Langfuse call your AI agents make, scoped per user, inspected, and logged.Try Langfuse MCP now
What your agents can ask once Langfuse MCP is connected.
Select the tools your AI agents can call
94 tools from the Langfuse MCP schema.
Showing 94 tools
What Langfuse MCP exposes
Langfuse MCP groups its 94 tools into 14 categories, each with a suggested starting policy.
All 94 tools as JSON, ready to paste.
| Category | Covers | Access | Suggested policy |
|---|---|---|---|
| Datasets | Upserting datasets and their items individually or in batches of up to 100, listing and reading datasets, items, runs and run items, deleting an item with all its run items, deleting a run, and creating run items that link a dataset item to a trace or observation | Read / Write | deleteDatasetItem takes its run items with it and deleteDatasetRun enqueues deletion of everything under the run. batchUpsertDatasetItems is not atomic: it processes in order and stops on the first failure, so a partial batch is a real outcome |
| Dashboards | Listing, reading, creating, updating and deleting dashboards and dashboard widgets, and adding, updating or deleting the placements that position widgets on a dashboard | Read / Write | Nothing here reaches production behaviour, so this is the safest write surface on the connection. The deletes remove shared views other people rely on, which is an availability concern rather than a data one |
| Annotation Queues | Listing, creating and reading annotation queues, the worklists that collect traces or observations for human review and scoring, managing the items in them with their pending or completed status, and assigning or unassigning project users to a queue | Read / Write | createAnnotationQueueAssignment puts work in a named person's queue, so an agent here is allocating human effort. Queue items reference real traces, so the queue is a pointer into production data |
| Scores | Finding and reading quality, evaluation and feedback scores for traces, observations, sessions and experiments, creating a score, and listing, reading, creating, updating and archiving score configurations with their numeric ranges or categories | Read / Write | Score reads are eventually consistent, so a score created here may not appear in a read immediately; an agent that retries on a missing score can double-write. Score configs define what every later score is validated against |
| Evaluators | Listing Langfuse and partner evaluator templates, listing, reading, creating, updating and deleting project evaluators of LLM-as-a-judge, code and decision-model types, and testing a saved or draft evaluator against one observation | Read / Write | createEvaluator and updateEvaluator accept up to 256 KB of Python or TypeScript that Langfuse runs. testEvaluator executes it against a real observation, emits an internal trace and may incur model or code execution cost. deleteEvaluator cannot be undone |
| Evaluation Rules | Listing and reading the rules that run evaluators automatically, creating and updating them, attaching an evaluator to a rule or detaching it, and deleting a rule | Read / Write | Creating a rule or attaching an evaluator starts automatic scoring against incoming traffic, which is a recurring model cost rather than a one-off. Detaching or deleting stops evaluation silently, so both directions deserve a log line |
| Prompts | Fetching a prompt by name with a label or version and with dependencies resolved or left intact, listing and filtering prompts with their versions, labels and tags, creating new text and chat prompt versions, and updating the labels on a version | Read / Write | Prompts are immutable, so content changes create a new version that receives the latest label and cannot be given the production label at creation. updatePromptLabels is the only route to production, and labels are unique across versions, so setting one moves it off whichever version held it |
| Metrics & Platform | Analytics queries over usage, model cost, latency, errors and scores with grouped breakdowns, the schema of what can be analyzed, metadata and a signed download URL for a media asset, an API health check, v4 migration data and feedback to Langfuse | Read / Write | getMedia returns a signed download URL, so the asset itself moves outside the server and is invisible to anything watching tool calls alone. getMetricsSchema is the prerequisite for a queryMetrics call that validates |
| Observations | Finding and paging through generations, spans, events, agent steps and tool calls with filters for trace, name, type, level, environment and time, reading one by ID, and discovering which fields and filters are available with their example values | Read | Read-only but this is the production LLM traffic itself. Metadata truncates to 200 characters per key unless expandMetadataKeys is passed, and input, output and metadata projections require a window of at most 14 days |
| Models | Listing the custom and Langfuse-managed model definitions visible to the project, creating a custom definition for cost tracking and tokenization, reading one by ID and deleting a custom one | Read / Write | Model definitions set the prices used for cost attribution, so changing one rewrites what every later trace appears to have cost. Built-in models cannot be deleted |
| Experiments & Alerts | Listing experiments and their items, and listing and reading the project's alerts | Read | Entirely read-only. Alerts can be read but not changed through this server, which removes the usual risk of an agent quietly silencing monitoring |
| Comments | Creating a comment of up to 5,000 characters on a trace, observation, session or prompt, listing comments filtered by object or author, and reading one by ID | Read / Write | createComment accepts an author user ID, so an agent can attribute a comment to a person. Comments sit on production traces where colleagues will read them as human notes |
| Skills | Listing and searching project skills, reading their metadata, SKILL.md and files | Read | Read-only; safe to allow |
| Documentation | Searching the Langfuse docs, fetching a docs page and the llms.txt index | Read | Allow documentation searches |
Connect Langfuse MCP to your AI agent
Four steps, under ten minutes.
- 01
Sign in to NeuralTrust
Open the NeuralTrust platform, sign in and go to Getting started, then Connect your tools.
- 02
Choose your agent
When asked which agent you use, pick Claude Code, Codex, Cursor, Windsurf, Copilot or your own code.
- 03
Connect Langfuse
Find Langfuse in the tool list and connect it.
- 04
Connect your agent
Follow the steps on screen to add the config to your agent, then send the test prompt.
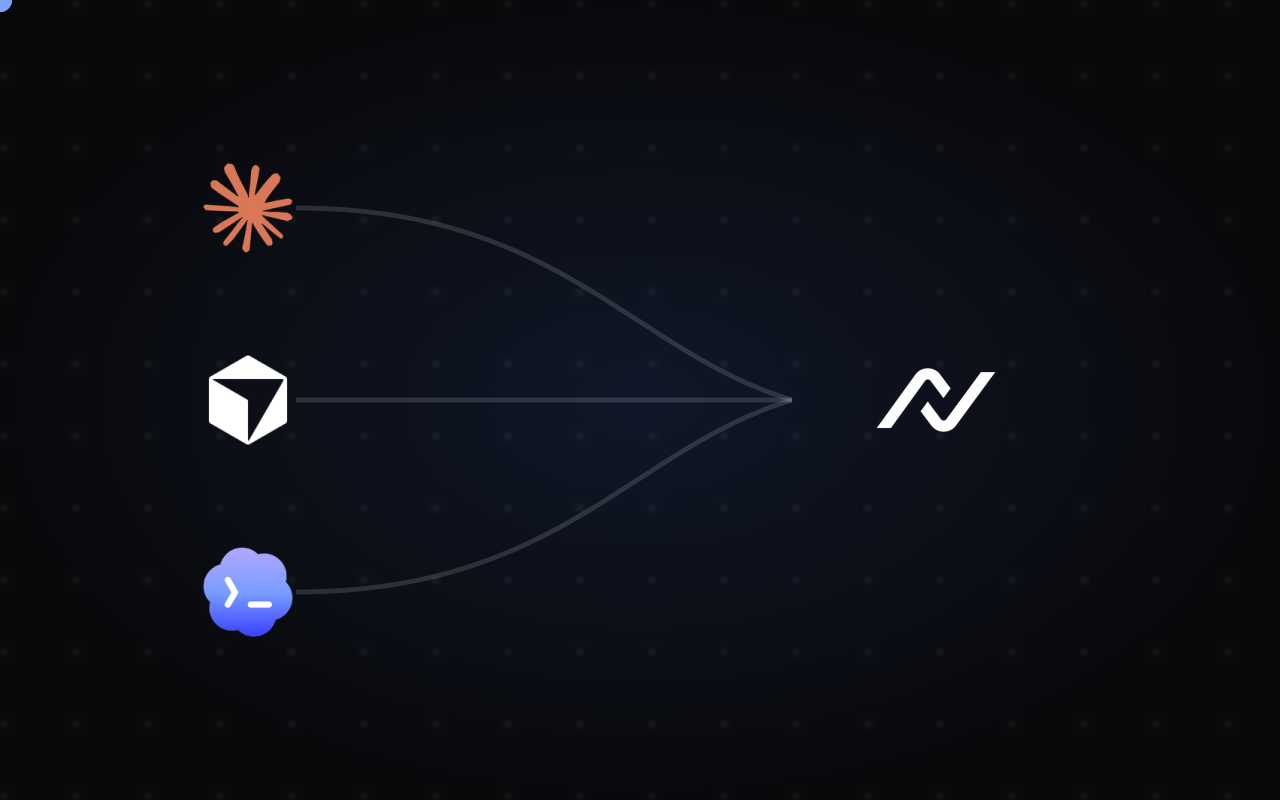
Permissions down to the single tool
You do not allow Langfuse MCP or block it. You allow the exact tools each agent can call, one by one.
| Langfuse MCP | 94 TOOLS AVAILABLE |
|---|---|
| Code review agent | 4 tools, read only |
| Issue triage bot | 9 tools |
| Platform team assistant | all 94 tools |
- Tool by toolConnecting the server is not the unit of access. Each tool is granted on its own.
- Default denyA tool you have not enabled is never exposed to the agent.
- Approval on writesTools that change or delete things can require a human to confirm.
Is Langfuse MCP secure?
One endpoint instead of raw credentials. Every call is checked against policy and logged.
| AI agentsConnect through your MCP client configuration. | NeuralTrustApply controls based on your configuration. | Langfuse MCP94 documented tools on the authenticated, project-scoped Langfuse Cloud MCP server, available for EU, US, Japan, HIPAA US, self-hosted and local deployments. Authentication is HTTP Basic with a base64 public and secret key pair. Langfuse describes the server as self-describing and warns that its tool set and schemas may change, so clients should refresh capabilities rather than assume a static interface. A separate unauthenticated Langfuse Docs MCP server offers four documentation tools. |
|---|---|---|
| Coding assistants | Connection & credentialsper user | Datasets13 tools |
| Internal copilots | Tool access policiesdeny by default | Dashboards13 tools |
| Workflow automations | Request & response inspectioninline | Annotation Queues10 tools |
| Compatible MCP clients | Activity monitoringalerts and logs | All other tools58 tools |
Use Langfuse MCP with any AI agent framework
Setup guides for the tools your team already uses.
 Claude CodeAdd Langfuse MCP to Claude Code from the terminal
 CursorUse Langfuse MCP tools inside Cursor's agent
 CodexConnect Langfuse MCP to the OpenAI Codex CLI
 WindsurfGive Windsurf's Cascade access to Langfuse MCP
 Gemini CLICall Langfuse MCP from Gemini CLI prompts
 Google AntigravityLet Antigravity agents work with Langfuse MCP
 GitHub CopilotUse Langfuse MCP in Copilot agent mode
 Claude EnterpriseRoll out Langfuse MCP across your Claude workspace
 Microsoft Copilot StudioAdd Langfuse MCP as a tool for Copilot Studio agents
 Open WebUIBring Langfuse MCP tools into Open WebUI chats
 LangChainLoad Langfuse MCP tools into LangChain agents
 HaystackPlug Langfuse MCP into Haystack agent pipelines
 Strands AgentsGive Strands agents Langfuse MCP tools
 Vercel AI SDKCall Langfuse MCP from Vercel AI SDK apps
 n8nUse Langfuse MCP in n8n AI agent workflows
Common questions about running Langfuse MCP through TrustGate.
Other MCP servers
More servers from the catalog.

Braintrust
Securely connect your AI agents to Braintrust through TrustGate: SQL over logs, experiments and datasets, traces, prompts, evaluators, online scoring, Topics, dashboards, alerts and evals, scoped per agent and logged.
47 toolsView
PostHog
Securely connect your AI agents to PostHog through TrustGate: insights, SQL, dashboards, feature flags, experiments, error tracking and documentation, scoped per agent and logged.
1135 toolsView
Axiom
Securely connect your AI agents to Axiom through TrustGate: APL and MPL queries over events, traces and metrics, datasets and fields, dashboards, monitors, notifiers and the service map, scoped per agent and logged.
31 toolsView
Statsig
Securely connect your AI agents to Statsig through TrustGate: feature gates, experiments, dynamic configs, metrics, logs, layers, segments and parameter stores, scoped per agent and logged.
27 toolsView
Connect Langfuse MCP instantly
Pick the tools, point your agent at TrustGate, and Langfuse MCP is live: scoped, inspected, logged.