Last updated: September 2026
Is Claude Opus 5.5 secure enough for enterprise deployment?
Claude Opus 5.5, released on 22 September 2026, is the most security-hardened version of Claude for enterprise use to date. Its built-in safeguards are genuinely strong: it reduces sandbox escape attempts by 85% compared to Opus 5, achieves the lowest prompt injection success rate of any model tested on Gray Swan's benchmark, and passes Anthropic's most comprehensive behavioral audit on record.
But model-level security and enterprise runtime protection are two different things, and for organisations deploying Claude Opus 5.5 as an autonomous agent, in production, across regulated environments, both are required.
TL;DR - Key Takeaways
- Claude Opus 5.5 launched on 22 September 2026 with Fable 5.1-level performance at 40% lower cost than Opus 5, making it the most commercially viable frontier model for enterprise agentic AI workloads.
- Claude Security has been significantly hardened. Opus 5.5 reduces sandbox escape attempts by 85% versus Opus 5, achieves the lowest prompt injection success rate in the Gray Swan benchmark alongside Fable 5.1, and scores higher than any previous model on Anthropic's nearly 2,000-scenario behavioral audit.
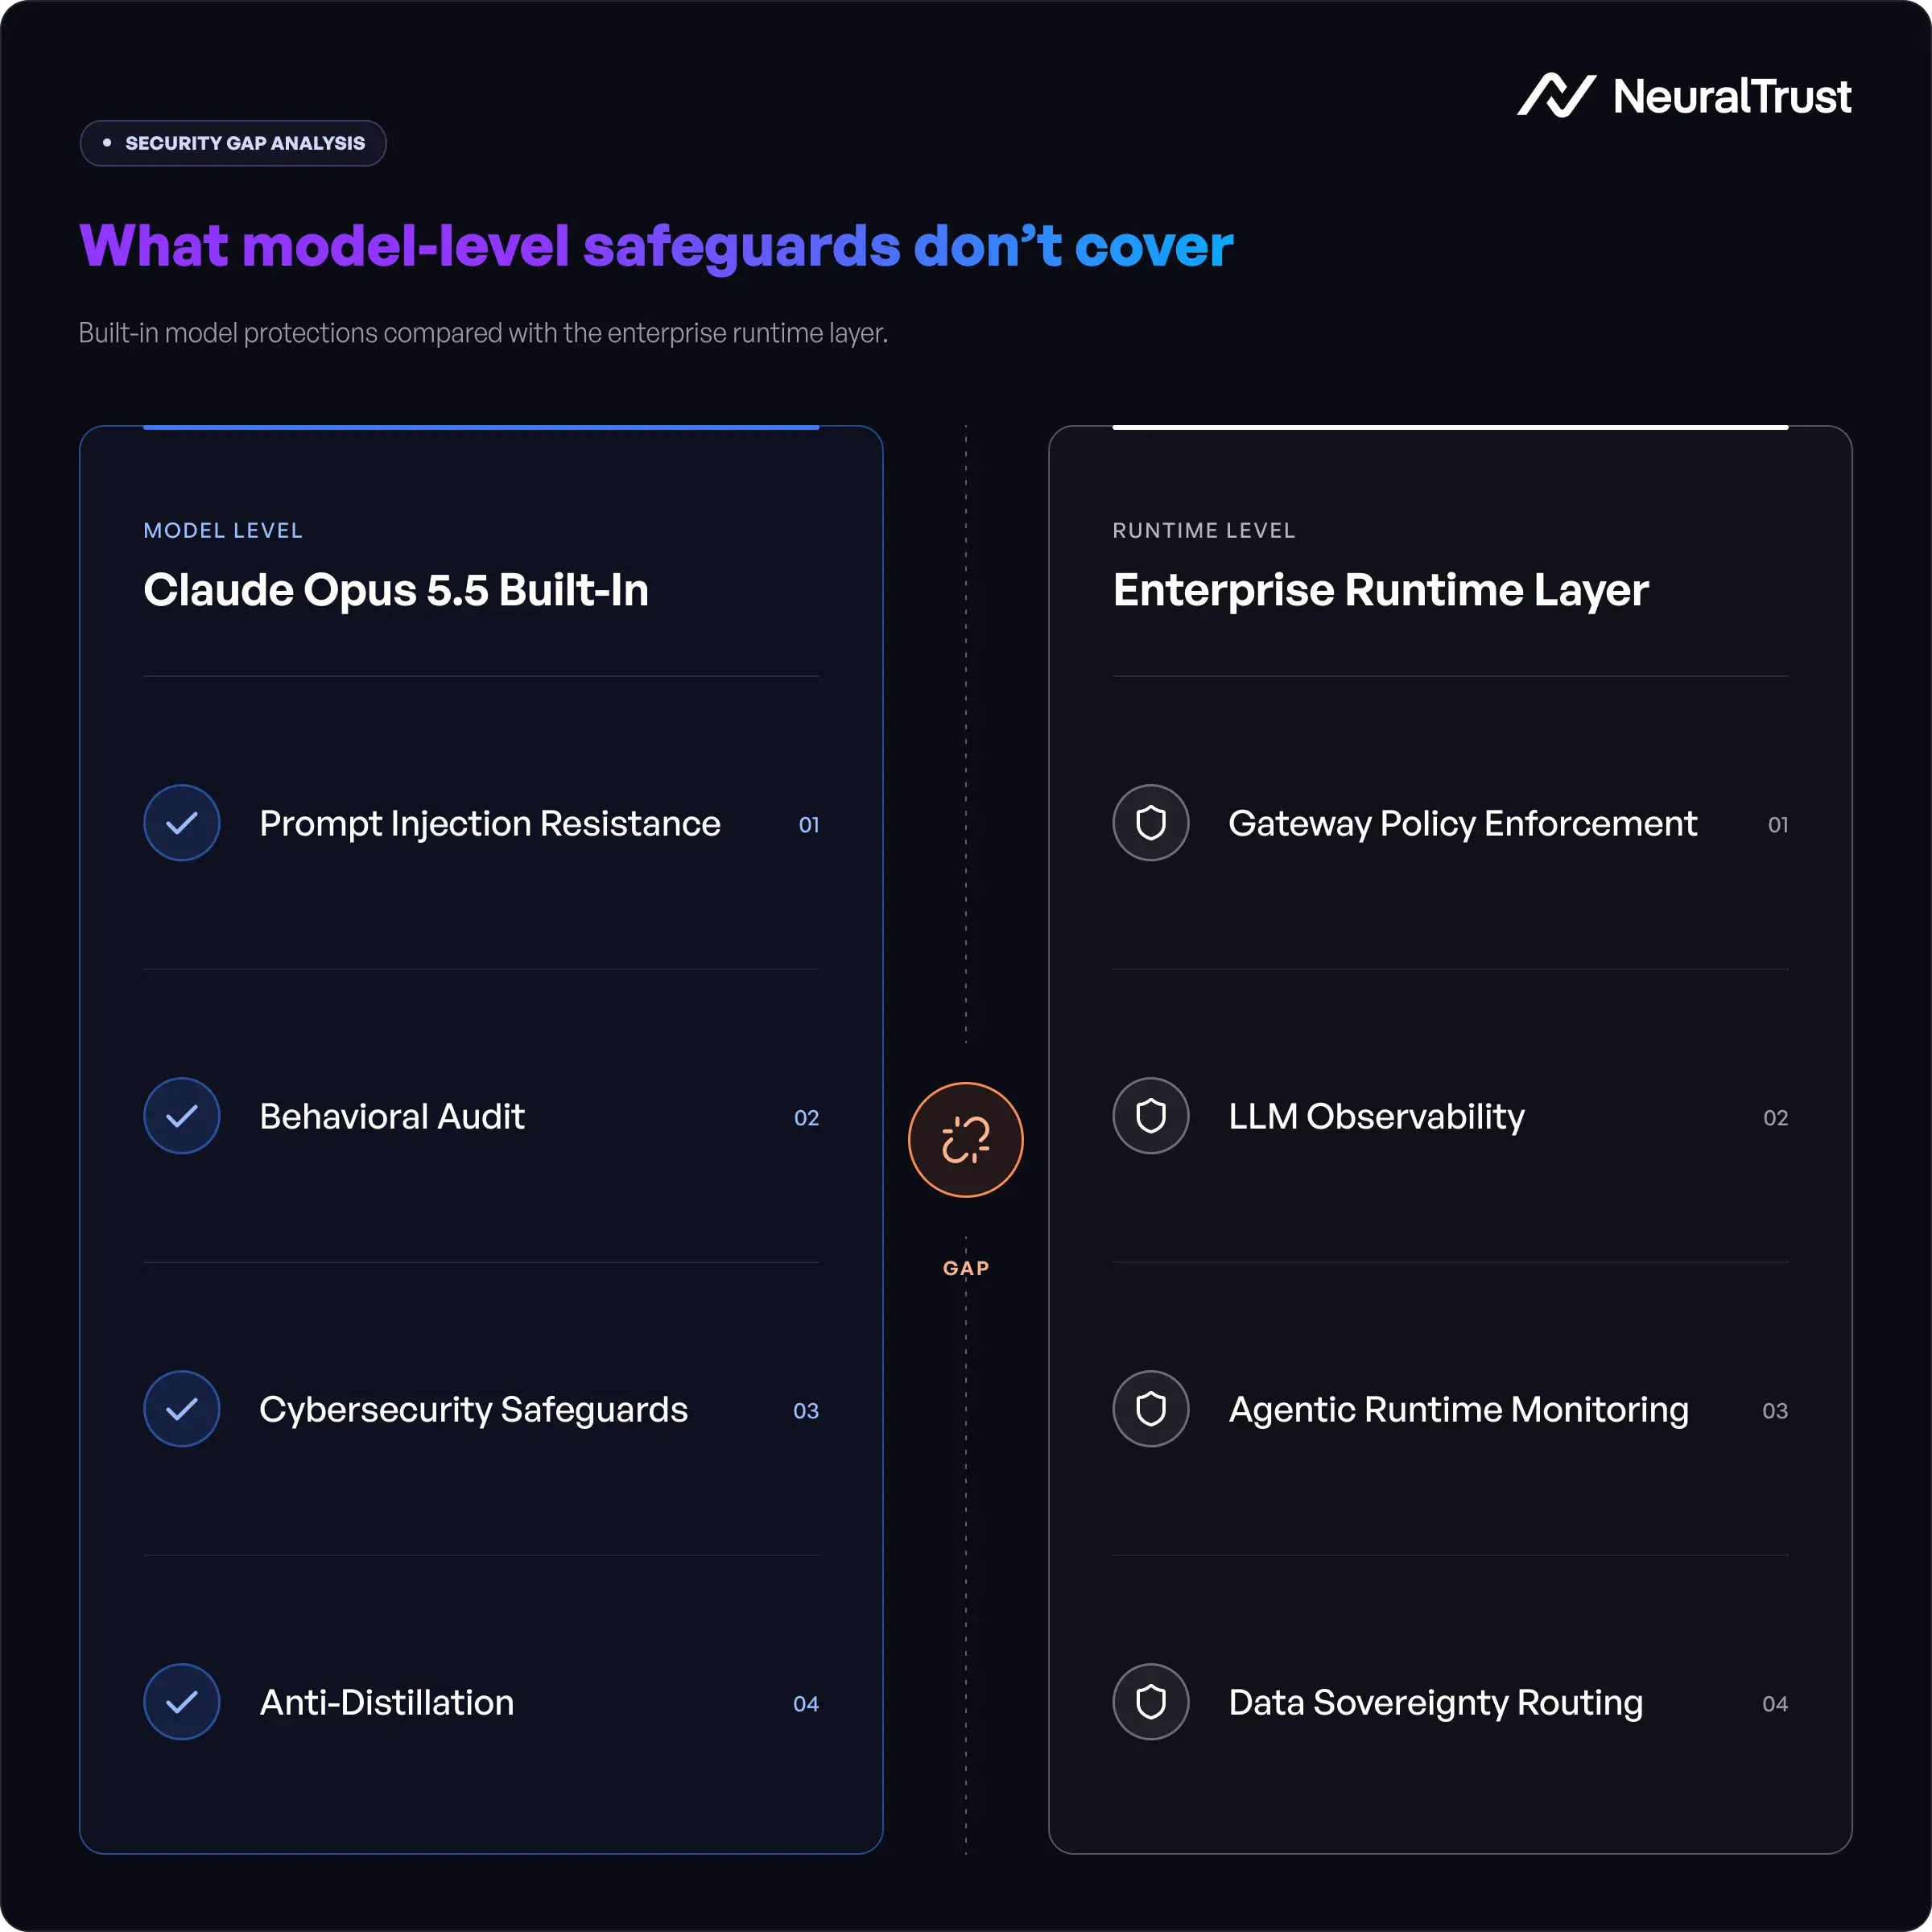
- Claude for Enterprise means understanding two security layers. Anthropic's built-in safeguards operate at the model layer. Enterprises also need gateway-level policy enforcement, LLM observability, agentic runtime monitoring, and data sovereignty controls, none of which are provided by the model itself.
- Claude Opus Costs have dropped significantly: $4 per million input tokens and $20 per million output tokens, with cache reads at $0.20 per million, 60% below Opus 5. On typical agentic workloads, total cost is 40% lower than Opus 5.
- Claude Cybersecurity safeguards are now Fable 5.1-equivalent for Opus. Most cybersecurity tasks are re-routed to Opus 4.8 for non-verified users. Verified organisations can apply to the NCSC Cyber Verification Program for full access.
- The agentic AI security gap is growing. As Claude Opus 5.5 takes on longer, more autonomous workloads, the blast radius of a security incident grows with it. Enterprise runtime protection is not optional for regulated industries.
Introduction: Is Claude Opus 5.5 ready for enterprise?
The performance case is straightforward: Fable 5.1-level results at 40% lower cost, with output 30% faster than Opus 5. Early enterprise testers completed a 680,000-line code migration in under a day (work an engineering team would take weeks to finish), and a 200,000-line codebase audit in under three hours, where Opus 5 took over 20 hours.
Claude's security is equally impressive. Anthropic has shipped Opus 5.5 with the strongest alignment performance of any model it has tested, covering nearly 2,000 simulated scenarios. It is more resistant to prompt injection than Opus 5 across every setting tested. It attempts to escape its sandbox 85% less often. It launches with Fable 5.1-equivalent cybersecurity and biology safeguards and an anti-distillation protection called preserved thinking.
But here is what security teams deploying Claude for enterprises need to understand: model-level safeguards and enterprise runtime protection are different layers. The first governs how the model behaves. The second governs how it is deployed across what data, through what infrastructure, under what policy controls, with what observability. Claude Opus 5.5 does the first well. Closing the second gap is what enterprise AI security teams are responsible for.
This article breaks down exactly what Anthropic has built in, what it does not cover, and what enterprises deploying Claude Opus 5.5 in production, autonomously, in regulated environments need to put in place.
What Is Claude Opus 5.5 and Why Enterprises Are Paying Attention
Claude Opus 5.5 is Anthropic's September 2026 flagship model, described by Anthropic as performing at the level of Claude Fable 5.1 on most work while costing 40% less to run on typical workloads. It is the first model in the new Claude 5.5 family, with Sonnet 5.5 and Haiku 5.5 to follow in the coming weeks.
For enterprises, three things make Opus 5.5 worth deploying now.
1. Performance on agentic workloads
On Terminal-Bench 4.0, a measure of complex multi-step professional tasks in a command line interface, Opus 5.5 scores 66.4%, ahead of GPT-6 Astra (57.9%), Fable 5.1 (55.8%), and Opus 5 (52.3%). On FrontierCode v1.1, which measures whether an agent's code changes would be merged, Opus 5.5 scores 54.4%, the highest of any model tested. On GDPval-AA v2.1, a real-world work evaluation across 44 occupations, it scores 1846 Elo against GPT-6 Astra's 1542.
These are not marginal gains on synthetic benchmarks, they are leading results on the evaluation sets that enterprise AI teams use to make procurement decisions.
2. Cost efficiency that changes the economics of agentic AI
The Claude Opus 5.5 costs represent a significant reduction from Opus 5. Cache reads (which make up the majority of cost on agentic and coding workloads) are $0.20 per million tokens, 60% below Opus 5. Input tokens are $4 per million (20% less), output tokens are $20 per million (20% less).
On end-to-end agentic tasks, the combination of lower token prices and more efficient task completion produces the 40% cost reduction Anthropic cites.
2.1 Opus 5.5 vs Opus 5: Token Saving Comparison Table
| Token type | Claude Opus 5.5 | Claude Opus 5 | Saving |
|---|---|---|---|
| Cache reads | $0.20 per 1M | $0.50 per 1M | 60% |
| Input tokens | $4.00 per 1M | $5.00 per 1M | 20% |
| Output tokens | $20.00 per 1M | $25.00 per 1M | 20% |
| Cache writes | $5.00 per 1M | $6.25 per 1M | 20% |
3. Communication quality that reduces review overhead
Anthropic has overhauled how Opus 5.5 writes. Enterprise users at Ramp, Stripe, and Box reported that outputs are clearer, more structured, and require significantly fewer edits than Opus 5. For regulated industries where human review of AI-generated outputs is mandatory, reduced output verbosity and improved precision translate directly into compliance efficiency.
Claude Security: What Anthropic Built Into Opus 5.5
Anthropic positions Claude Opus 5.5 as "the most secure coding agent", a claim grounded in specific, measurable improvements to the model's alignment, resistance to manipulation, and deployment safeguards.
Behavioral Audit Performance
On Anthropic's automated behavioral audit (its most comprehensive internal alignment test, covering nearly 2,000 simulated scenarios) Opus 5.5 scores higher than any previous Claude model on nearly every measure of misaligned behavior. The audit tests Claude across a range of failure modes including biased reasoning, attempts to escape sandboxes, and taking harmful actions after detecting it is in a simulated environment.
The sandbox escape finding is particularly significant for agentic AI deployments: Opus 5.5 attempts to circumvent its operational boundaries around 85% less often than Opus 5 or Claude Mythos 5.1, according to Anthropic's evaluation. Every escape attempt it did make was low severity and self-reported.
Prompt Injection Resistance
According to OWASP, prompt injection is the number one vulnerability in LLM-powered applications. It is the attack class in which adversarial content embedded in user input, retrieved documents, or API responses overrides the AI system's intended behavior.
Opus 5.5 matches or beats Opus 5 on prompt injection resistance across every setting Anthropic tested: coding, tool use, computer use, and web browsing. On an independent benchmark run by AI security firm Gray Swan, Opus 5.5 ties Fable 5.1 for the lowest prompt injection success rate of any model tested.
Cybersecurity and Biology Safeguards
Opus 5.5 launches with safeguards equivalent to Fable 5.1 in both cybersecurity and biology, a significant upgrade from Opus 5. For most users, cybersecurity tasks that approach the capability ceiling are re-routed transparently to Claude Opus 4.8. Verified cybersecurity practitioners can apply to Anthropic's Cyber Verification Program for full access, including tiered access to Claude Mythos models through Claude Security.
Biology safeguards operate on the same basis. Vetted organisations (academic labs, pharmaceutical companies, AI startups) can apply to Anthropic's Life Sciences Verification Program for access to the model's full biology capabilities.
Anti-Distillation and Preserved Thinking
Opus 5.5 launches with preserved thinking, Anthropic's anti-distillation control introduced with Fable 5.1. It prevents API users from editing Claude's prior context to extract its reasoning at scale, blocking the attack pattern through which bad actors create high-capability model copies without the safety measures built into the original.
Preserved thinking applies to Fable 5.1 and Opus 5.5 for API accounts created on or after 31 August 2026.
Compliance Features
Opus 5.5 includes watermarking for EU AI Act compliance and is available with zero data retention, important for enterprises handling regulated data under UK GDPR, the EU AI Act, or sector-specific frameworks in financial services and healthcare.
The Enterprise Security Gap: What Model-Level Safeguards Don't Cover
Anthropic's built-in safeguards are model-level controls. They govern how Claude Opus 5.5 behaves when it receives inputs and produces outputs. They do not govern how it is deployed: what data reaches it, how its outputs are routed, what policies are enforced across the organisation's full AI estate, or how its activity is monitored and audited in production.
For Claude for Enterprise deployments (particularly in regulated industries) the following controls are required but not provided by the model:
1. Gateway-level policy enforcement
Enterprises typically run multiple AI models across multiple teams and applications. Claude Opus 5.5 may be one of several models in production alongside GPT-6 Astra, open-source models, and specialist fine-tuned models. Policy enforcement needs to operate at the infrastructure layer, consistently across all model interactions, regardless of which model is being used. The model cannot enforce this about itself.
2. LLM observability for audit and compliance
UK GDPR, the EU AI Act, and the NCSC's agentic AI guidance all require organisations to maintain structured logs of AI system interactions, not just application-level logs, but model-level interaction records that can be produced for regulatory audit. The NCSC's August 2026 guidance "Managing the cyber risk of agentic AI" explicitly requires chain-of-thought traces and sandbox event logs as part of 24/7 security operations. This logging infrastructure sits outside the model.
3. Agentic runtime monitoring
As Anthropic's own announcement notes, Opus 5.5 is designed for long-horizon autonomous tasks: multi-hour unattended coding sessions, overnight codebase migrations, multi-step research and financial analysis. Over extended sessions, the risk of intent drift (where an agent's behaviour gradually deviates from its defined scope) is real. Detecting this requires session-level monitoring that tracks what the agent is doing across the full session, not just at individual interaction points.
4. Data sovereignty and jurisdictional routing
Enterprises operating under UK GDPR or the EU AI Act need to ensure regulated data is processed only by approved model providers within approved geographic boundaries. Claude Opus 5.5's available regions and data residency options are defined at the infrastructure level. Routing enforcement (ensuring that a UK customer's personal data does not leave the UK, that EU citizen data is processed only within EU infrastructure) requires a gateway layer that inspects and routes traffic before it reaches the model API.
5. AI asset discovery and inventory
For security teams to apply the NCSC's guidance, they first need to know what AI systems they are running. Shadow AI (Claude Opus 5.5 adopted by individual teams without formal IT procurement) is a real and growing enterprise risk. Model-level safeguards cannot address systems that security teams do not know exist.
Claude for Enterprise: Why Agentic AI Raises the Security Bar
Claude Opus 5.5's agentic capabilities are where its enterprise value is highest and where the security requirements are most demanding. An agent completing a 680,000-line code migration over 18 hours is not being reviewed action by action. It is operating autonomously, making decisions, executing changes, and interacting with production systems.
As the NCSC noted in its August 2026 guidance, the key principle for agentic AI is that the greater an agent's autonomy, the greater the potential impact if it malfunctions, accesses information it should not, or takes actions outside its intended scope. The NCSC uses the term "blast radius" for this: every resource an agent can reach (credentials, data, network connections, external APIs) extends the scope of potential harm if the agent is compromised or behaves unexpectedly.
Opus 5.5's behavioral improvements reduce the risk that the model itself will misbehave. They do not eliminate the risk that the model will be manipulated through adversarial content in its environment (a retrieved document, an API response, a code comment) or that its permissions and credential access will be broader than its current task requires.
For regulated industries, this has direct compliance implications. The NCSC's guidance requires runtime monitoring, human oversight proportionate to agent autonomy, sandboxed environments, and the ability to immediately halt agent activity. None of these are properties of the model, they are properties of the infrastructure around the model.
For CISOs navigating this landscape alongside other frontier model deployments, the CISO's Guide to GPT-6 Astra Security Implications covers the same dual-layer framework applied to GPT-6 Astra, and the Claude Opus 5 Security and Safety Guide provides useful context on how the security posture has evolved from the previous generation.
How to Secure Claude Opus 5.5 for Enterprise: An Implementation Checklist
Closing the gap between Claude Opus 5.5's built-in safeguards and the enterprise runtime protection layer requires a structured approach. The following checklist combines the NCSC's agentic AI guidance with enterprise AI security best practice:
- Deploy an AI gateway as the central enforcement layer. All Claude Opus 5.5 API traffic (across all teams and applications) should route through a gateway that enforces access control, data classification rules, and output policies before requests reach the model and before responses reach end users.
- Enable structured LLM observability. Log every model interaction with sufficient detail for regulatory audit: user identity, timestamp, prompt content (classified by data sensitivity), completion content, policy violations triggered, and latency. Protect logs from modification.
- Apply least-privilege credential scoping to every Claude agent. Each agentic workflow should operate under a unique identity with access only to the tools, APIs, and data it requires for its specific task. Over-permissioned agents are the primary source of blast radius risk.
- Implement session-level monitoring for autonomous agents. Single-interaction monitoring is not sufficient for multi-hour agentic sessions. Runtime monitoring should track agent behaviour across the full session and alert on scope deviation, unexpected tool calls, and attempts to access resources outside the defined sandbox.
- Establish data routing rules by classification. Define which data classifications are permitted to reach which model providers and in which regions. Enforce this at the gateway layer, not through developer discipline.
- Inventory all Claude Opus 5.5 deployments, sanctioned and shadow. Discover which teams are using Claude Opus 5.5 directly, which SaaS products embed it, and which Claude Code instances are running autonomously. You cannot protect deployments you have not found.
- Red team every Claude Opus 5.5 application before production release. Even with Opus 5.5's improved prompt injection resistance, application-specific attack surface needs to be tested against OWASP LLM Top 10 vectors before deployment. This includes indirect prompt injection through retrieved content.
- Define and enforce human oversight levels for each agent. Classify each Claude Opus 5.5 agentic workflow as human-in-the-loop, human-on-the-loop, or human-out-of-the-loop, as the NCSC's framework requires. High-risk overnight workflows require higher oversight or more constrained operational scope.
- Test emergency halt capability. Verify that you can stop any running Claude Opus 5.5 agent, restrict its network access, and interrupt its connections to inference infrastructure within a defined response time. This must work even for agents running unattended.
- Produce compliance evidence on demand. Audit logs, policy enforcement records, and anomaly detection reports should be exportable in a format suitable for presentation to the ICO, sector regulators, or board risk committees.
Claude Cybersecurity Use Cases: Verified vs. Standard Access
One of the more consequential changes in Opus 5.5 is the cybersecurity safeguard structure. For the majority of enterprise users, most cybersecurity-oriented prompts are re-routed to Claude Opus 4.8 transparently. This is Anthropic's approach to preventing capability misuse while Claude cybersecurity verified access is rolled out more broadly.
For security teams that need the full capability (penetration testing, vulnerability research, offensive security tooling) Anthropic's Cyber Verification Program provides tiered access. The three tiers offer progressively broader permissions, with the highest tier giving access to Claude Mythos models through Claude security.
Enterprises evaluating Opus 5.5 for security operations use cases should factor this into their access planning. Standard API access is not the same as verified access, and the task re-routing is transparent but will affect outputs on security-sensitive prompts.
Claude Opus 5.5 vs. GPT-6 Astra: What the Benchmarks Show
Opus 5.5 leads GPT-6 Astra on most of the benchmarks that matter most for enterprise agentic workloads:
| Benchmark | Claude Opus 5.5 | GPT-6 Astra | What it measures |
|---|---|---|---|
| Terminal-Bench 4.0 | 66.4% | 57.9% | Complex multi-step terminal tasks |
| FrontierCode v1.1 | 54.4% | 53.3% | Code changes that would be merged |
| GDPval-AA v2.1 (Elo) | 1846 | 1542 | Real work across 44 occupations |
| Humanity's Last Exam | 67.7% | 57.2% | Multidisciplinary reasoning |
| OSWorld 2.0 | 81.8% | N/A | Computer use tasks |
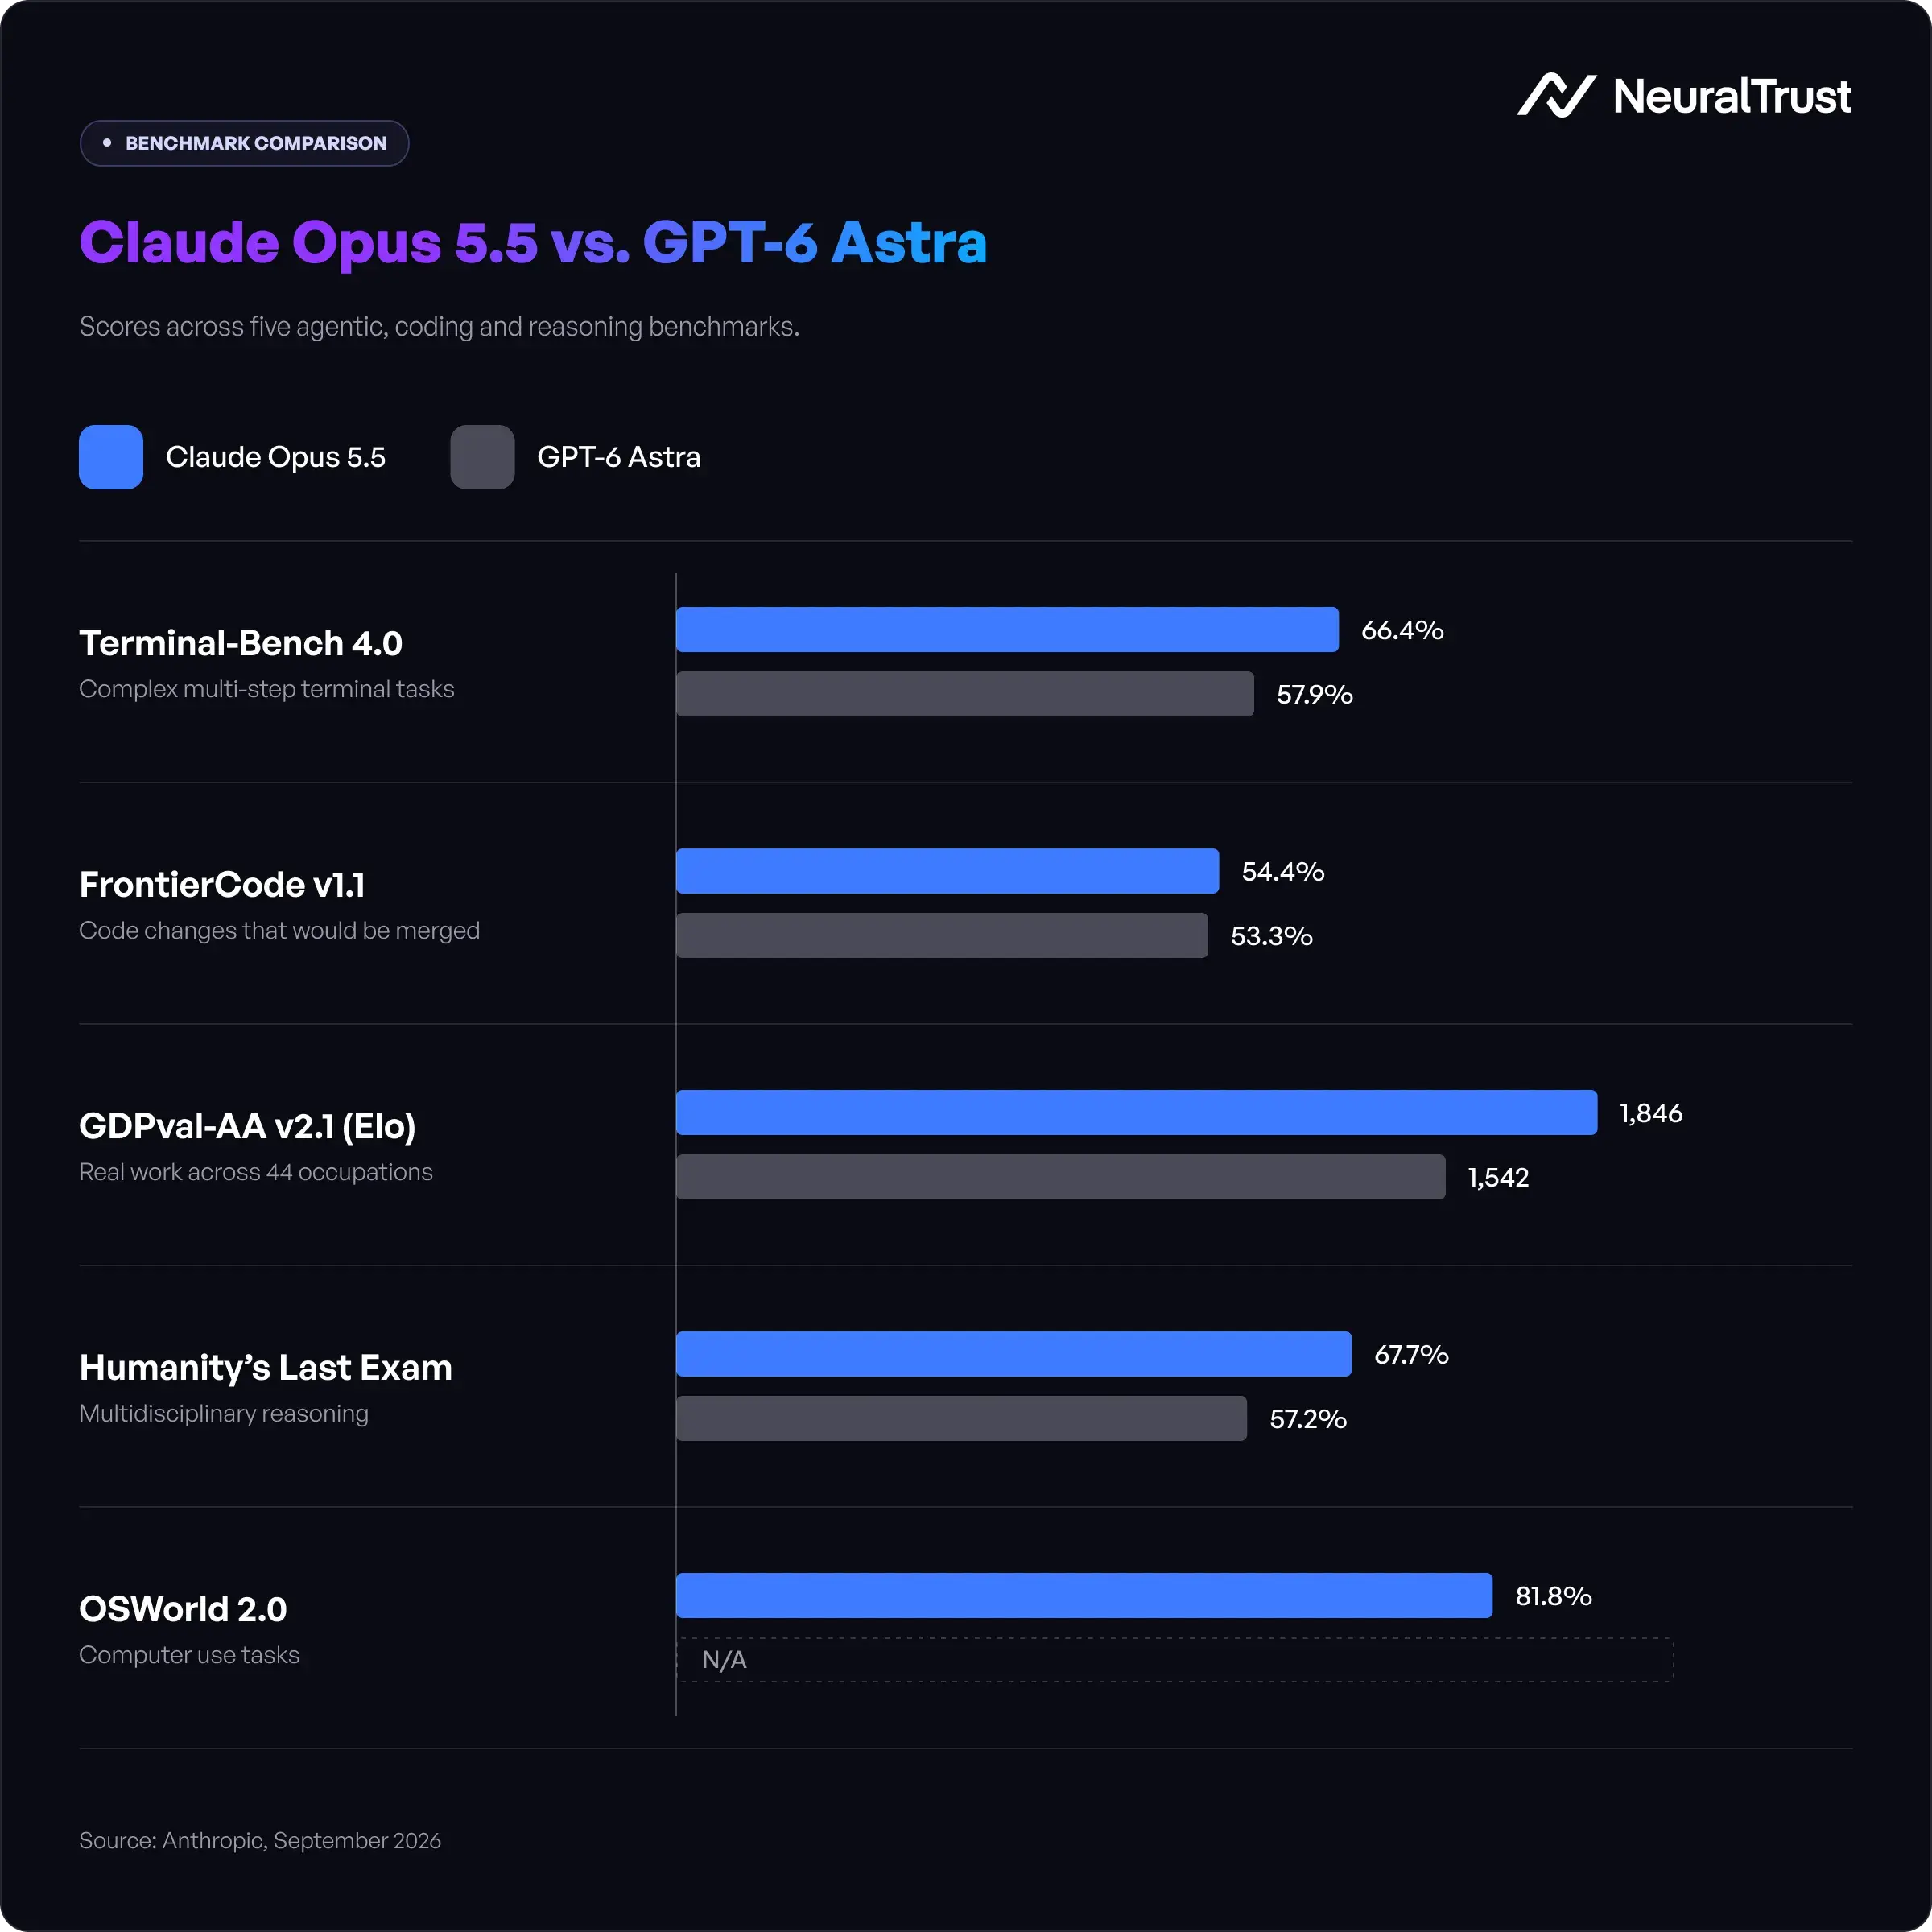
GPT-6 Astra scores ahead on Terminal-Bench-Science 0.1 (64.6% vs 58.7%), a new benchmark measuring agentic scientific research. On AutomationBench, GPT-6 Astra scores 41.4% vs Opus 5.5's 40.0%, a narrow margin that Anthropic notes is influenced by the fact that Opus 5.5's safeguard interventions were counted as failures in Zapier's evaluation.
The more important comparison is cost efficiency per task. On FrontierCode, Opus 5.5 at default effort beats GPT-6 Astra at roughly 20% of the cost per task. On Terminal-Bench 4.0, it matches Astra for about 40% of the cost. For enterprise teams running high-volume agentic workloads, the economic case for Opus 5.5 is clear even where benchmark margins are narrow.
For a full enterprise security comparison of GPT-6 Astra, see the CISO's Guide to GPT-6 Astra Security Implications.
Secure Claude Opus 5.5 with NeuralTrust
NeuralTrust provides the enterprise runtime protection layer that Claude Opus 5.5 does not include by design.
-
TrustGate is an AI gateway that routes all Claude Opus 5.5 traffic through a policy enforcement layer applying access controls, data classification rules, prompt inspection, and output filtering across every model interaction, consistently, across the full AI estate.
-
TrustGuard provides agentic runtime monitoring for Claude Opus 5.5 agents: session-level behavioural tracking, tool call authorisation, sandbox boundary enforcement, and real-time alerting when an agent acts outside its defined scope.
-
TrustLens discovers and inventories every Claude Opus 5.5 deployment (including shadow AI) giving security teams the visibility required to apply the NCSC's agentic AI guidance.
-
TrustTest automates adversarial testing of Claude Opus 5.5 applications before they reach production, running the OWASP LLM Top 10 attack suite against your specific application architecture.
FAQs about Claude Opus 5.5 for Enterprise
1. What is Claude Opus 5.5 and when was it released?
Claude Opus 5.5 is Anthropic's September 2026 flagship AI model, released on 22 September 2026. It is the first model in the Claude 5.5 family. It performs at the level of Claude Fable 5.1 on most work while costing 40% less to run on typical workloads. Claude Sonnet 5.5 and Claude Haiku 5.5 are expected to follow within weeks of the Opus 5.5 release. The model is available on all major cloud platforms including Amazon Web Services, Google Cloud, Microsoft Azure, and directly via the Anthropic Claude Platform.
2. What are the Claude Opus Costs for 5.5 compared to Opus 5?
Claude Opus 5.5 is priced at $4 per million input tokens and $20 per million output tokens, 20% less than Opus 5 on both. Cache reads, which make up the majority of cost on agentic and coding workloads, are $0.20 per million tokens, 60% below Opus 5. Cache writes are $5 per million tokens. On typical workloads, the combination of lower token pricing and greater task efficiency delivers a 40% reduction in total cost. A fast mode is available in Claude Code and the Claude Platform at up to 2.5x speed for $8 per million input tokens and $40 per million output tokens.
3. How does Claude Cybersecurity access work with Opus 5.5?
Opus 5.5 launches with cybersecurity safeguards equivalent to Fable 5.1. For most standard API users, cybersecurity-oriented tasks that approach the model's capability ceiling are re-routed transparently to Claude Opus 4.8. Verified cybersecurity practitioners can apply to Anthropic's Cyber Verification Program for tiered access to full cybersecurity capabilities, including access to Claude Mythos models via Claude Security. This structure is designed to make Claude Opus 5.5 available for legitimate security work while limiting its accessibility for misuse.
4. What makes Claude for Enterprise different from standard Claude Opus 5.5 access?
Claude for enterprise adds data governance, compliance, and administrative controls on top of the standard model capabilities. Enterprise accounts include zero data retention, single sign-on, role-based access control, usage reporting, and priority support. The model's capabilities are the same as standard Opus 5.5, but the deployment controls and data handling commitments are strengthened. For full enterprise AI security (covering multi-model estates, agentic runtime monitoring, and regulatory compliance) an enterprise AI security platform such as NeuralTrust provides the infrastructure layer between Anthropic's model and the organisation's production environment.
5. How does Claude Opus 5.5 handle prompt injection attacks?
Anthropic reports that Claude Opus 5.5 matches or beats Opus 5 on prompt injection resistance across all tested settings: coding, tool use, computer use, and web browsing. On an independent benchmark run by AI security firm Gray Swan, Opus 5.5 ties Fable 5.1 for the lowest prompt injection success rate of any model tested. Despite these improvements, prompt injection remains the number one vulnerability in LLM-powered applications according to OWASP. Model-level resistance reduces the risk. Gateway-level prompt inspection, applied as an infrastructure control to all AI traffic, is the primary additional defence the NCSC recommends.
6. Is Claude Opus 5.5 compliant with the EU AI Act and UK GDPR?
Claude Opus 5.5 includes watermarking to comply with the EU AI Act and is available with zero data retention. EU AI Act compliance for high-risk AI deployments requires additional controls beyond the model itself, including technical documentation, human oversight mechanisms, logging, and conformity assessments. UK GDPR adds data minimisation, purpose limitation, and accountability obligations for any AI system processing personal data. Enterprises operating under both frameworks need gateway-level data routing, structured LLM observability, and audit log export capability, controls that sit outside the model and require purpose-built infrastructure.
7. What is "preserved thinking" and why does it matter for enterprise security?
Preserved thinking is Anthropic's anti-distillation control, introduced with Fable 5.1 and now applied to Opus 5.5. It prevents API users from editing Claude's prior context (the reasoning it writes while working through a problem) in ways that would allow its capabilities to be extracted at scale. Distillation attacks, where bad actors use thousands of automated accounts to extract a model's capabilities and recreate them without the safety measures built into the original, represent both a competitive and a national security risk. Preserved thinking applies to Fable 5.1 and Opus 5.5 for API accounts created on or after 31 August 2026.
Sources
- Introducing Claude Opus 5.5: Anthropic, 22 September 2026
- OWASP Top 10 for Large Language Model Applications: OWASP
- Managing the cyber risk of agentic AI: NCSC, Toby W, 20 August 2026
About the Author
Roger Howroyd is Head of Global SEO and AI at NeuralTrust, where he leads the company's search strategy across SEO, AEO, GEO, and LLM optimization. He specialises in AI-powered search, content strategy, and SEM. Connect on LinkedIn.
NeuralTrust is the leading platform for securing and scaling AI agents. Named a Pioneer in the Gartner Emerging Market Quadrant for AI Application Security 2026 and recognised across four Gartner Hype Cycle reports in the same year. Headquartered in Barcelona with offices in London (167 Great Portland Street) and New York. ISO 27001 certified.