Last updated: September 2026
Is Claude better than ChatGPT in 2026?
In the Claude vs ChatGPT matchup, the answer depends on the job. Anthropic's Claude Opus 5.5 leads on agentic coding and professional knowledge work while costing 60% less per API token. OpenAI's ChatGPT, whose top plans run GPT-6 Astra, leads on advanced math and science reasoning and offers native image generation. For enterprises running either one in production, the bigger question is how you secure it.
Both vendors shipped a new flagship in September 2026: OpenAI launched GPT-6 Astra on September 3, and Anthropic followed with Claude Opus 5.5 on September 22. This guide compares them with the latest published benchmarks, current pricing, privacy terms and security data, so you can choose with evidence instead of hype.
TL;DR: Key Takeaways
- Coding and agents: Claude Opus 5.5 scores 66.4% on Terminal-Bench 4.0 versus 57.9% for GPT-6 Astra, according to Anthropic's launch benchmarks.
- Math and science: GPT-6 Astra posts 97.6% on FrontierMath Tier 4 and 96.0% on GPQA Diamond, per OpenAI.
- Overall: independent aggregator BenchLM scores the two flagships 88.47 (Astra) and 88.45 (Opus 5.5), a statistical tie.
- API cost: Opus 5.5 costs $4/$20 per million input/output tokens. GPT-6 Astra costs $10/$50, making Claude 60% cheaper per token.
- Subscriptions: both start at $20 per month for individuals. ChatGPT adds a cheaper $8 Go tier and has a far larger user base (900 million weekly users).
- Security: in Gray Swan's indirect prompt injection tests, attackers broke GPT-6 Astra in 8.5% of scenarios. Anthropic reports Opus 5.5 ties for the lowest prompt injection success rate of any model tested.
At a Glance: Key Differences in 2026
| Claude (Anthropic) | ChatGPT (OpenAI) | |
|---|---|---|
| Flagship model | Claude Opus 5.5 (Sept 22, 2026) | GPT-6 Astra (Sept 3, 2026) |
| Other models | Fable 5.1, Sonnet, Haiku | GPT-6 Sol and Luna; GPT-5.6 Luna, Terra and Sol |
| Context window (API) | 1M tokens | 1M tokens |
| API price (input/output per 1M tokens) | $4 / $20 | $10 / $50 |
| Individual plans | Free, Pro ($20), Max (from $100) | Free, Go ($8), Plus ($20), Pro ($100 or $200) |
| Team plans | $25 per seat monthly ($20 annual) | $25 per seat monthly ($20 annual) |
| Native image generation | No | Yes |
| Coding agent | Claude Code | Codex |
| Best for | Agentic coding, long documents, knowledge work | Math and science, multimodal creation, broad ecosystem |
What Are Claude and ChatGPT in 2026?
Claude and ChatGPT are general-purpose AI assistants, each built on a family of large language models. Claude is made by Anthropic and runs on models such as Claude Opus 5.5. ChatGPT is made by OpenAI and runs on models such as GPT-6 Astra and GPT-5.6. Both are available as consumer apps, team workspaces and developer APIs.
The models behind Claude
Anthropic released Claude Opus 5.5 on September 22, 2026. Anthropic describes it as matching its larger Fable 5.1 model on most work while costing less to run, and it supports a 1 million token context window with up to 128,000 output tokens per request, VentureBeat reports. Opus is available on paid plans, while free users get the lighter Sonnet and Haiku models, according to Claude's pricing page.
For a security-focused review of the new model, see our analysis of Claude Opus 5.5 enterprise security safeguards and gaps.
The models behind ChatGPT
OpenAI launched GPT-6 Astra on September 3, 2026, in the API and in ChatGPT. OpenAI's Help Center says "GPT-6 Pro, powered by GPT-6 Astra" is available on the Pro, Business and Enterprise plans, while Plus users get GPT-5.6 Sol and the faster GPT-6 Sol and GPT-6 Luna models, added on September 22. Free users chat with GPT-5.6 Luna. According to Vellum's benchmark review, Astra is also a 1 million token context model and holds 96.3% accuracy at the 512K to 1M range.
What this means for buyers: at the flagship level, the two products are closer than ever. The practical differences show up in specific workloads, price and tooling.
Claude vs ChatGPT Benchmarks: Who Wins on Performance?
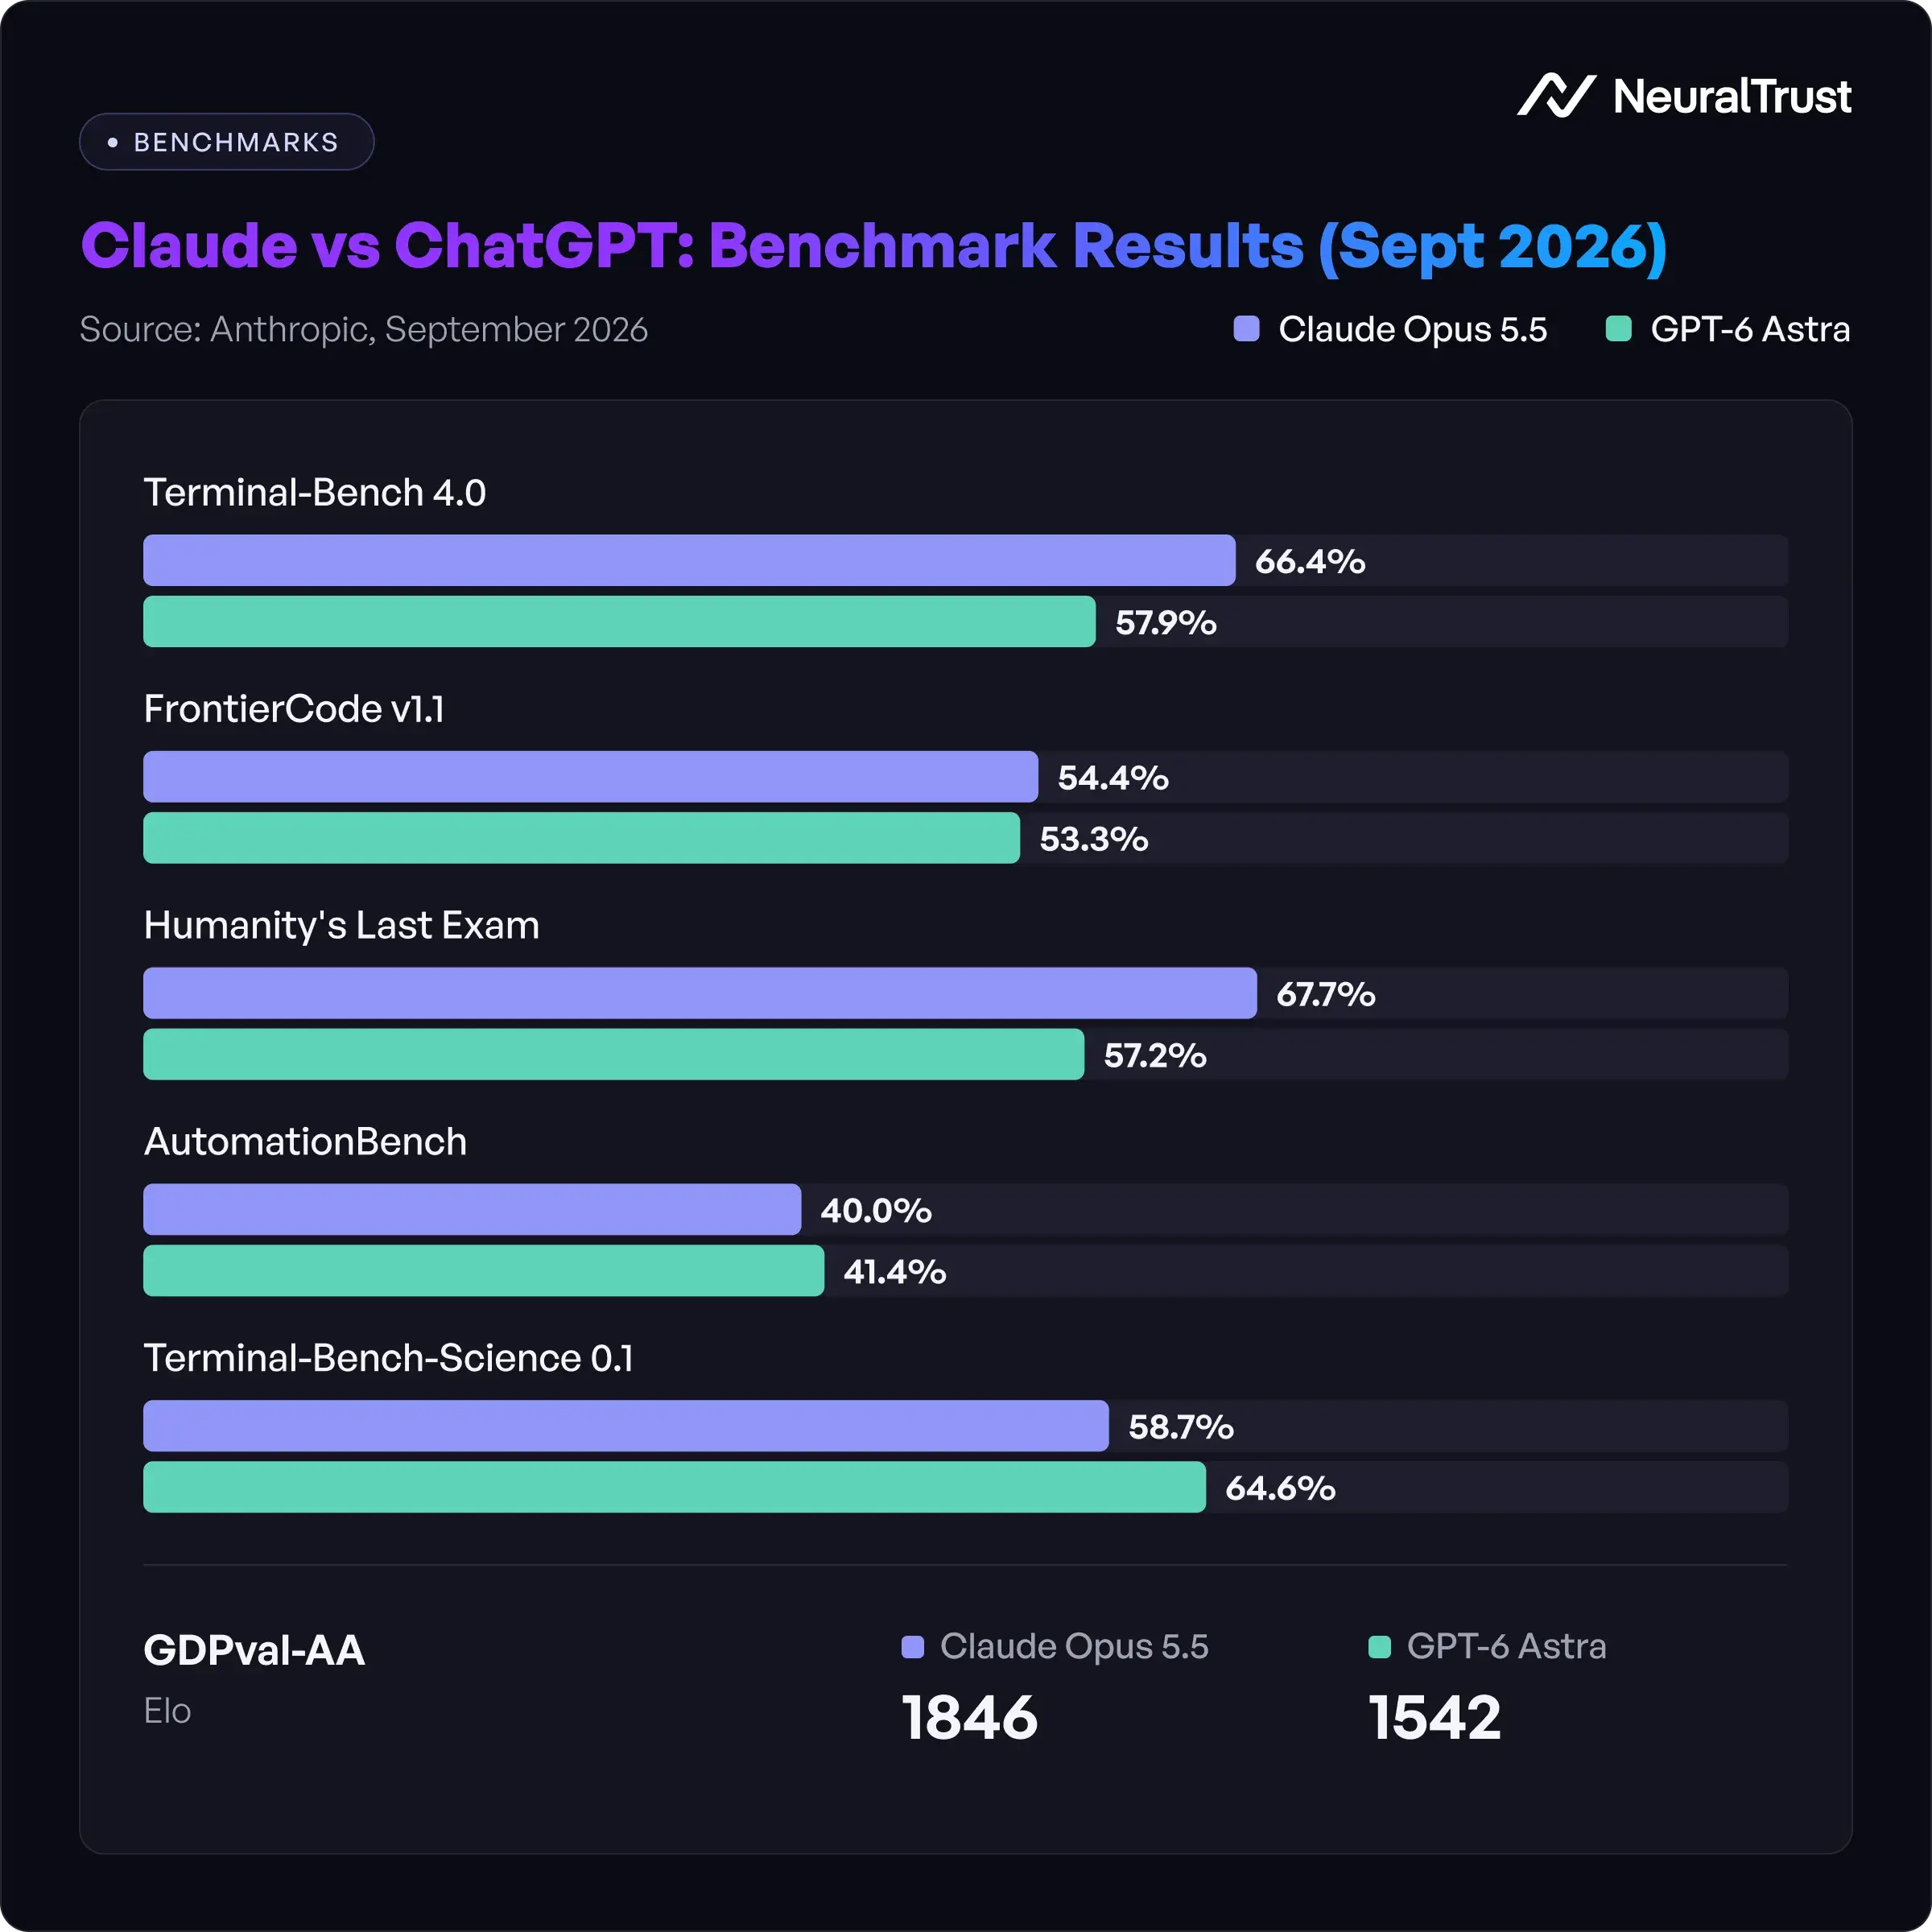
Claude Opus 5.5 wins more of the shared benchmarks, especially agentic coding and knowledge work, while GPT-6 Astra wins on science workflows and some automation tasks. Across aggregated leaderboards the two are effectively tied. The table below uses the only side-by-side figures both models appear in, published by Anthropic on September 22, 2026.
| Benchmark (what it measures) | Claude Opus 5.5 | GPT-6 Astra | Leader |
|---|---|---|---|
| Terminal-Bench 4.0 (agentic coding in a terminal) | 66.4% | 57.9% | Claude |
| FrontierCode v1.1 (work on large codebases) | 54.4% | 53.3% | Claude (narrow) |
| GDPval-AA v2.1 (professional tasks across 44 occupations, Elo) | 1846 | 1542 | Claude |
| Humanity's Last Exam (expert-level questions) | 67.7% | 57.2% | Claude |
| AutomationBench (business workflow automation) | 40.0% | 41.4% | ChatGPT (narrow) |
| Terminal-Bench-Science 0.1 (scientific computing tasks) | 58.7% | 64.6% | ChatGPT |
Source: Anthropic, Introducing Claude Opus 5.5, September 2026. Vendor-reported results.
Where GPT-6 Astra leads
OpenAI reports scores that Anthropic did not publish for Opus 5.5. According to OpenAI (2026), GPT-6 Astra reaches 97.6% on FrontierMath Tier 4 and 96.0% on GPQA Diamond, which Vellum calls "the highest published score" on that graduate-level science test. If your work is research mathematics or advanced science Q&A, Astra has the stronger public record.
How to read vendor benchmarks
Every number above comes from the vendors themselves, and each lab picks the tests it presents. Independent aggregation helps: BenchLM's September 2026 ranking places GPT-6 Astra at 88.47 and Claude Opus 5.5 at 88.45, with overlapping confidence intervals. Artificial Analysis gives Claude Opus 5.5 a score of 58 on its Intelligence Index v4.3.2 and notes that the cost of running its test suite varies up to 11x across Opus 5.5 configurations, a reminder that reasoning effort settings change both quality and price. In practice, the "best model" depends on your workload, so run a pilot on your own tasks before committing.
How we compared Claude and ChatGPT
This comparison uses only published, dated sources: the vendors' launch announcements and system cards, independent aggregators such as BenchLM and Artificial Analysis, and external red-team results from Gray Swan. Where the two labs report different benchmarks, we say so instead of mixing numbers from different test setups. Prices reflect the US list prices shown on each vendor's site in September 2026. We did not run private tests, so treat every score as a starting point for your own evaluation rather than a final verdict.
Coding: Claude Code vs Codex
Claude is the stronger choice for agentic coding in 2026. Opus 5.5 leads GPT-6 Astra by 8.5 points on Terminal-Bench 4.0 and edges it on FrontierCode, and it scores 57.8% on CursorBench 4.0, a test OpenAI's model does not appear in. ChatGPT remains a capable coding partner, particularly for tightly specified tasks.
Both companies now ship dedicated coding agents:
- Claude Code runs in the terminal, IDE and desktop app, and is included from the Claude Pro plan upward.
- Codex is OpenAI's coding agent, included with ChatGPT Plus and above.
The benchmark gap matters most for long, multi-step work: refactors across many files, debugging sessions that need a terminal, and tasks where the agent has to plan before it edits. For quick snippets and well-defined functions, both tools perform well.
How to run a fair coding pilot
Public benchmarks rarely match your codebase, so a two-week pilot tells you more than any leaderboard. A simple structure works for most teams:
- Pick 20 to 30 real tickets from your backlog, mixing bug fixes, small features and one or two refactors.
- Run each ticket through both agents with the same instructions, repository access and time limit.
- Score the output on tests passed, review comments needed and time to merge, not on how confident the agent sounded.
- Track cost per merged change, including retries, since a cheaper token price can be offset by extra attempts.
- Log every tool call and file change so your security team can see what each agent actually did with its permissions.
What this means for engineering leaders: if coding agents will touch production repositories, weigh security alongside accuracy. An agent with shell access and repository credentials widens your attack surface, whichever model powers it.
Reasoning, Math and Research
GPT-6 Astra is the better pick for math-heavy and scientific reasoning, while Claude Opus 5.5 is stronger on broad expert knowledge and long-document analysis. The split is visible in the numbers: Astra leads Terminal-Bench-Science (64.6% vs 58.7%) and posts near-perfect FrontierMath results, while Opus 5.5 leads Humanity's Last Exam by 10.5 points.
For analysts and knowledge workers, GDPval-AA is the most relevant signal because it scores realistic professional deliverables. Opus 5.5's Elo of 1846 versus Astra's 1542 is the widest gap in the shared results. Anthropic also reports that 16 of 18 Opus 5.5 financial analysis reports passed its quality threshold without fabricated figures or quotations, according to VentureBeat.
Long context and document work
Both flagships now accept 1 million tokens of context through the API, enough for several full contracts, a large codebase or a year of meeting notes in a single request. Claude Opus 5.5 can also return up to 128,000 output tokens synchronously and up to 300,000 through Anthropic's batch API, which helps with long reports and large code changes. Vellum measured GPT-6 Astra at 96.3% accuracy in the 512K to 1M token range, a large jump over its predecessor. For legal, finance and compliance teams, the practical takeaway is that context size is no longer the deciding factor. Retrieval quality, citation accuracy and how your data is protected inside that context matter more.
On hallucinations, OpenAI says GPT-6 Astra reproduced previously reported ChatGPT errors "much less often" than earlier models, The Decoder notes. Neither vendor claims zero hallucinations, so human review stays essential for anything customer-facing or regulated.
Claude vs ChatGPT Pricing: Subscriptions and API Costs
For individuals, Claude and ChatGPT cost the same at the standard tier: $20 per month. ChatGPT offers more entry points, including an $8 Go plan. For developers, Claude Opus 5.5 is 60% cheaper per token than GPT-6 Astra.
Subscription plans
| Plan level | Claude | ChatGPT |
|---|---|---|
| Free | $0 (Sonnet and Haiku models) | $0 (GPT-5.6 Luna, ads in the US) |
| Entry | None | Go: $8/month |
| Standard | Pro: $20/month ($17/month annual) | Plus: $20/month (GPT-5.6 Sol, GPT-6 Sol and Luna) |
| Power user | Max: from $100/month (5x or 20x Pro usage) | Pro: $100 (5x) or $200/month (20x), includes GPT-6 Astra |
| Team | $25/seat monthly or $20 annual | Business: $25/seat monthly or $20 annual |
| Enterprise | $20/seat/month plus usage | Custom pricing |
Sources: Claude pricing; CloudZero's 2026 ChatGPT pricing guide.
API pricing
| Per 1M tokens | Claude Opus 5.5 | GPT-6 Astra |
|---|---|---|
| Input | $4 | $10 |
| Output | $20 | $50 |
| Fast mode | $8 / $40 | 2x standard price |
| Cached input reads | $0.20 | Not published at launch |
Here is what that difference looks like at scale. A workload of 10 million input tokens and 2 million output tokens per month costs about $80 on Claude Opus 5.5 and $200 on GPT-6 Astra. At enterprise volumes, that gap compounds quickly.
One caveat: price per token is not price per task. A model that finishes a task in fewer steps or tokens can be cheaper overall, so measure cost per completed task in your own pilot.
Features and Ecosystem
ChatGPT has the broader consumer feature set and a much larger user base, while Claude focuses on work tools such as coding, documents and agents. The clearest single difference: ChatGPT generates images natively and Claude does not.
| Feature | Claude | ChatGPT |
|---|---|---|
| Native image generation | No | Yes (all tiers, limited on Free) |
| Voice conversations | Yes | Yes |
| Memory across chats | Yes | Yes |
| Deep research | Yes | Yes |
| Agent that acts in a browser or desktop | Claude in Chrome, Cowork | ChatGPT Agent |
| Coding agent | Claude Code | Codex |
| Visual design tools | Claude Design | Image generation |
Scale is ChatGPT's biggest structural advantage. According to Wikipedia's ChatGPT entry, ChatGPT reached 900 million weekly active users in February 2026. That reach means more integrations, more community knowledge and faster feedback loops.
Usage limits are the other practical difference. Both vendors cap how much you can use their top models on each plan, and the caps change often. If your team relies on the flagship model all day, budget for the power-user tiers (Claude Max or ChatGPT Pro) or move heavy workloads to the API, where you pay per token instead.
Claude's advantage is depth in professional workflows. Anthropic has built Claude Code, Cowork and Claude Design around getting work done inside real files and tools, which suits teams that care more about output quality than breadth of features.
Enterprise Privacy and Data Controls
On business plans, neither Claude nor ChatGPT trains on your data by default. Both offer admin controls, SSO and retention settings, so the choice here comes down to specific compliance needs rather than a clear winner.
| Control | Claude (Team/Enterprise) | ChatGPT (Business/Enterprise) |
|---|---|---|
| Training on business data | No, by default | No, by default |
| Data retention | Custom retention on Enterprise | Admin-controlled; deleted chats removed within 30 days on Business |
| Identity | SSO, SCIM, role-based access | SSO, admin controls |
| Audit and compliance | Audit logs, compliance API | SOC 2 Type 2 |
| Health data | HIPAA-ready option | HIPAA BAA for API customers |
Sources: Claude pricing; OpenAI enterprise privacy.
Consumer plans work differently. Anthropic's privacy center says consumer chats are used for training only if you allow it, and Incognito chats are never used. OpenAI lets consumers turn off model training in ChatGPT's data controls. Either way, employees using personal accounts for company work sit outside your contractual protections, which is why shadow AI is a governance issue, not a preference.
Security and Governance: Deploying Claude and ChatGPT in the Enterprise
Model-level safety has improved sharply in both products, but neither model is secure enough on its own for production agents. The main risk is prompt injection: malicious instructions hidden in emails, documents or web pages that hijack what the model does next. The OWASP Top 10 for LLM Applications ranks prompt injection as risk number one (LLM01).
What the security data shows
- GPT-6 Astra: OpenAI's system card reports a 99.99% defense rate against direct injection attempts. In Gray Swan's external test of 1,810 indirect attacks, attackers still succeeded in 8.5% of scenarios, down from 27.0% for GPT-5.6 Sol. On the same test, Claude Opus 5 came in at 4.8%, The Decoder reports.
- Adaptive attacks: when attackers adjust tactics over several turns, Astra's defense rate against jailbreaks drops to about 67%, meaning persistent adversaries succeed roughly one time in three.
- Claude Opus 5.5: Anthropic says the new model ties Fable 5.1 for the lowest prompt injection success rate of any model Gray Swan tested, and attempts to circumvent its boundaries about 85% less often than Opus 5.
Claude currently has the edge on injection resistance, but "lower" is not "zero." An attack that works 1 time in 20 will eventually succeed against an agent that processes thousands of documents a day.
Why this decides enterprise rollouts
According to Gartner (2025), over 40% of agentic AI projects will be canceled by the end of 2027, with inadequate risk controls among the three main causes. Most enterprises will also end up using both vendors, often inside the same workflow. That makes vendor-specific safeguards insufficient: you need one set of policies that applies to every model, agent and tool call.
How NeuralTrust secures Claude and ChatGPT
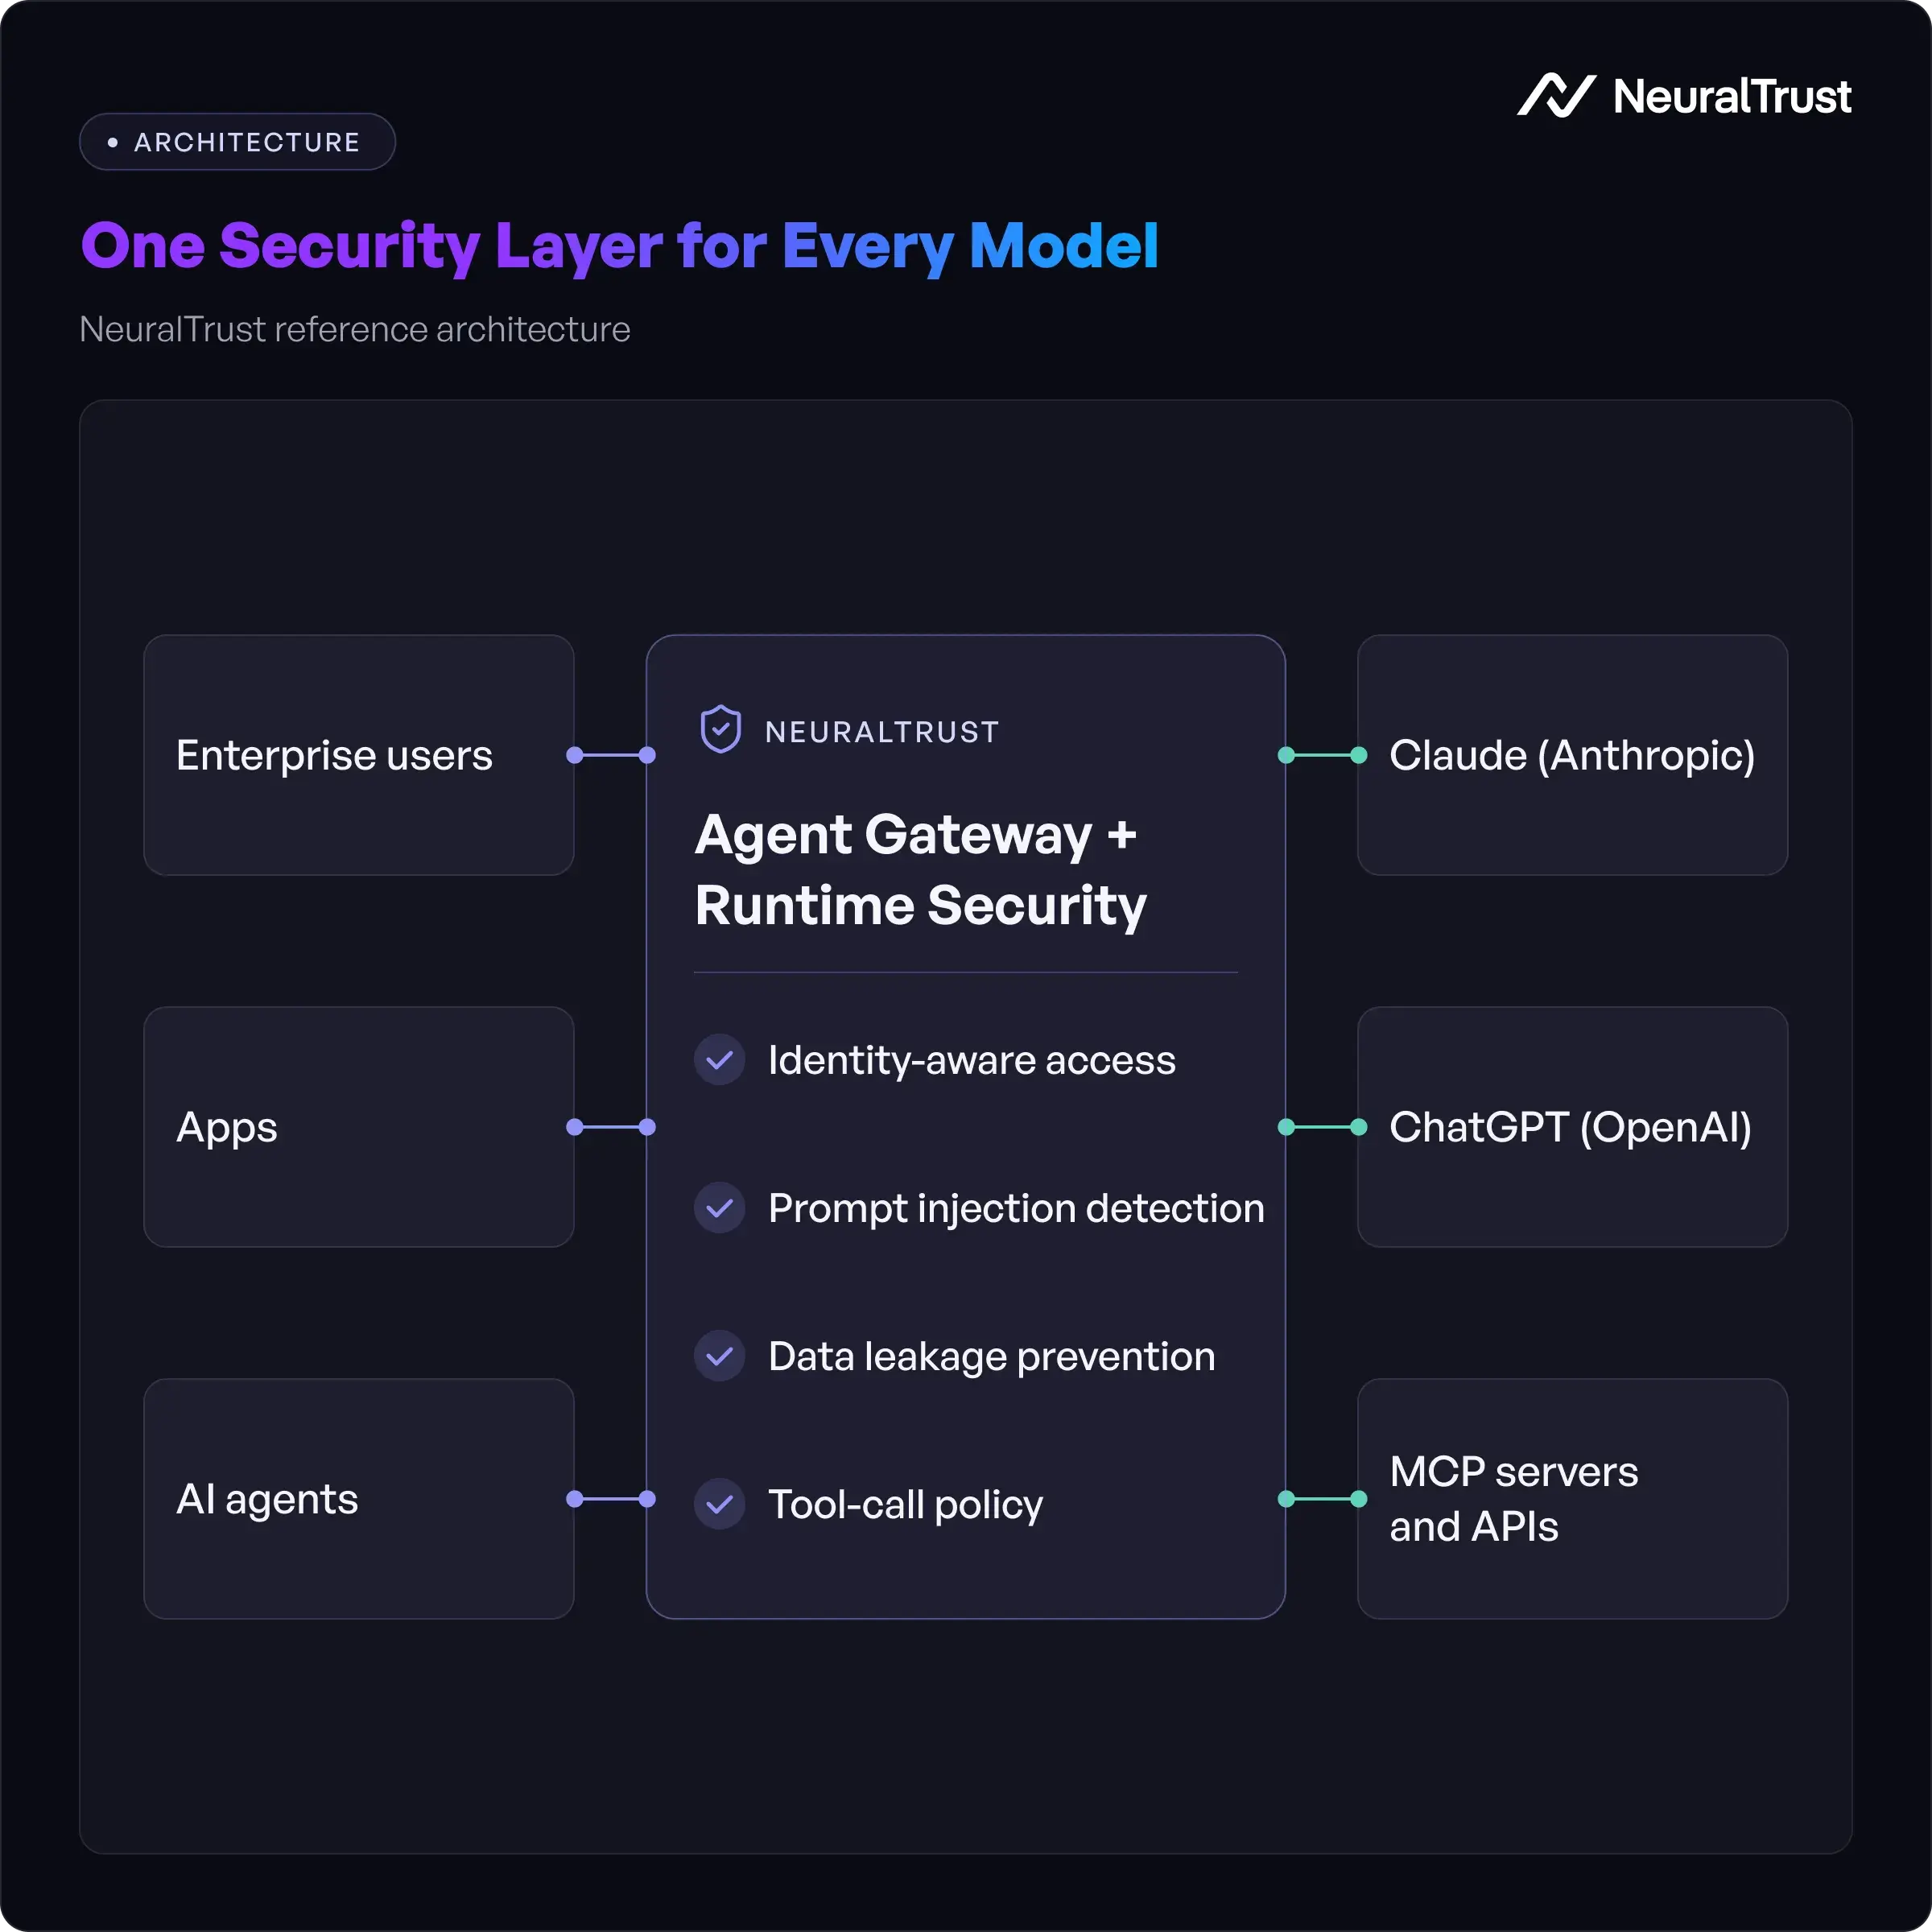
NeuralTrust adds a runtime security layer that works the same way whether a request goes to Claude, ChatGPT or both:
- Agent Gateway (TrustGate): connects agents to models, MCP servers and APIs with identity-aware access control, so every prompt, response and tool call passes one policy point. It ships with 200+ pre-built MCP servers.
- Agent Runtime Security (TrustGuard): inspects interactions in real time to block prompt injection, data leakage and unauthorized tool use before they reach your systems.
- AI Red Teaming (TrustTest): attacks your own deployments with adversarial tests, so you measure injection resistance on your prompts and data, not just on vendor benchmarks.
NeuralTrust was recognized across four Gartner Hype Cycle reports in 2026 in the AI Runtime Defense category. For the OpenAI side specifically, see our CISO's guide to GPT-6 Astra security implications.
Which Should You Choose? Claude or ChatGPT
Choose Claude if your priority is agentic coding, long-document work or API cost. Choose ChatGPT if you need math and science reasoning, image generation or the widest ecosystem. Many teams will use both, which makes a shared security layer more important than the choice itself.
| If you are... | Pick | Why |
|---|---|---|
| A software team running coding agents | Claude | Leads Terminal-Bench 4.0 and FrontierCode; Claude Code included from Pro |
| A researcher in math or science | ChatGPT | Top published FrontierMath and GPQA Diamond scores |
| An analyst producing reports and models | Claude | Largest lead in the shared results on GDPval-AA professional tasks |
| A marketer creating visual content | ChatGPT | Native image generation on every tier |
| A developer optimizing API spend | Claude | $4/$20 vs $10/$50 per million tokens |
| A budget-conscious individual | ChatGPT | $8 Go plan between Free and $20 tiers |
| A CISO approving AI at scale | Both, behind one gateway | Consistent policy, monitoring and injection defense across vendors |
Conclusion
The Claude vs ChatGPT decision in 2026 is closer than any headline suggests. Claude Opus 5.5 is the better value for coding, agents and knowledge work, and it currently resists prompt injection better. GPT-6 Astra leads on math, science and multimodal features, backed by a far larger ecosystem. Pick the model that fits each workload, and secure every one of them the same way.
Secure Claude and ChatGPT in Production with NeuralTrust
Run Claude, ChatGPT or both behind one policy layer with real-time protection for every prompt, response and tool call.
FAQs about Claude vs ChatGPT
1. Is Claude better than ChatGPT?
It depends on the task. Claude Opus 5.5 leads GPT-6 Astra on agentic coding (66.4% vs 57.9% on Terminal-Bench 4.0), expert knowledge and professional work, and costs 60% less per API token. ChatGPT leads on advanced math and science and offers native image generation. Independent aggregate rankings put the two flagships in a statistical tie.
2. Is Claude better than ChatGPT for coding?
Yes, on current benchmarks. Claude Opus 5.5 scores 66.4% on Terminal-Bench 4.0 against 57.9% for GPT-6 Astra, and also leads on FrontierCode. The gap is largest on long, multi-step tasks such as refactors and terminal debugging. For short, well-specified snippets, both assistants perform well.
3. Which is cheaper, Claude or ChatGPT?
For subscriptions, both cost $20 per month at the standard tier, but ChatGPT also offers an $8 Go plan. For APIs, Claude Opus 5.5 costs $4 per million input tokens and $20 per million output tokens, versus $10 and $50 for GPT-6 Astra, which makes Claude about 60% cheaper per token.
4. Can Claude generate images like ChatGPT?
No. ChatGPT includes native image generation on all plans, with limits on the free tier. Claude does not generate images natively. It can create diagrams, charts and designs as code, and Claude Design helps with visual layouts, but for photographic or illustrated images ChatGPT is the better tool.
5. Is Claude or ChatGPT safer for enterprise use?
Both train on business data only if you opt in, and both offer SSO and admin controls. On prompt injection, Claude currently has the edge: Anthropic reports Opus 5.5 ties for the lowest attack success rate in Gray Swan's tests, while attackers broke GPT-6 Astra in 8.5% of scenarios. Neither is safe without a runtime security layer.
6. Do Claude and ChatGPT use my data for training?
On business plans, neither uses your data for training by default. On consumer plans, Anthropic trains on chats only if you allow it and never on Incognito chats, while OpenAI lets you turn off model training in ChatGPT's data controls. Check your settings, especially if employees use personal accounts for work.
7. Can I use Claude and ChatGPT together?
Yes, and many enterprises already do, routing each task to the model that handles it best. The challenge is governance: two vendors mean two sets of controls and logs. An AI gateway that applies the same policies, monitoring and injection defense to both models keeps multi-model use manageable and auditable.
About the Author
Roger Howroyd is Head of Global SEO and AI at NeuralTrust, where he leads the company's search strategy across SEO, AEO, GEO, and LLM optimization. He specializes in AI-powered search, content strategy, and SEM. Connect on LinkedIn.
NeuralTrust is the leading platform for securing and scaling AI agents. Named a Pioneer in the Gartner Emerging Market Quadrant for AI Application Security 2026, recognized across four Gartner Hype Cycle reports in 2026, and featured in the Gartner Market Guide for Guardian Agents 2026, the Gartner Market Guide for AI Gateways 2025 and the KuppingerCole Leadership Compass for Generative AI Defense 2025. Headquartered in Barcelona with offices in London and New York. ISO 27001 certified.
Related articles
- Gemini vs ChatGPT (2026): Benchmarks, Pricing & Verdict
- Claude Code vs Cursor (2026): Benchmarks, Pricing & Security
- Claude Opus 5.5 Enterprise Security: Safeguards & Gaps
- GPT-6 Astra Security Implications: The CISO's Guide
Sources
- Anthropic: Introducing Claude Opus 5.5 (September 2026)
- OpenAI: GPT-6 Astra (September 2026)
- OpenAI: GPT-6 Astra System Card, Prompt Injection (September 2026)
- VentureBeat: Anthropic releases Claude Opus 5.5 (September 2026)
- Vellum: GPT-6 Astra Benchmarks Explained (September 2026)
- BenchLM: ChatGPT vs Claude (September 2026)
- The Decoder: GPT-6 Astra hallucinates less but remains vulnerable to hidden prompt injections (September 2026)
- Claude: Plans and Pricing
- CloudZero: ChatGPT pricing in 2026
- OpenAI: Enterprise privacy
- Anthropic Privacy Center: Is my data used for model training?
- Wikipedia: ChatGPT
- OWASP: LLM01:2025 Prompt Injection
- Gartner: Over 40% of Agentic AI Projects Will Be Canceled by End of 2027 (June 2025)
- Artificial Analysis: Claude Opus 5.5 (September 2026)
- OpenAI Help: GPT-5.6 and GPT-6 Pro in ChatGPT (September 2026)