How do you reduce LLM costs in production? An AI gateway reduces LLM costs by routing each request to the most cost-efficient model that can handle it, caching repeated prompts so identical calls never hit the model twice, enforcing token and rate limits before spend accumulates, and attributing every dollar of AI cost to the team or application that generated it. Without a gateway, LLM spend grows unchecked until it shows up as a surprise on your cloud bill.
TL;DR - Key Takeaways
- LLM costs are infrastructure costs: they need the same centralised controls as compute and storage, which means a gateway layer, not per-app logging
- Intelligent routing directs simple requests to cheaper models and complex ones to capable models, cutting costs without changing application code
- Semantic caching eliminates redundant model calls entirely: if two users ask the same question, only the first call reaches the model
- Token budgets and rate limits cap per-user, per-agent, and per-application spend before it compounds
- Cost attribution by team or application is the prerequisite for any meaningful cost reduction: you cannot cut what you cannot see
- According to Andreessen Horowitz, AI inference costs represent the single largest line item in the AI application stack for most companies scaling beyond prototype
- TrustGate, NeuralTrust's open-source AI gateway, implements all of these mechanisms at the infrastructure layer with no application-level changes required
The LLM Bill Nobody Saw Coming
You shipped the AI feature. Users love it. Then the invoice arrives.
This is the pattern. Teams build LLM-powered features fast, focus on quality and latency, and treat cost as a problem to solve later. Later arrives at scale, and the numbers are hard to explain to a CFO because nobody can tell them which team, which feature, or which prompt is driving the spend.
The problem is structural. Most teams instrument LLM costs at the application level: one app, one API key, one billing line. As soon as you have multiple applications, multiple models, or multiple teams sharing AI infrastructure, per-app instrumentation stops giving you a usable picture. You see total spend but not where it comes from or what to cut.
An AI gateway solves this by moving cost control to the only layer that sees everything: the infrastructure layer between your applications and your model providers.
Why LLM Costs Spiral Without a Gateway
Before looking at solutions, it is worth being precise about what drives LLM spend out of control, because the causes determine which controls actually work.
1. Unrouted requests. Every request goes to the same model regardless of complexity. A simple FAQ answer costs the same as a multi-step reasoning task because nothing in the stack distinguishes between them.
2. Redundant calls. The same or semantically identical prompts hit the model repeatedly. A customer support tool answering "what is your refund policy?" fifty times a day makes fifty model calls when one cached response would do.
3. No per-user or per-agent limits. A single misbehaving agent, a broken retry loop, or a user running unusually long sessions can generate thousands of tokens with no circuit breaker in place.
4. No attribution. Without knowing which team or application generated which spend, cost reduction conversations are guesswork. You can lower the overall bill but not target the specific cause.
5. Overpaying for model capability. Most production AI workloads are a mix of simple and complex tasks, but without routing logic, all of them pay the price of the most capable (and expensive) model in the stack.
An AI gateway addresses all five. Not by changing your applications, but by adding a control layer that your applications already route through.
How an AI Gateway Cuts LLM Costs: The Five Mechanisms
1. Intelligent Routing (Cost-Based Model Selection)
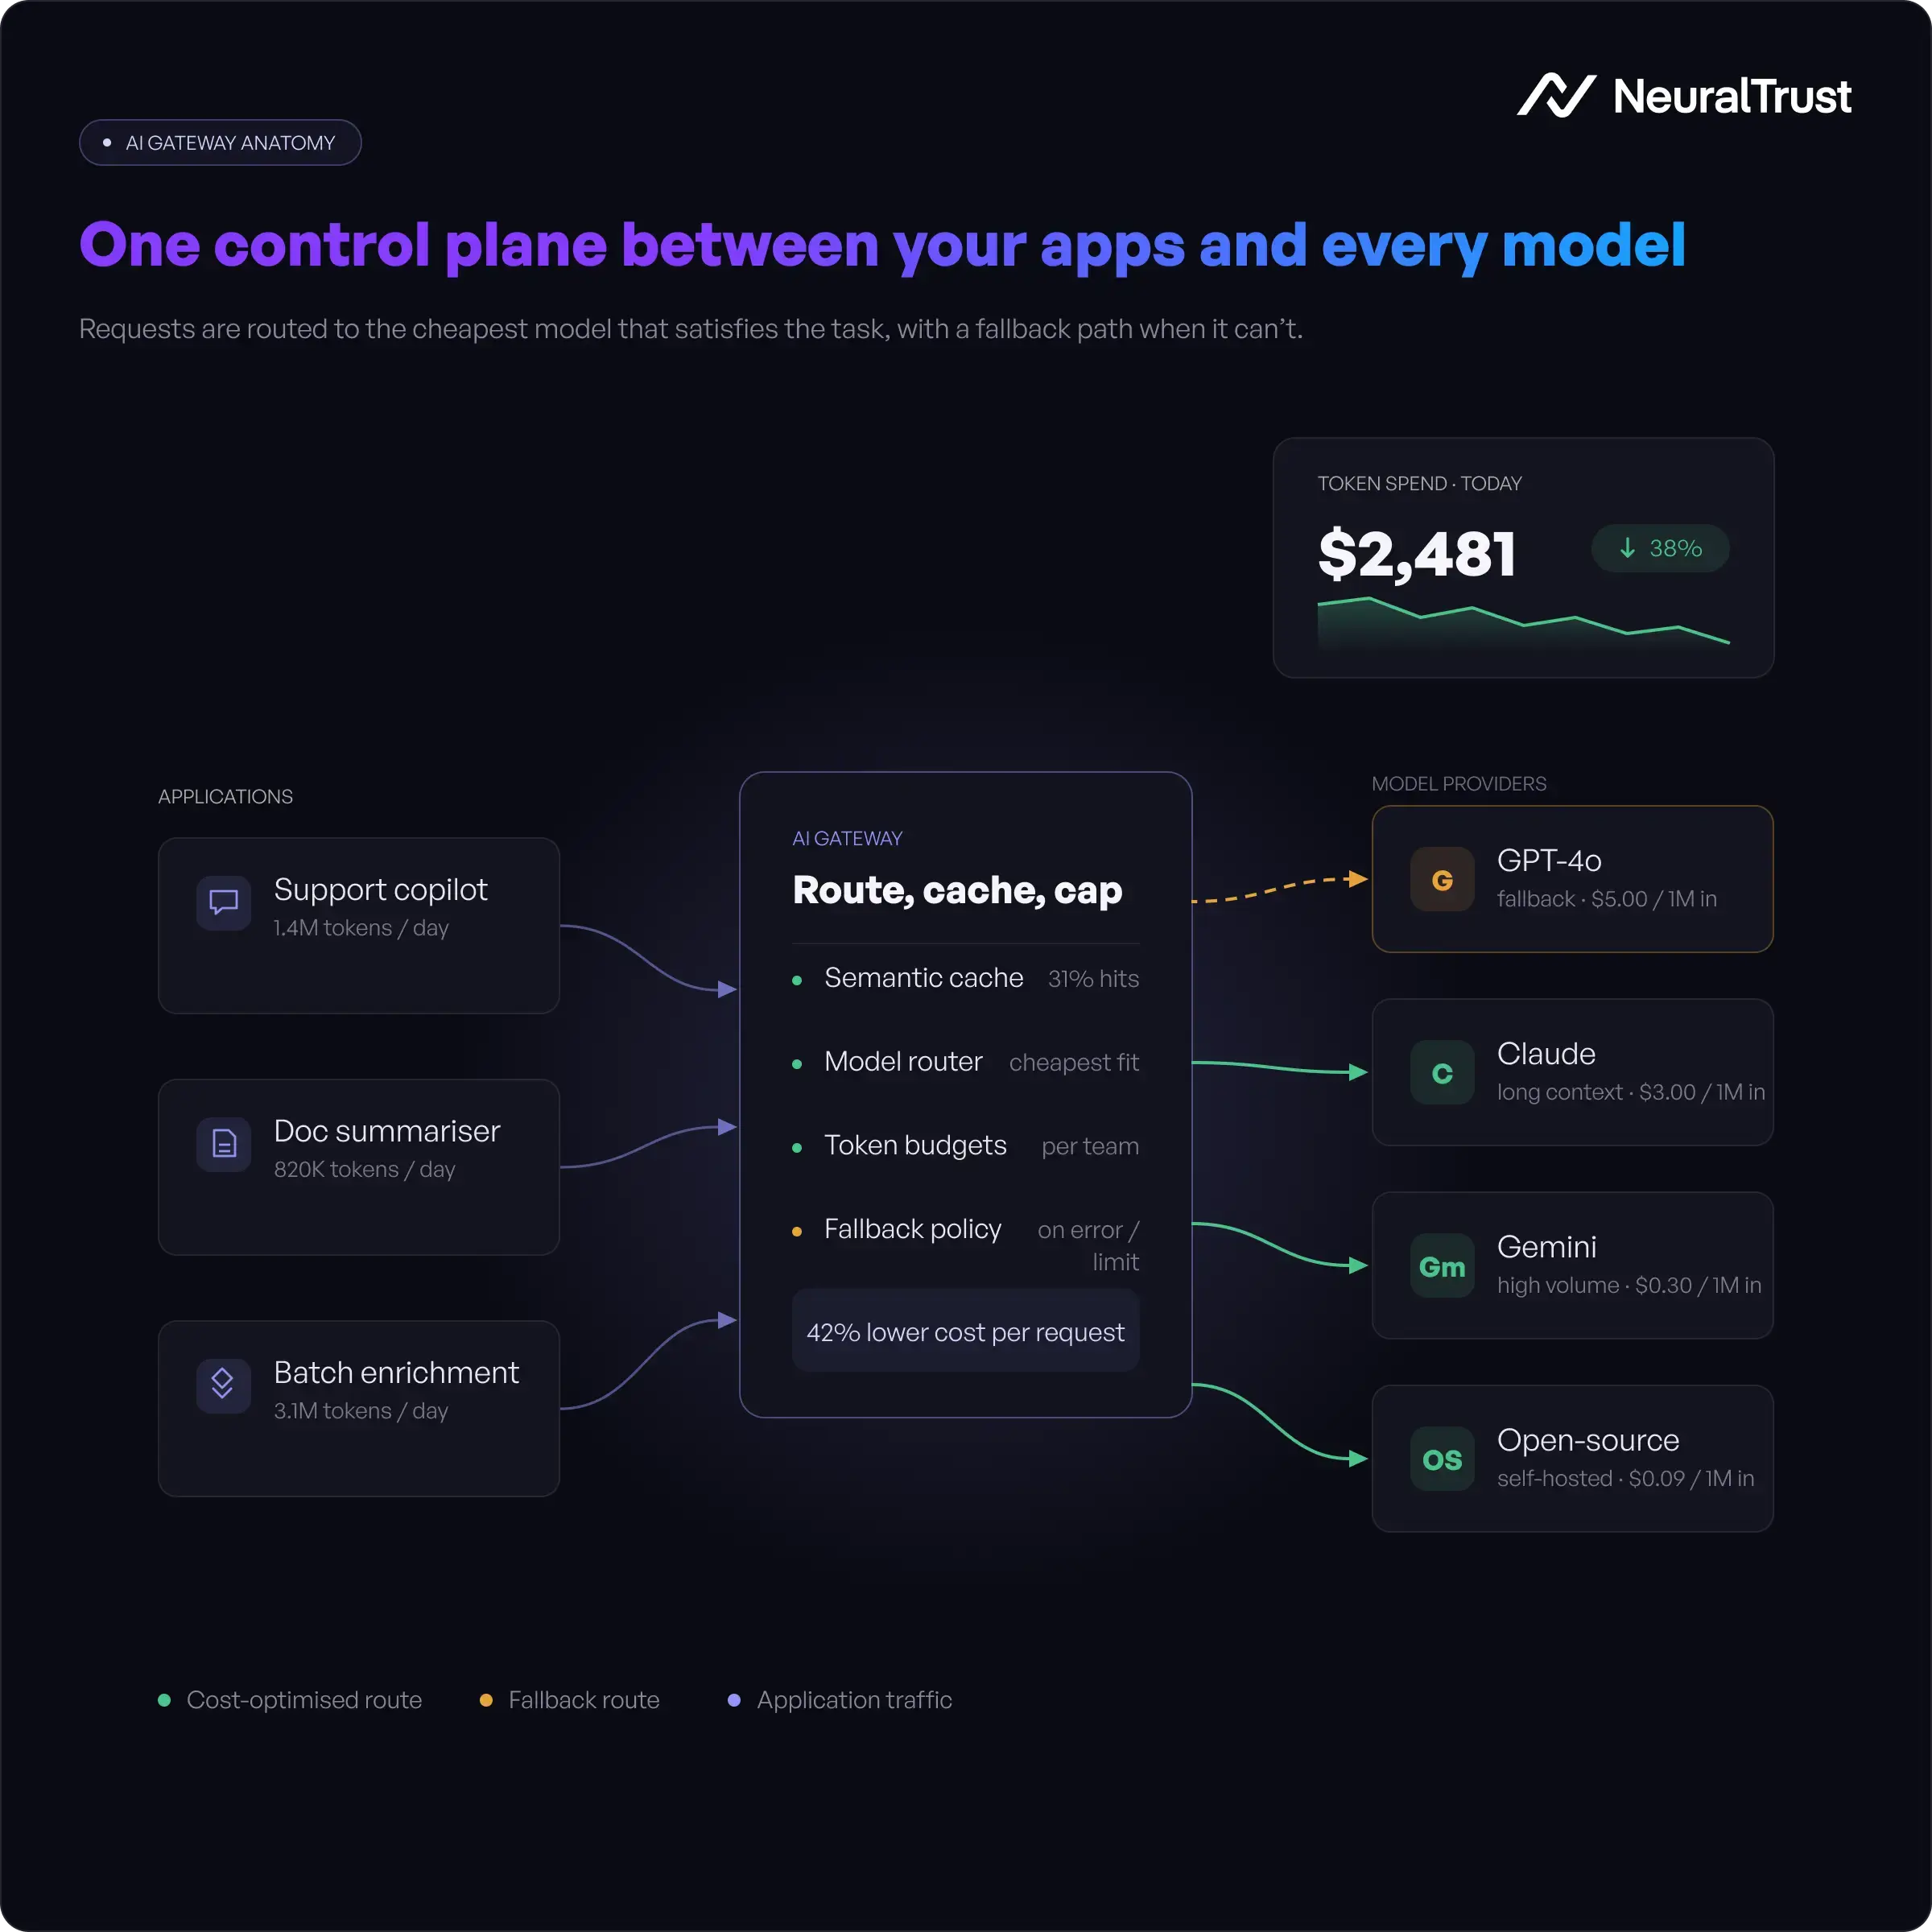
The routing engine inside an AI gateway evaluates each incoming request and directs it to the most cost-efficient model that can handle it. You define the rules: requests under a certain complexity or token estimate go to cheaper models; requests above that threshold go to more capable ones.
In practice, this looks like a tiered model stack:
| Request type | Routed to | Typical cost saving |
|---|---|---|
| Simple FAQ, classification, short summary | Small or mid-tier model | 70-90% per call vs frontier model |
| Code generation, multi-step reasoning | Frontier model | Baseline |
| Repeated or cached query | Cache (no model call) | 100% |
The routing decision happens in milliseconds before the upstream call. Your application sends a standard request to the gateway; the gateway decides which model handles it. No application changes required.
This is one of the most direct levers available. According to Martian's LLM routing research, teams using cost-based routing typically reduce inference spend by 40-70% without measurable degradation in output quality for the majority of their workload.
2. Semantic Caching
Semantic caching goes beyond exact-match caching. Instead of only returning a cached response when the prompt is character-for-character identical, a semantic cache uses embedding similarity to identify prompts that are asking the same thing in different words.
"What is your returns policy?" and "How do I return an item?" are different strings but semantically equivalent. A semantic cache catches both and returns the same cached response without touching the model.
For high-volume production applications, cached request rates of 20-40% are common. Each cached request costs nothing. At scale, that is a significant share of your model bill eliminated entirely.
The gateway handles cache lookup, cache writes, and cache invalidation. Applications receive responses at the same latency as a model call (or faster), with no visibility into whether the response came from cache or from the model.
3. Token Budgets and Rate Limiting
Token-based rate limiting is fundamentally different from request-count rate limiting, and it is the right abstraction for LLM cost control.
A single long prompt with a long completion can cost 100 times more than a short one. Request-count limits do not capture this. Token budgets do.
An AI gateway enforces token budgets at multiple levels:
- Per request: Maximum input and output tokens per call
- Per user: Daily or hourly token allowance before throttling kicks in
- Per application: Monthly token quota that triggers alerts or rate limits when approached
- Per agent: Hard limits on how many tokens an autonomous agent can consume in a session
This is the circuit breaker for runaway spend. A broken agent loop that would otherwise make 10,000 API calls hits the token budget and stops. The blast radius is capped before it reaches the invoice.
Rate limiting also protects against prompt injection attacks designed to extract long completions or trigger expensive tool chains, which connects directly to the security layer your AI gateway enforces.
4. Fallback Chains (Avoiding Expensive Retry Logic)
Without a gateway, application-layer retry logic typically retries on the same provider, at full cost, when a request fails. A gateway implements intelligent fallback chains: when the primary model is unavailable or rate-limited, the request automatically routes to the next provider in the chain.
This has two cost benefits. First, it avoids the latency cost of failed requests that are then retried manually. Second, you can configure the fallback chain to route to cheaper models when the primary is degraded, so downtime does not force expensive manual intervention.
You define the chain. The gateway handles the retry. Applications receive a response without knowing a fallback occurred. More on how fallback chains work in the routing engine.
5. Cost Attribution by Team and Application
Cost attribution is not a cost reduction mechanism by itself. It is the prerequisite for every other mechanism to work.
Without knowing which team is spending what, you cannot have a cost-reduction conversation with engineering leads. You cannot set meaningful token budgets. You cannot identify which application is the largest cost driver. You cannot show the CFO a credible plan.
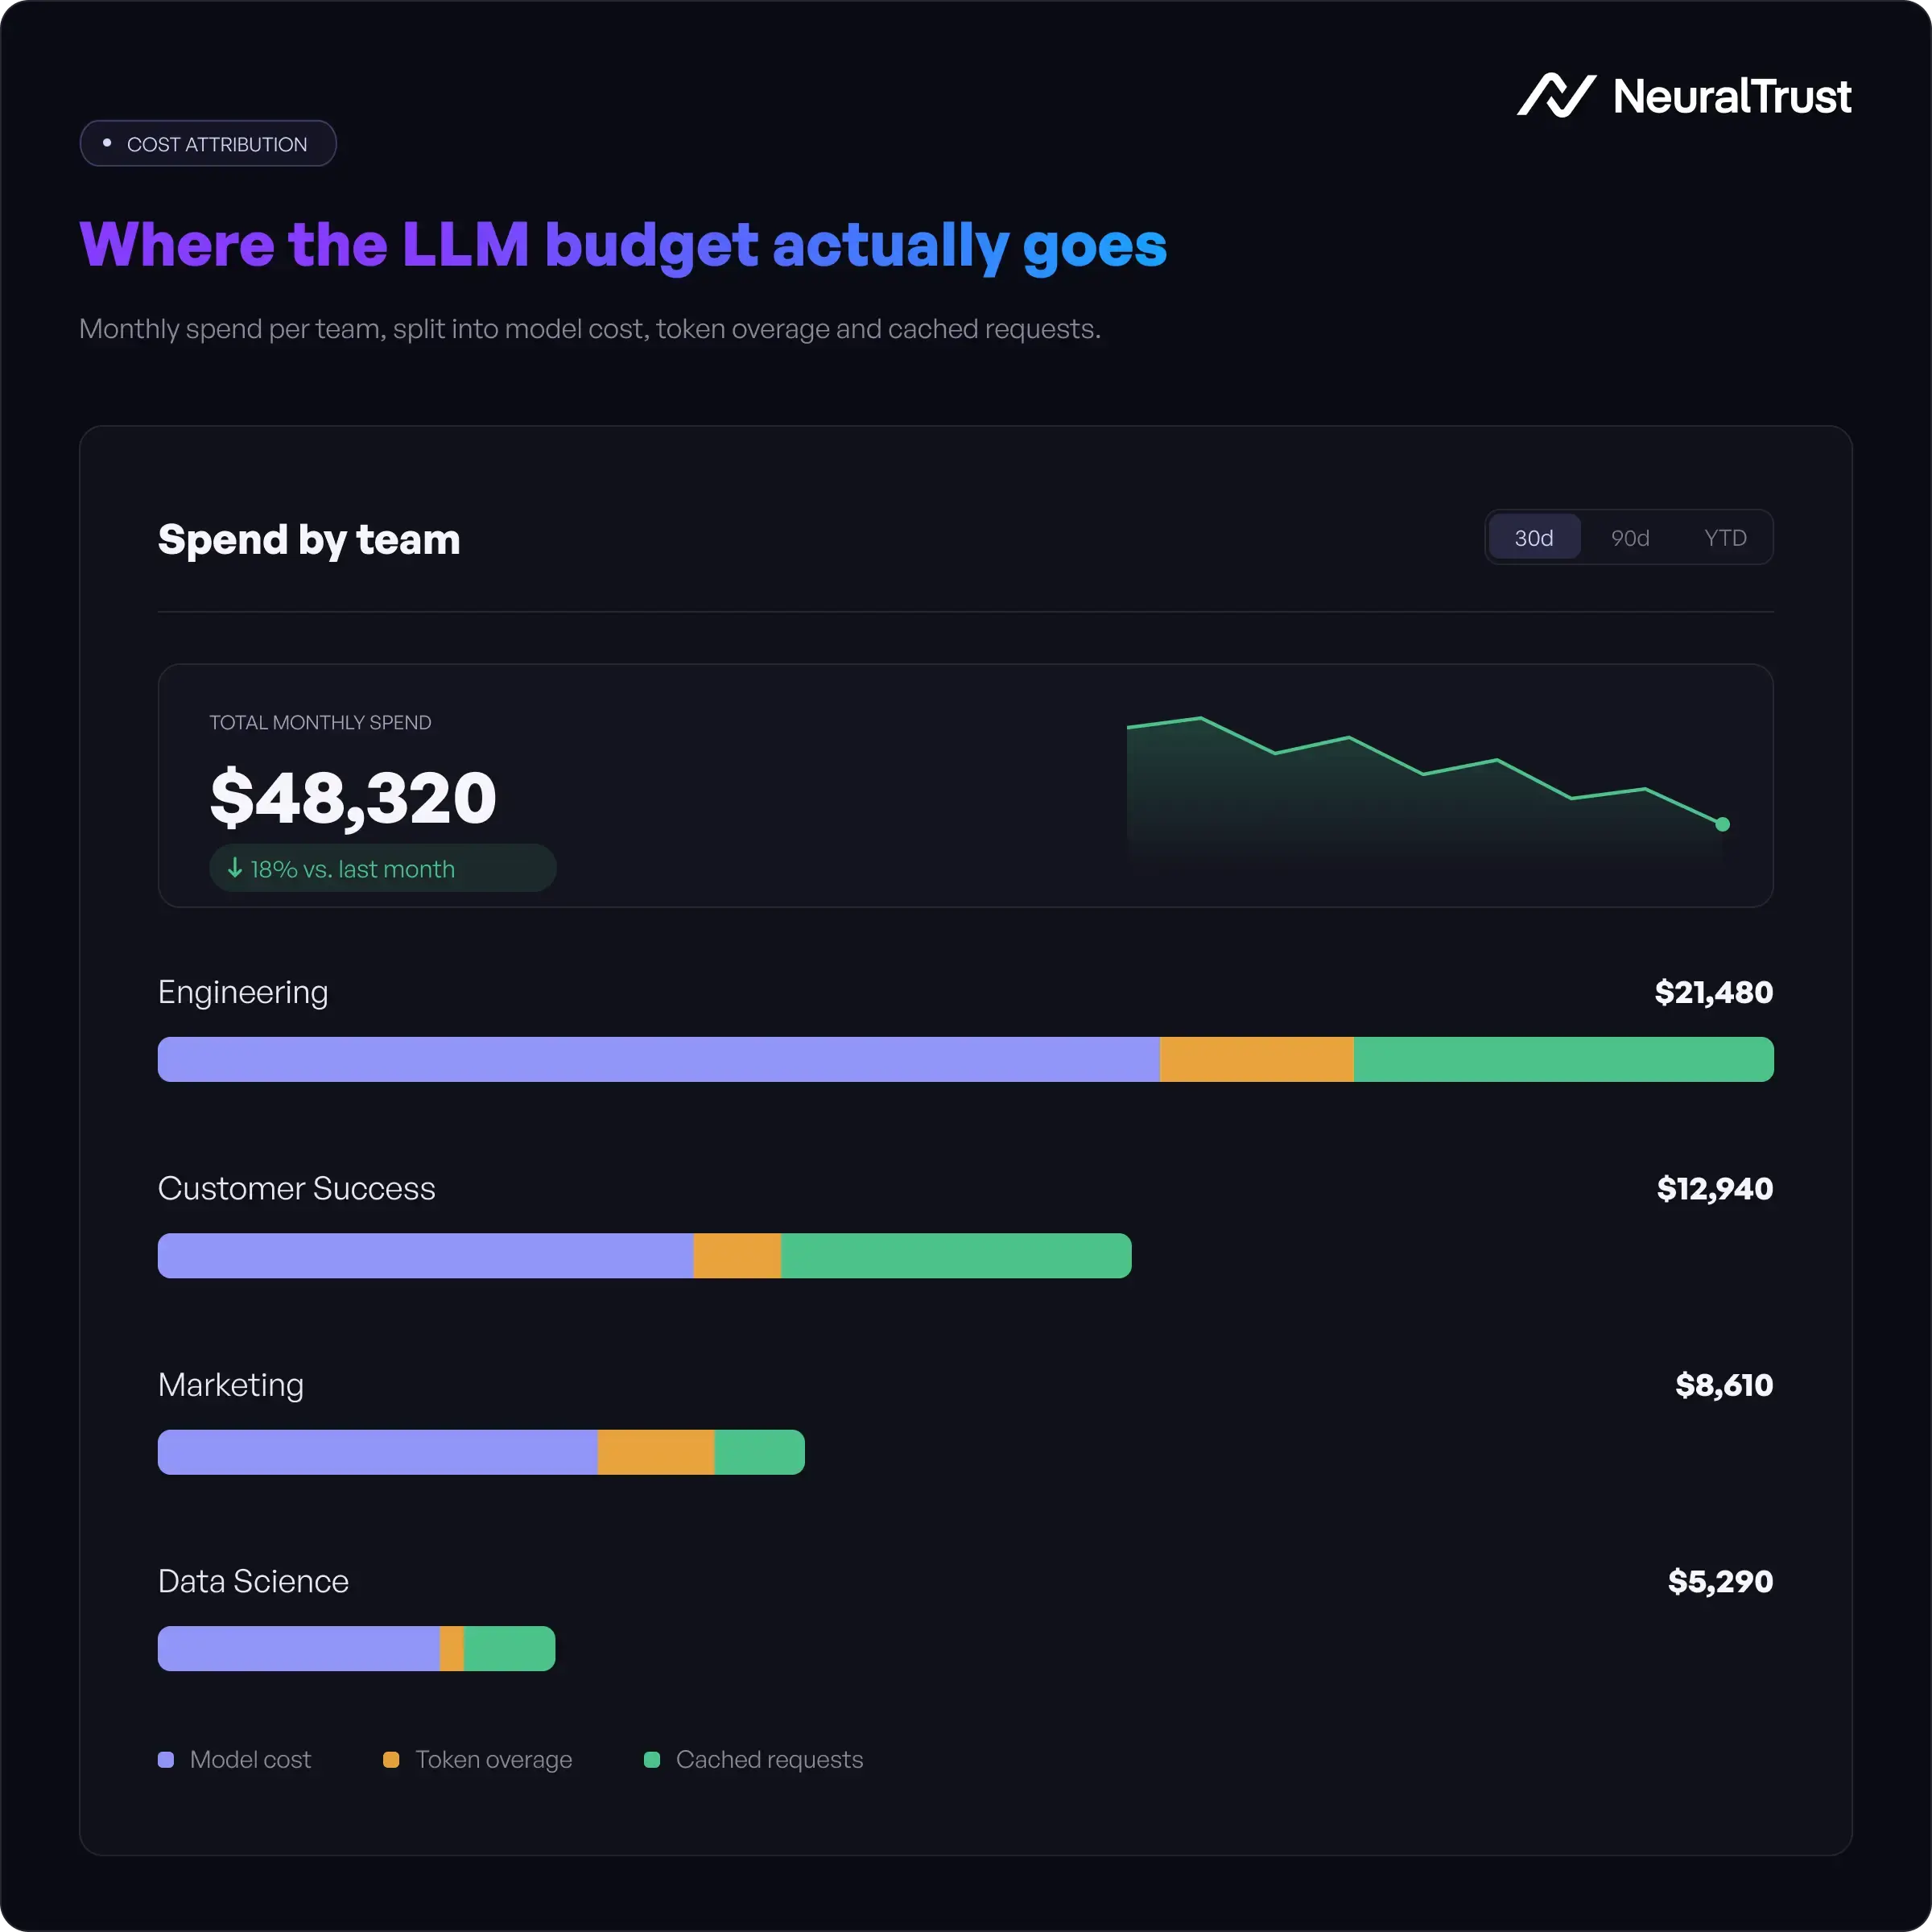
A gateway tags every request with its source (API key, service identity, team label, or application name) and rolls that up into cost reports: spend by team per day, spend by model per week, cost per request type. This is the observability layer that makes LLM cost management operational.
Once attribution is in place, the pattern of cost reduction is straightforward: identify the highest-spend team or application, look at what model they are using and whether routing could shift some of their workload to cheaper models, check their cache hit rate, and review whether their token usage per request is within expected ranges.
What LLM Cost Optimisation Looks Like in Practice
Here is a realistic example of what a medium-sized engineering team looks like before and after deploying an AI gateway with cost controls in place.
| Metric | Before gateway | After gateway | Change |
|---|---|---|---|
| Average cost per request | $0.042 | $0.016 | -62% |
| Cache hit rate | 0% | 31% | +31pp |
| Requests routed to cheaper models | 0% | 58% | +58pp |
| Runaway agent incidents per month | 4 | 0 | -100% |
| Cost attribution coverage | 0% | 100% | Full visibility |
| Time to identify cost anomalies | Days | Minutes | Real-time alerts |
The cost reduction comes from three places simultaneously: routing, caching, and eliminating runaway spend. Attribution makes all of it visible and auditable.
The MCP Layer: Cost Control for Agent Tool Calls
As AI agents become more common in production, LLM costs are no longer just about model inference. Agents make tool calls, retrieve context, and chain multiple model invocations to complete a task. Each step adds to the bill.
The Model Context Protocol (MCP) is the standard that governs how agents connect to tools and data sources. An AI gateway that operates at the MCP layer can apply cost controls to agent tool calls directly: limiting how many tool calls an agent can make per session, which data sources it can retrieve from, and how much context it is allowed to pull before costs compound.
Without MCP-layer controls, an agent that is supposed to answer a support ticket can make dozens of tool calls and model invocations before returning an answer, at multiples of the expected cost. With gateway-level controls at both the LLM layer and the MCP layer, that behaviour is bounded.
TrustGate: Cost Optimisation at the Infrastructure Layer
TrustGate is NeuralTrust's open-source AI gateway. It implements all five cost mechanisms described above at the infrastructure layer, applying to every application and every model in your stack from a single deployment.
- Intelligent routing is configured declaratively: define cost thresholds, model tiers, and routing rules once. The gateway enforces them on every request.
- Semantic caching is built into the data plane. Cache hits are logged alongside cache misses so you can measure the savings directly.
- Token budgets and rate limits are set per API key, per user, or per application and enforced in real time.
- Fallback chains route to alternative providers or cheaper models automatically when the primary is degraded.
- Cost attribution is captured on every request and surfaced through the observability dashboard, broken down by team, application, model, and time period.
TrustGate runs in your own infrastructure (Kubernetes, VPC, or on-premises) so LLM traffic never leaves your environment. The control plane manages policy without touching your data.
View TrustGate on GitHub | TrustGate product page
Start Reducing Your LLM Costs Today
No sales call. No credit card. Deploy TrustGate in your own environment and get full visibility into your LLM spend with routing, caching, and rate limiting active, just in minutes.
FAQs about Reducing LLM Costs with an AI Gateway
1. How does an AI gateway reduce LLM costs?
An AI gateway reduces LLM costs through five mechanisms: intelligent routing (directing requests to the cheapest model that can handle them), semantic caching (returning cached responses for repeated or similar queries without touching the model), token budgets and rate limits (capping per-user and per-application spend before it compounds), fallback chains (avoiding expensive manual retries when providers degrade), and cost attribution (making every dollar of AI spend visible by team and application).
2. What is cost-based LLM routing?
Cost-based LLM routing is the practice of directing each AI request to the most cost-efficient model that can handle it, rather than sending all requests to the same model regardless of complexity. A routing engine evaluates each request against rules you define (complexity estimates, token counts, task type) and selects the appropriate model tier. Simple tasks go to cheaper models; complex tasks go to frontier models. The decision happens at the gateway layer before any upstream call is made.
3. What is semantic caching in an AI gateway?
Semantic caching is a caching mechanism that returns stored responses for prompts that are semantically equivalent, not just character-for-character identical. It uses embedding similarity to match incoming prompts against previously answered ones. This catches paraphrased versions of the same question and eliminates redundant model calls. For high-volume production applications, semantic cache hit rates of 20-40% are common, reducing model call volume (and cost) accordingly.
4. How do token budgets work in an AI gateway?
Token budgets set a maximum number of input and output tokens a user, application, or agent is allowed to consume in a given period. The gateway enforces the budget in real time, throttling or blocking requests that would exceed it. This is the primary mechanism for containing runaway spend from broken agent loops, unusually long sessions, or prompt injection attacks designed to trigger expensive completions. Unlike request-count limits, token budgets reflect the actual cost driver in LLM infrastructure.
5. Can an AI gateway reduce costs without changing application code?
Yes. Because an AI gateway sits between your applications and your LLM providers, it applies routing, caching, and rate limiting at the infrastructure layer. Applications send requests to the gateway endpoint exactly as they would send them to a provider directly. The gateway handles all cost-control decisions transparently. No SDK changes, no application refactoring, and no per-service instrumentation required.
6. What is the relationship between LLM cost optimisation and LLM observability?
Cost optimisation depends on observability. You cannot route intelligently without knowing which requests are most expensive. You cannot set meaningful token budgets without knowing current usage patterns. You cannot identify cost anomalies without real-time monitoring. Cost attribution (knowing which team or application generated which spend) is the prerequisite for all targeted cost reduction. An AI gateway provides both simultaneously: the observability data that identifies the problem and the control mechanisms that fix it.
Related articles
- What Is an AI Gateway? Complete Guide
- AI Gateway vs MCP Gateway
- AI Gateway Security: Protecting LLM Traffic
- AI Gateway Architecture: How It Works Under the Hood
- LLM Observability with an AI Gateway
- AI Token Optimization: Complete Guide to Reducing LLM Costs
About the Author
Roger Howroyd is Head of Global SEO and AI at NeuralTrust, where he leads the company's search strategy across SEO, AEO, GEO, and LLM optimization. He specializes in AI-powered search, content strategy, and SEM. Connect on LinkedIn.
*NeuralTrust is an AI agent security platform recognized in the Gartner Hype Cycle for Application Security 2026, the Gartner Market Guide for AI Gateways, and the KuppingerCole Leadership Compass for Generative AI Defense. ISO 27001 certified. Headquartered in Barcelona.