AI Gateway Architecture: An AI gateway processes every LLM request through five sequential layers: authentication, routing, security inspection, the upstream model call, and logging. The routing engine decides which model handles each request using load balancing, fallback chains, and cost-based rules. A split-plane architecture separates policy management from traffic handling, keeping your data in your own environment.
TL;DR - Key Takeaways
- Every request through an AI gateway passes five layers in sequence: authentication, routing, security inspection, upstream call, and logging
- The routing engine handles: load balancing, fallback chains, and cost-based decisions, directing each request to the right model in milliseconds
- Control plane vs data plane: separation determines whether your LLM traffic ever leaves your infrastructure
- TrustGate's split-plane design keeps the data plane entirely within your environment; the control plane manages policies without touching your traffic
Most engineers treat an AI gateway as a black box. Traffic goes in, responses come back. But the architecture inside determines whether you can actually control your AI stack in production. This article walks through every layer, from authentication to audit log. Skip to the routing engine section if that's what you came for.
The Problem Nobody Talks About Until It Breaks
You are six months into production. The AI features work. Then your CTO asks: how much is each user costing us? Which model handled that failed request last week? Did any prompt from the customer service team include PII?
No answers. Not because you are a bad engineer. Because you were moving fast, and the gateway layer felt like something to add later.
Now you are adding it with live traffic.
This is the pattern. The control layer gets skipped, then rebuilt under pressure. Building it right from the start means understanding how it actually works.
What Is an AI Gateway?
An AI gateway is an AI router: a reverse proxy layer built specifically for LLM traffic. It sits between your applications and the model providers you use. Every request goes through it.
Unlike a standard API gateway, it understands the payload. It does not just forward HTTP traffic. It reads prompts, inspects responses, routes by model capability, and logs every token at every step.
The architecture inside is what makes all of that possible.
How an AI Gateway Processes a Request
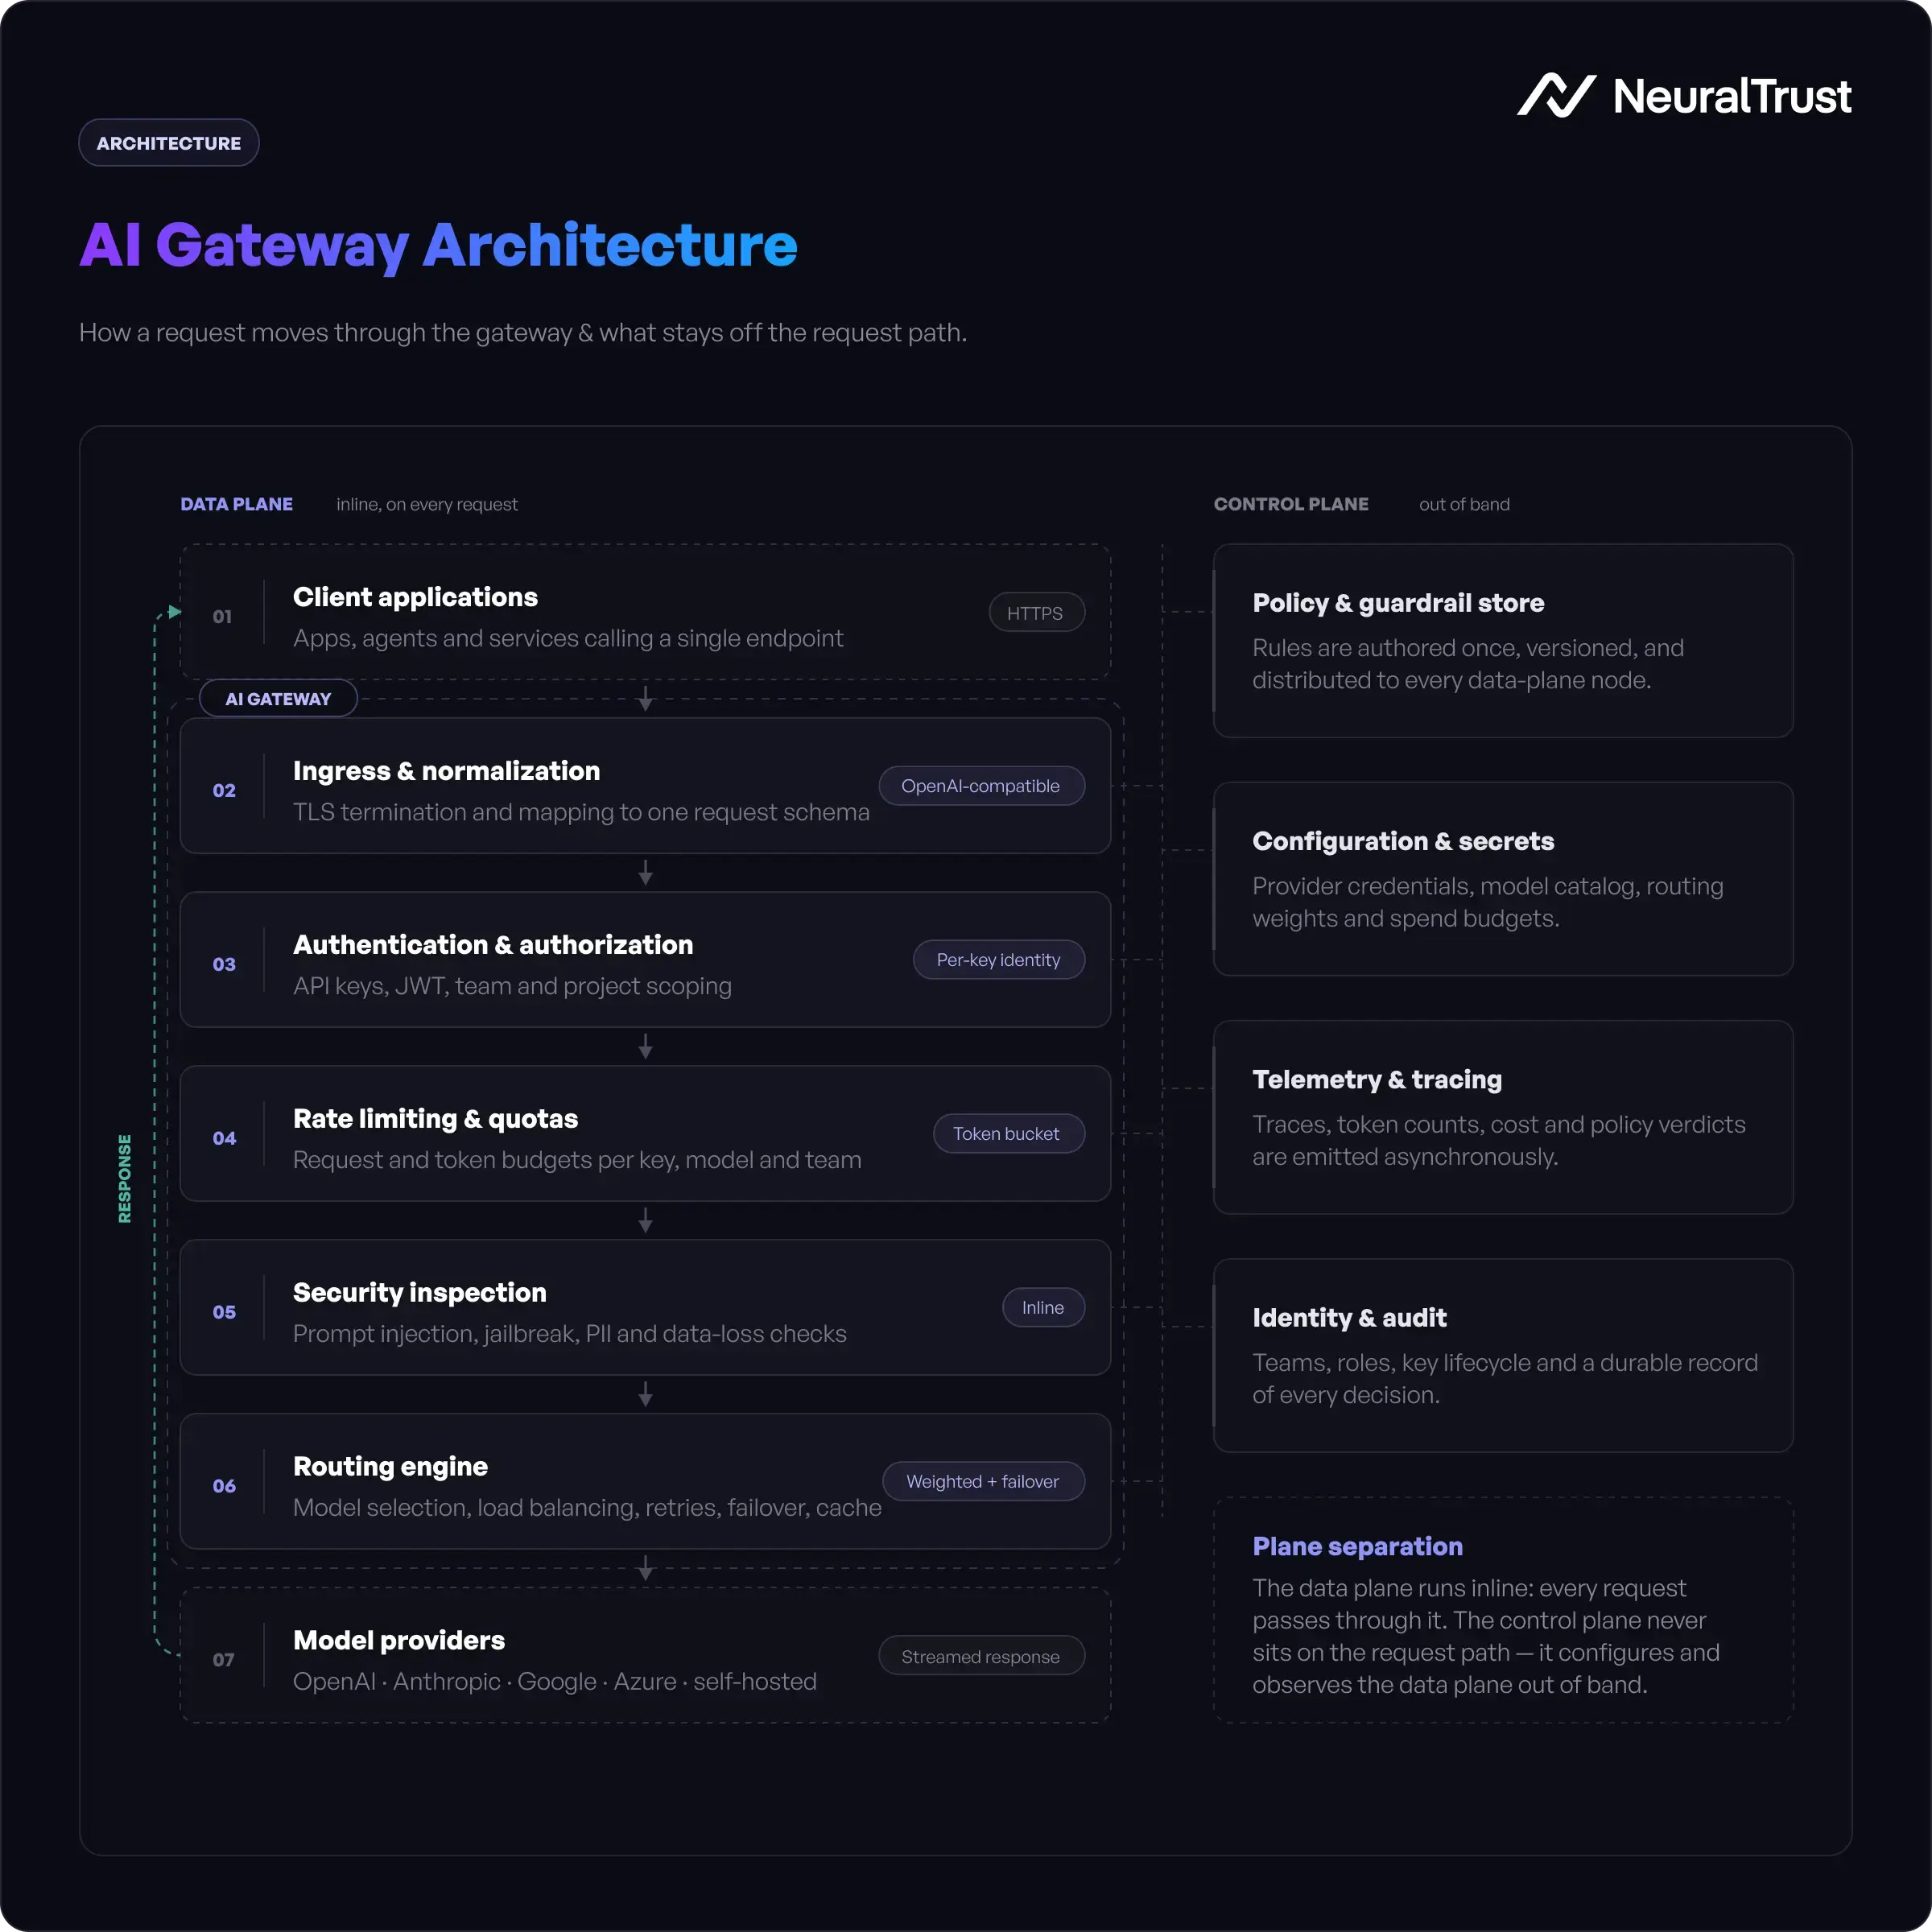
Here is the full flow. Five steps, one request, milliseconds end-to-end.
Step 1: Request received
Your application sends an API call to the gateway endpoint. To the application, this looks identical to calling an LLM provider directly. The gateway is transparent in the path.
Step 2: Authentication and access control
Who sent this? Which models are they allowed to call? What rate limits apply? A service token identifies the caller. If authentication fails, the request stops here. Nothing reaches the routing engine.
Step 3: Routing decision
The routing engine evaluates the request. Which model handles it? Not random. The engine applies rules you define: cost thresholds, latency targets, model capability requirements, current provider availability. The decision happens before any upstream call is made.
Step 4: Security inspection
Before the request goes upstream, the security layer inspects the prompt. Prompt injection is the top threat listed in the OWASP LLM Top 10. The layer scans for injection attempts, detects and redacts PII, and applies your content policies. The same inspection runs on the response before it returns to the caller. More on the security layer here.
Step 5: Logging and tracing
Every interaction is logged: timestamp, caller identity, model used, tokens consumed, latency, cost, and policy outcomes. No logging means no debugging, no cost attribution, and no compliance evidence.
Total round-trip: under 100ms in a well-built gateway.
The Routing Engine: How LLM Routing Actually Works
The routing engine is the most technically interesting part. This is where the "AI router" label comes from.
Three strategies matter in production.
Load balancing
Distribute requests across multiple instances of the same model. Useful when you are hitting provider rate limits or want to smooth latency variance. Standard load balancing patterns, applied to LLM endpoints: round-robin, weighted, or least-connections.
Fallback chains
If your primary model is unavailable or returns an error, the gateway automatically retries with the next provider in the chain. You define the order. The gateway handles the retry. Your application gets a response without knowing a failure occurred. This is what real LLM observability looks like in practice: the system recovers, and the event is logged.
Cost-based routing
The routing engine knows the cost per token for each model. You set a threshold: requests under a certain complexity or token estimate go to cheaper models, requests above it go to the capable one. This is one of the most direct levers for reducing LLM costs without changing any application code.
These three strategies together mean you are not locked into one provider, and you are not overpaying for simple tasks.
Control Plane vs Data Plane: Why the Split Matters
This is the architectural decision with the biggest security and compliance implications.
A naive design runs everything in one process: policy management, traffic handling, logging. Simple to build. But it means LLM traffic has to pass through the gateway vendor's infrastructure.
A split-plane architecture separates two concerns:
- Control plane: Manages configuration, policies, and routing rules. Knows what to enforce. Does not touch LLM traffic.
- Data plane: Handles actual LLM requests and responses. Runs in your infrastructure.
The control plane tells the data plane what rules to apply. The data plane enforces them without your traffic leaving your environment.
For regulated industries, this is not optional. The NIST AI Risk Management Framework identifies access control and data handling as core requirements for responsible AI deployment. The EU AI Act, applicable from August 2026, requires demonstrable data controls for high-risk AI systems. A split-plane architecture is how you prove those controls exist. Why this matters for data sovereignty.
Architectural Patterns Compared
Three deployment patterns exist. They have genuinely different security properties.
| Pattern | Data Path | Latency | Sovereignty | Complexity |
|---|---|---|---|---|
| Centralized (SaaS) | Vendor cloud | Low | Limited | Low |
| Sidecar | Collocated with each app | Very low | High | High |
| Split-plane | Data plane in customer env | Low | High | Medium |
Centralized SaaS is fast to set up. Your traffic routes through their cloud. Simple operationally, limited from a data sovereignty standpoint.
Sidecar deploys the gateway alongside each application instance. Maximum control, but complex to manage at scale. Every new service needs its own gateway deployment.
Split-plane gives you sovereignty without sidecar complexity. The data plane runs in your environment and is managed centrally through the control plane. That is the right balance for most enterprise deployments.
How the major AI gateways compare on these dimensions.
The Plugin and Middleware Layer
A well-designed AI gateway is not monolithic. It is a pipeline.
Each request passes through a chain of plugins, each doing one job:
- Rate limiter
- Authentication handler
- PII detector
- Prompt injection scanner
- Router
- Cost tracker
- Response filter
- Audit logger
Enable what you need. Disable what you do not. The pipeline runs in order. Adding a new inspection step means adding a plugin, not rebuilding the gateway.
This is also how AI gateways and guardrails work together. A guardrail is a plugin in the middleware chain, running alongside routing and cost tracking as one coordinated pipeline, not a separate system bolted on.
How centralized AI management works at scale.
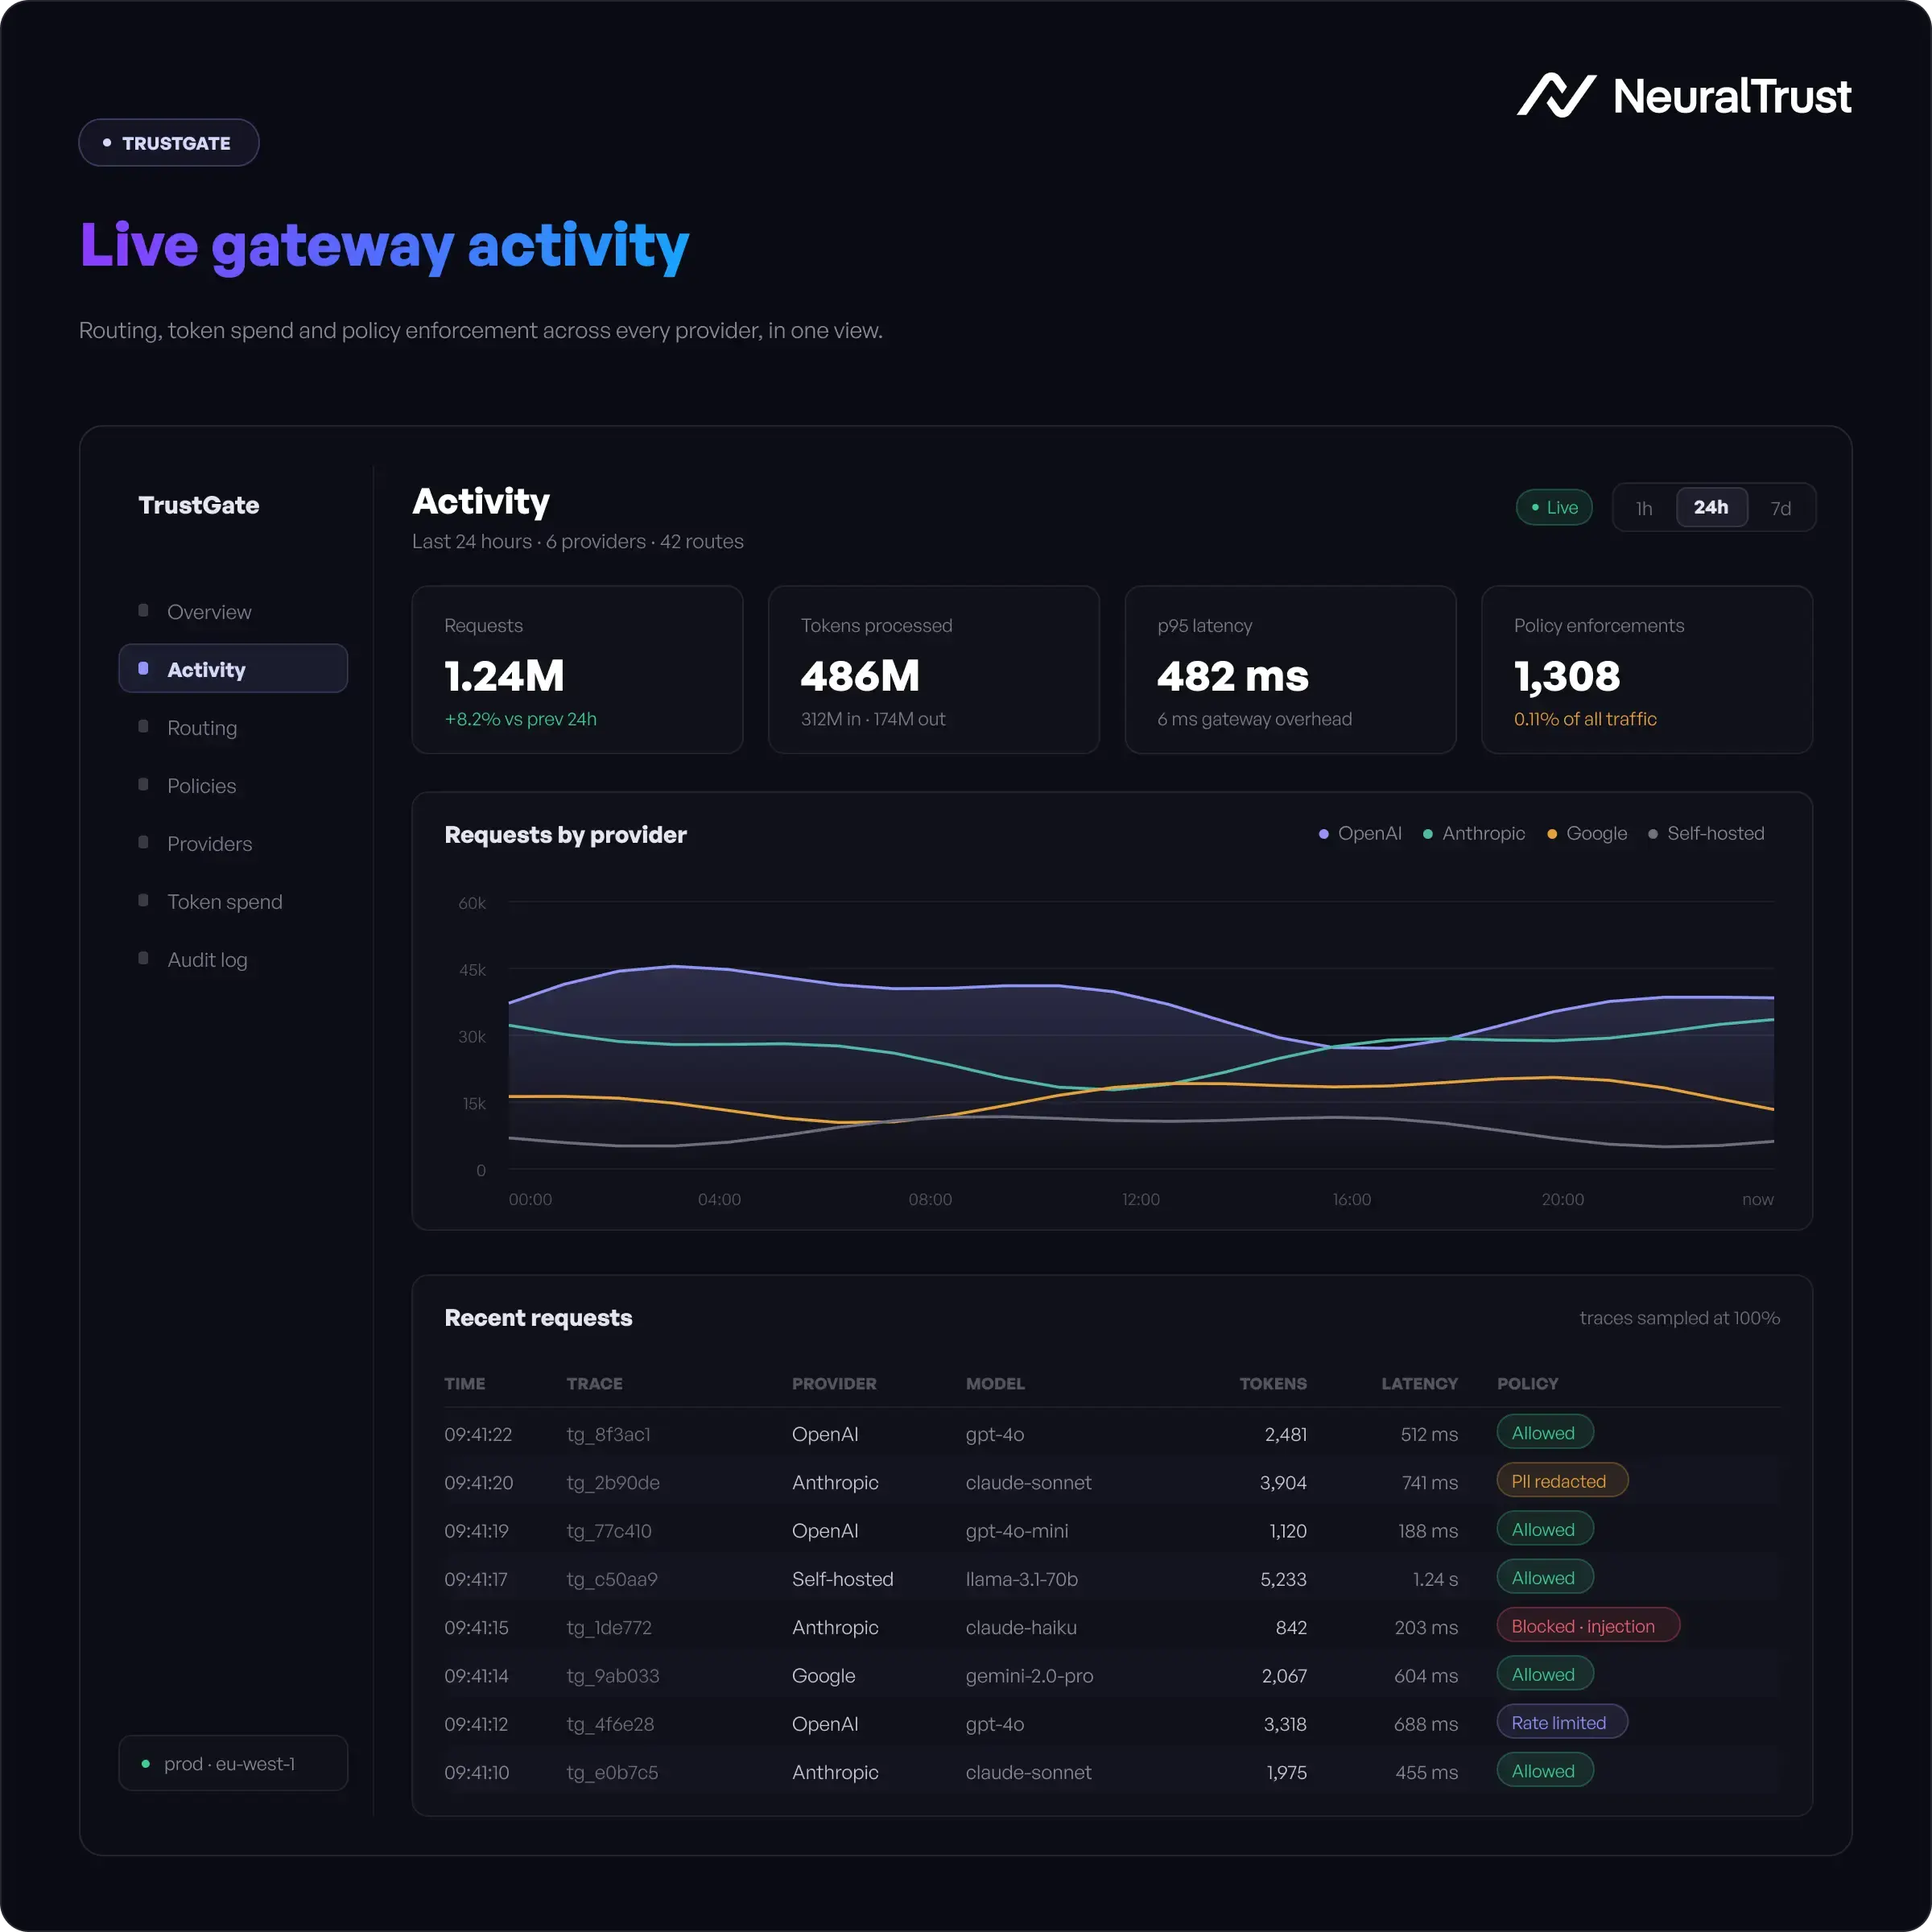
TrustGate: Split-Plane Architecture in Practice
TrustGate is NeuralTrust's open-source AI gateway. It implements the split-plane pattern.
The data plane is a high-performance Go service that runs in your Kubernetes cluster, your VPC, or your on-premises environment. It handles routing, security inspection, and logging without any traffic leaving your infrastructure.
The control plane distributes policy updates to the data plane. Policy changes propagate in seconds without downtime.
Average inline latency: under 100ms. No traffic leaves your environment.
Gartner named NeuralTrust a Representative Vendor in AI Gateways in the 2025 Gartner Market Guide for AI Gateways.
View TrustGate on GitHub | TrustGate product page
The Full AI Gateway Series
- What Is an AI Gateway? Complete Guide
- AI Gateway vs MCP Gateway
- AI Gateway Security: Protecting LLM Traffic
- How an AI Gateway Solves LLM Observability
- How an AI Gateway Reduces LLM Costs
- AI Gateways vs API Gateways: The Differences
- Centralized AI Management at Scale
- AI Gateways and Data Sovereignty
- Best AI Gateways in 2026
- AI Gateway vs Guardrails: What You Actually Need
Frequently Asked Questions about AI Gateway Architecture
1. What is LLM routing?
LLM routing is the process of directing each AI request to the appropriate model based on rules you define. The routing engine inside an AI gateway evaluates each incoming request and decides which model handles it, based on cost, latency targets, capability requirements, or provider availability. The decision happens in milliseconds before the upstream call.
2. How does an AI gateway route traffic?
The routing engine applies three strategies: load balancing (distributing requests across model instances), fallback chains (automatically retrying with alternative models when the primary fails), and cost-based routing (sending cheaper requests to cheaper models). Rules are configured in the control plane and enforced by the data plane at request time.
3. What is a fallback chain in an AI gateway?
A fallback chain is an ordered list of model providers the gateway tries in sequence when the primary fails. If the first model returns an error or is rate-limited, the gateway automatically retries with the next provider in the chain. Your application receives a response without knowing a fallback occurred.
4. What is the difference between an AI gateway and an LLM proxy?
An LLM proxy is a simple forwarding layer: it relays requests to an LLM provider and returns responses. An AI gateway does that plus routing, security inspection, cost tracking, policy enforcement, and observability. An LLM proxy is one component in a gateway architecture, not a replacement for the full stack.
About the Author
Roger Howroyd is Head of Global SEO and AI at NeuralTrust, where he leads the company's search strategy across SEO, AEO, GEO, and LLM optimization. He specializes in AI-powered search, content strategy, and SEM. Connect on LinkedIn.
NeuralTrust is an AI agent security platform recognized in the Gartner Hype Cycle for Application Security 2026, the Gartner Market Guide for AI Gateways, and the KuppingerCole Leadership Compass for Generative AI Defense. ISO 27001 certified. Headquartered in Barcelona.