What is LLM observability? LLM observability is the practice of monitoring every request, response, token, and cost flowing through your AI applications in real time. An AI gateway provides it automatically at the infrastructure layer, covering all models and all applications from one central point, without changing any application code.
TL;DR - Key Takeaways
- SDK-level logging gives you partial visibility per app, an AI gateway gives you complete visibility across every app, model, and team from one layer
- The six metrics that matter in LLM production: request latency (p50/p95/p99), token usage, cost per call, error rate, fallback rate, and anomaly detection
- OpenTelemetry is the emerging standard for LLM tracing: a well-built gateway emits OpenTelemetry-compatible traces automatically
- TrustGate collects observability data at the gateway layer, TrustLens surfaces it as agent posture intelligence across your full AI stack
You added logging to your LLM app. But application-level logs only show you what one app did. An AI gateway sits upstream of all your apps and all your models, so it sees everything: which team is spending the most tokens, which model is slow at p99, which requests triggered fallbacks. That is what real LLM observability looks like. This article explains how it works and what you should be tracking.
You Think You Have Visibility. You Probably Don't.
I see this constantly. A team ships an LLM feature, adds some logging to the Python app, points it at a dashboard, and declares observability solved. Two months later, the LLM bill doubles unexpectedly. A latency spike appears at p99 but not p50, so nobody catches it until enterprise customers complain. A prompt from one team leaks data that belonged to another.
None of it shows up in the app-level logs.
This is the observability gap in LLM production. Not a lack of tools. Not a lack of intent. A structural problem: you are trying to observe a multi-model, multi-team, multi-application system from individual application vantage points. And it does not work.
An AI gateway solves this. Not by adding more logging to your apps. By moving the observation layer to the only place that sees everything.
What Is LLM Observability?
LLM observability is the practice of tracking and understanding every request, response, token, and cost flowing through your AI applications. It covers latency at the model level, token consumption by user and team, cost attribution by application, error and fallback rates, and anomalous traffic patterns that might indicate abuse or misconfiguration.
Traditional application performance monitoring (APM) was built for deterministic software. Same input, same output, same path. LLMs are different. The same prompt can produce different responses, consume wildly different token counts, and route to different models depending on your gateway configuration. That is why standard API gateway monitoring does not cover it, and why LLM observability is a distinct discipline.
Why SDK-Level Instrumentation Fails at Scale
Most teams start with SDK-level instrumentation. You add an OpenAI Python client wrapper, log the request and response, push it to your APM tool. This works fine for one application with one model.
It breaks in three ways as you scale.
It is per-app, not per-system. You get visibility into App A's calls, but not how App A's usage compares to App B or App C. You cannot see aggregate token consumption across your whole AI stack from any single place.
It misses the model layer. Application logs show you what the app sent and received. They do not show you which model actually handled the request after routing, what the provider returned before response filtering, or whether a fallback to a secondary model occurred.
It accumulates tech debt fast. Every new application needs its own instrumentation. Every model change requires instrumentation updates. As AI management centralises, the per-app approach becomes unmaintainable.
An AI gateway sits upstream of all of this. Every request from every application, to every model, passes through it. One observation point. Complete coverage.
The 6 Metrics That Matter in LLM Observability
Here is what you actually need to be tracking, and why each metric is different in an LLM context.
| Metric | What It Measures | Why It Matters |
|---|---|---|
| Request latency (p50/p95/p99) | Time from request to response, at each percentile | p99 reveals tail latency that averages hide; slow p99 kills enterprise user experience |
| Token usage per request | Input tokens + output tokens per call | Directly predicts cost; large variance means prompts are not optimised |
| Cost per call / cost per team | Dollar cost attributed by application, team, or user | Without this, you cannot allocate AI spend or spot runaway usage |
| Error rate | Percentage of requests that fail or return errors | Rising error rate signals provider issues or prompt policy violations |
| Fallback rate | Percentage of requests that hit the fallback chain | High fallback rate means your primary model is unreliable or rate-limited |
| Anomaly detection alerts | Unusual spikes in volume, cost, or failure patterns | Catches prompt injection campaigns, misconfigured agents, or billing surprises before they escalate |
These metrics are only meaningful when aggregated across your full stack. A single app's error rate tells you little. Your error rate across all models and all teams tells you whether you have a provider problem, a prompt problem, or a configuration problem.
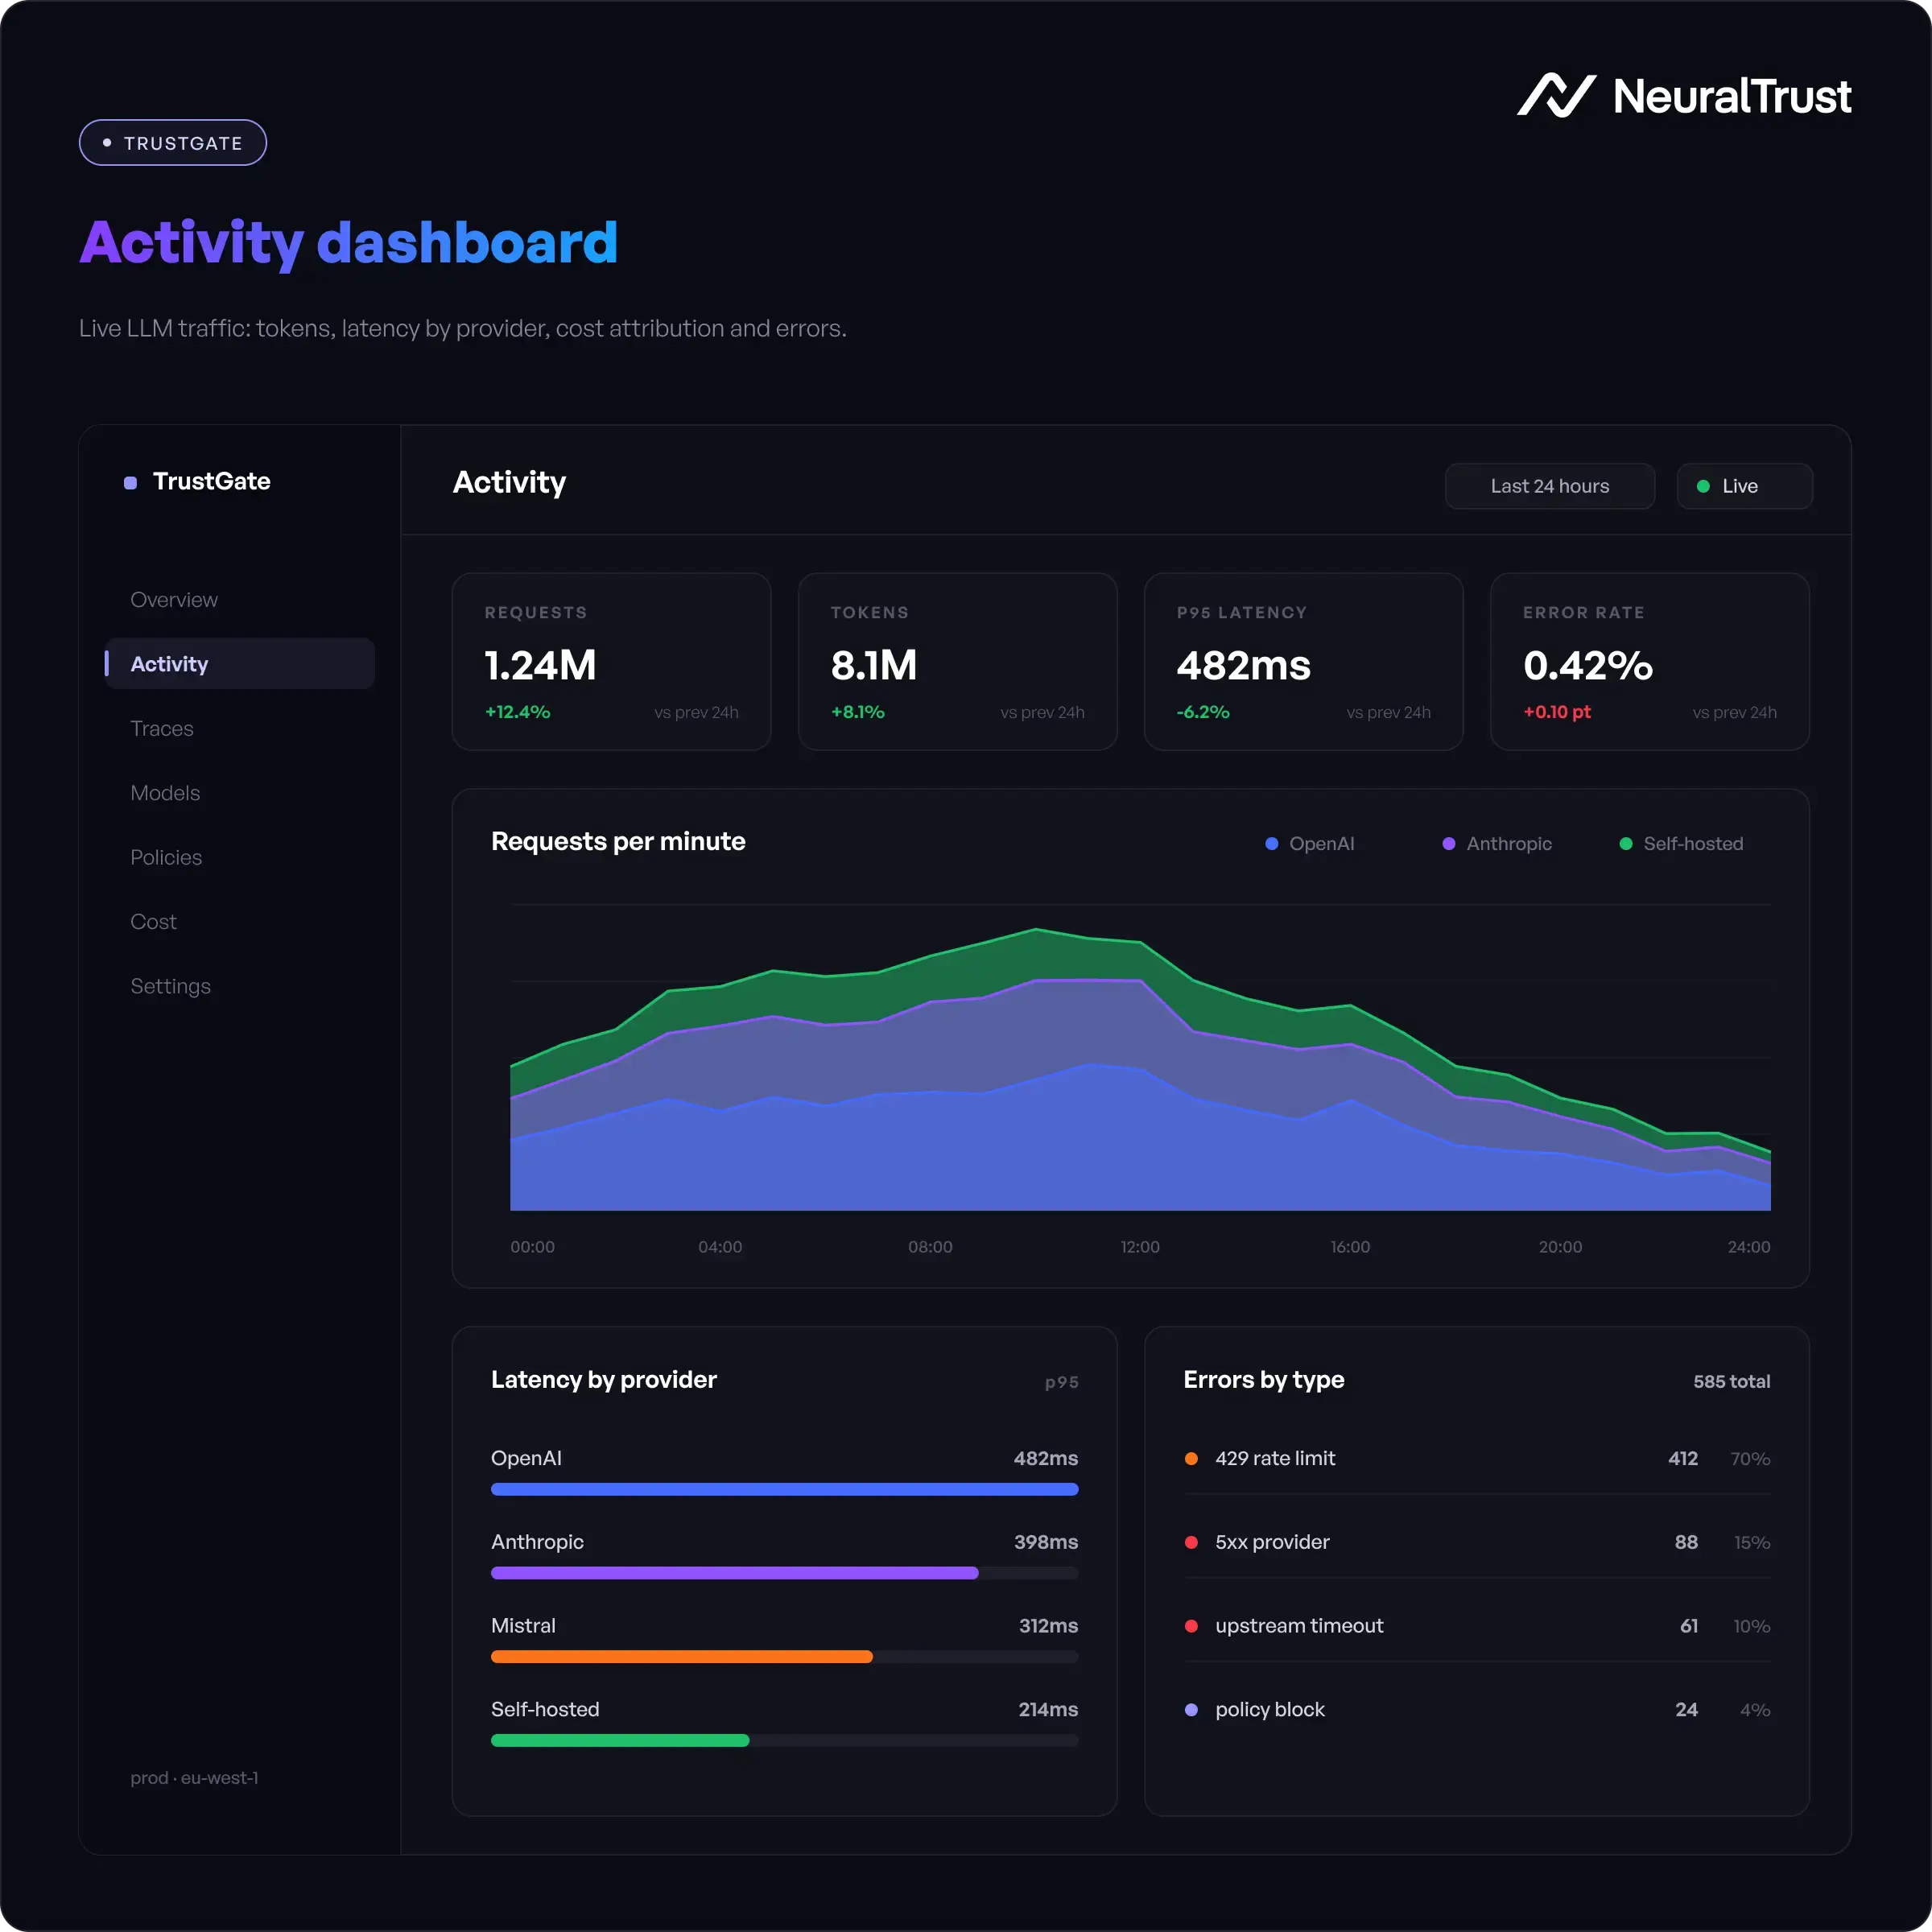
Latency That Actually Means Something
Most teams track average latency. Averages lie.
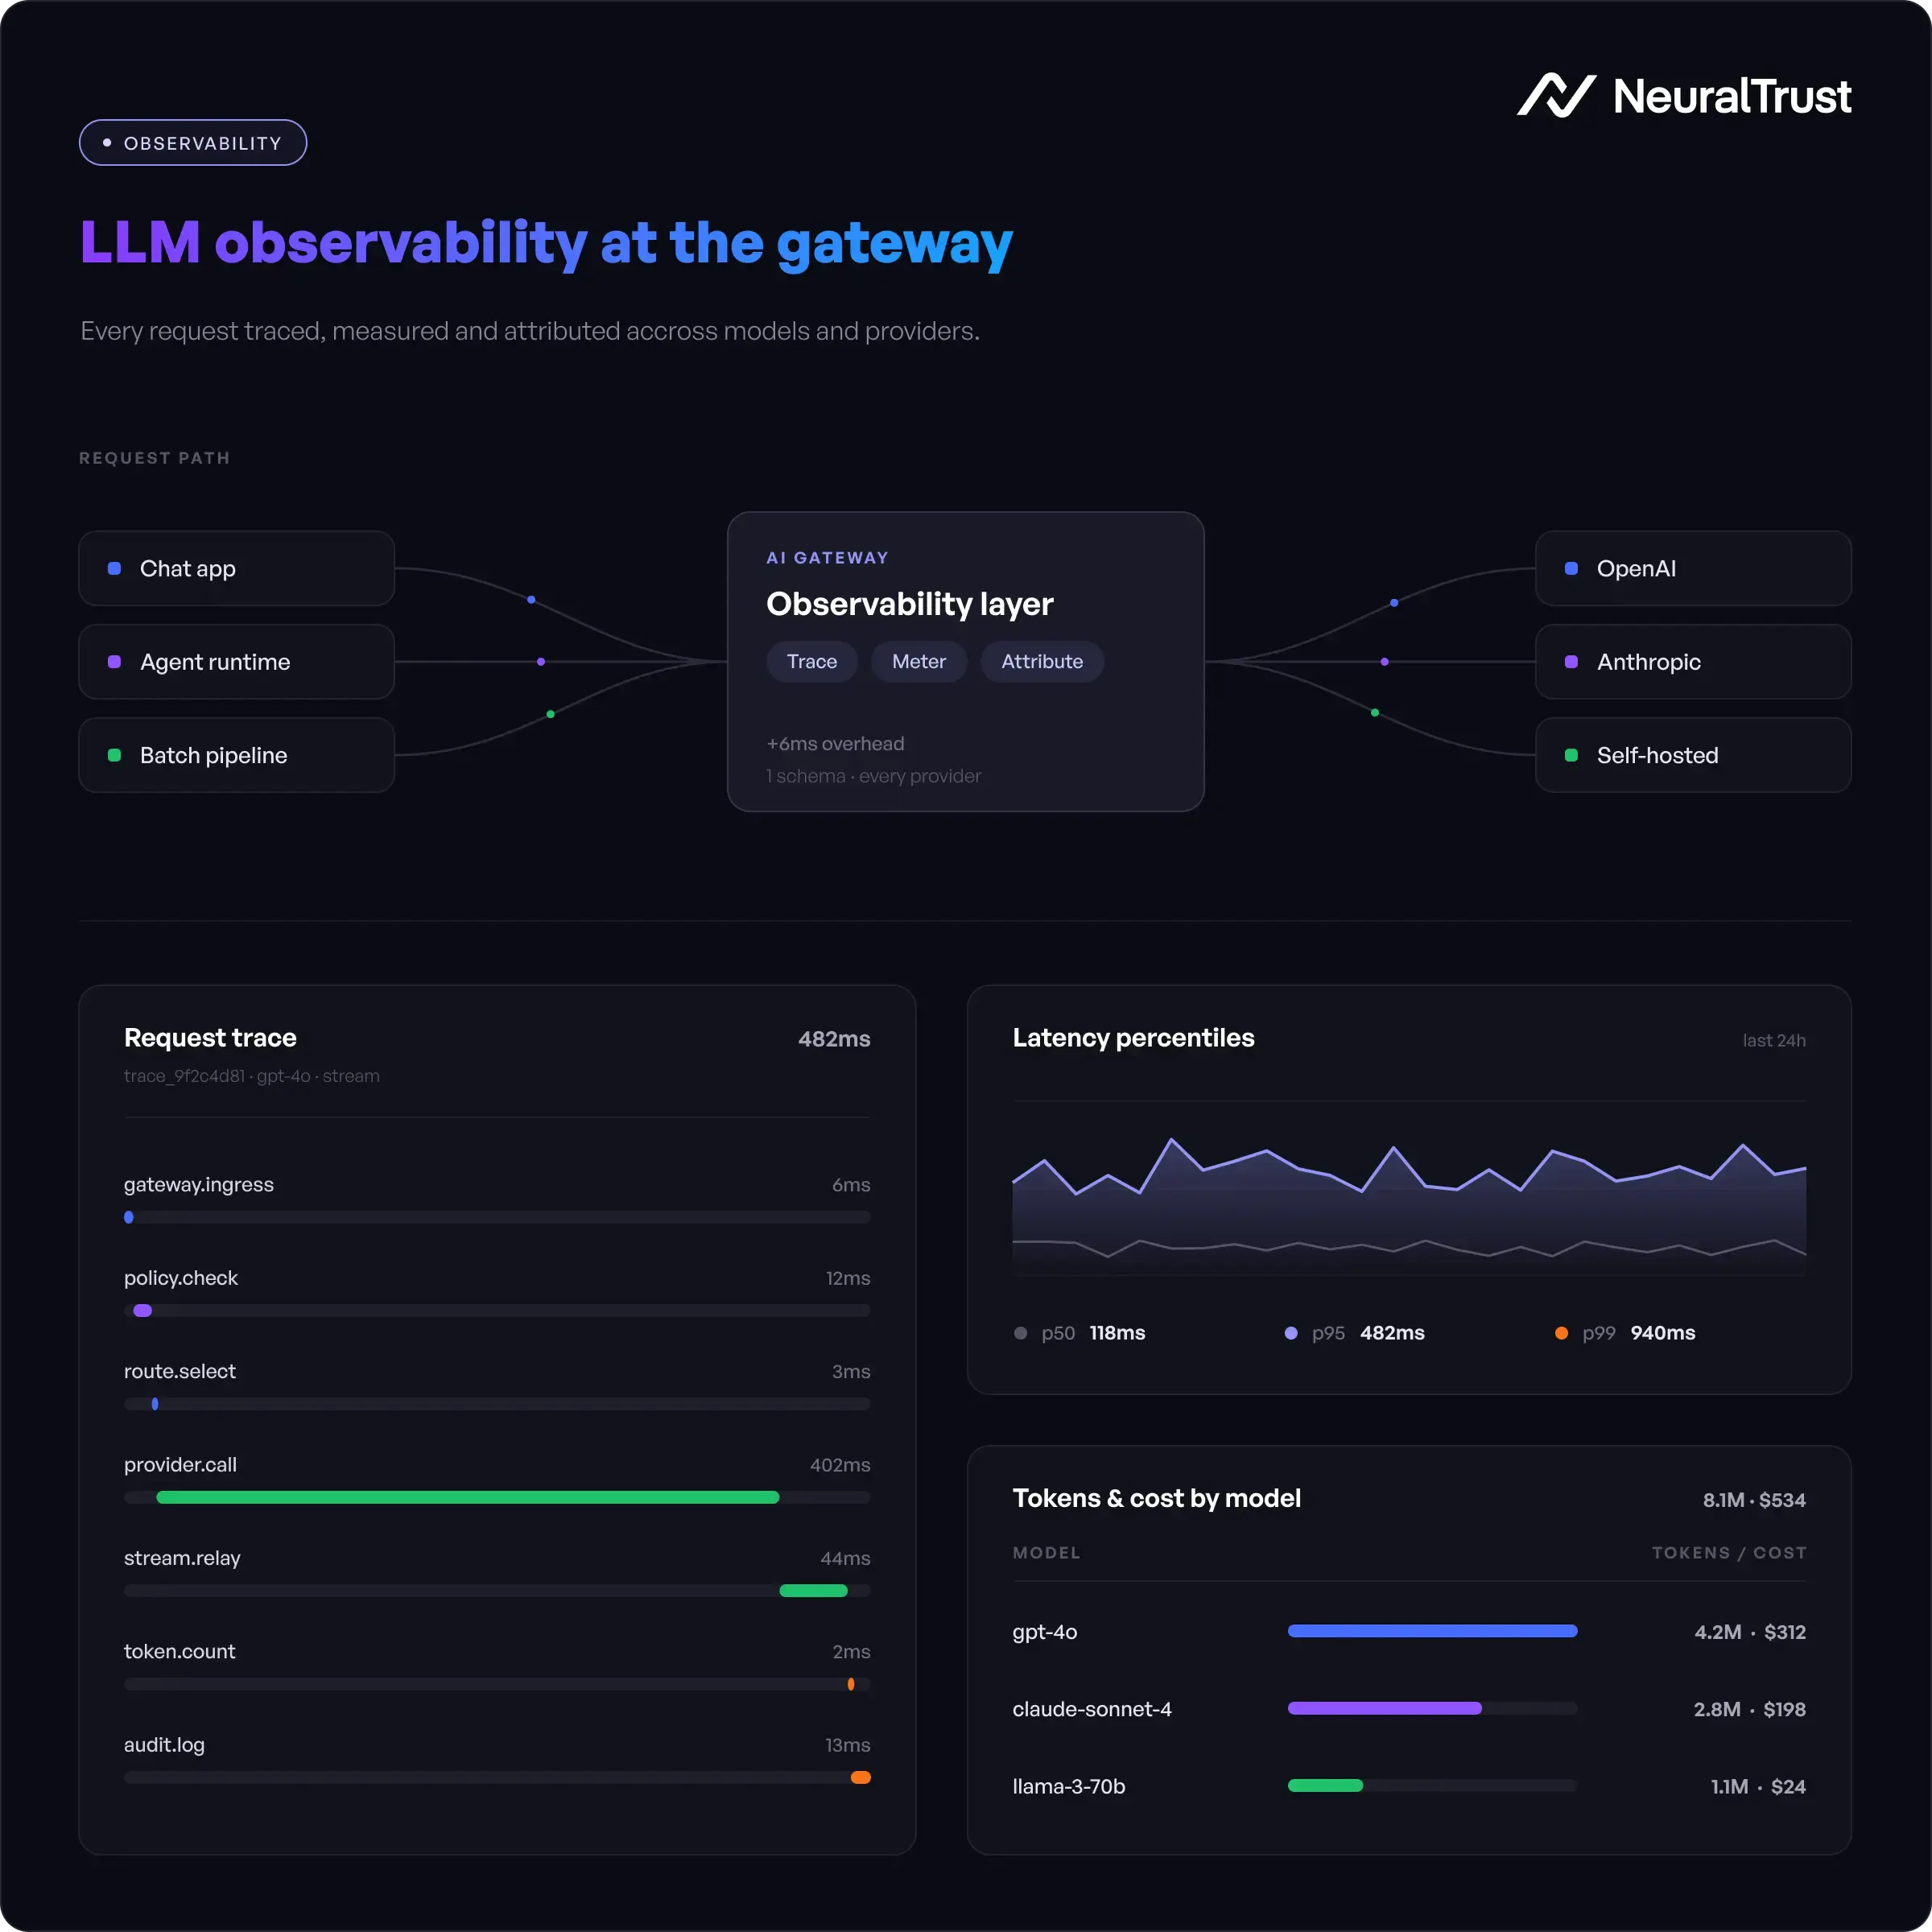
A request that takes 200ms 95% of the time and 8,000ms 5% of the time has a fine average and a terrible user experience. Percentile tracking, specifically p50, p95, and p99, tells the real story: the typical case, the near-worst case, and the actual worst case.
Tracking latency at the provider level reveals which model is slow. At the team level, it reveals who is running complex queries that inflate response times. At the request level, it helps you identify which prompt structures produce the worst latency. See how AI gateway architecture captures this data.
Token Tracking as Cost Control
Tokens are the unit of LLM cost. Most teams find out they have a token problem on their cloud bill. By then, it is already expensive.
Gateway-level token tracking gives you real-time visibility: how many tokens each application is consuming, which user or team is the highest consumer, and whether individual request token counts are within expected ranges. Outliers are often broken agents running in loops or prompts that are dramatically longer than intended.
This feeds directly into LLM cost optimisation: once you know which requests use the most tokens, you can route them to cheaper models or restructure the prompts.
Why OpenTelemetry Matters Here
OpenTelemetry has become the industry standard for distributed tracing. It gives you a common format for spans, traces, and metrics that works across observability backends: Datadog, Grafana, Prometheus, and others.
A gateway that emits OpenTelemetry-compatible traces means you get LLM observability data in the same format as the rest of your infrastructure observability. No separate toolchain for AI. One unified view.
This is the integration model that scales. Your platform team does not want to maintain a separate observability stack for AI. They want LLM traces in the same place as their service traces.
TrustGate + TrustLens: Observability in Practice
TrustGate is NeuralTrust's open-source AI gateway. At the data plane level, it captures every request and response: latency, token counts, model used, routing decision, policy outcomes, cost estimate, and the full trace. No application-level instrumentation required.
TrustLens is NeuralTrust's agent posture management product. It works alongside TrustGate to provide full lifecycle AI observability: not just individual request metrics, but the behavioural patterns of agents over time, including which agents are consuming unexpected resources, making unusual API calls, or deviating from their expected access patterns.
Together they give you two layers: request-level observability through TrustGate, and agent-level posture intelligence through TrustLens.
View TrustGate on GitHub | TrustGate product page | TrustLens product page
Try TrustGate Free
No sales call. No credit card. Sign up, deploy TrustGate in your own environment, and see your full LLM traffic in real time within minutes.
The Full AI Gateway Series
- What Is an AI Gateway? Complete Guide
- AI Gateway vs MCP Gateway
- AI Gateway Security: Protecting LLM Traffic
- AI Gateway Architecture: How It Works Under the Hood
- How an AI Gateway Reduces LLM Costs
- AI Gateways vs API Gateways: The Differences
- Centralized AI Management at Scale
- AI Gateways and Data Sovereignty
- Best AI Gateways in 2026
- AI Gateway vs Guardrails: What You Actually Need
FAQs about how an AI Gateway solves LLM observability
1. What is LLM observability?
LLM observability is the practice of monitoring every request, response, token, and cost flowing through your AI applications in real time. It covers latency at the model and provider level, token consumption by team or user, cost attribution by application, error and fallback rates, and anomaly detection for unusual traffic patterns.
2. How do you monitor LLM performance in production?
The most complete approach is a gateway-layer monitoring setup: every LLM request passes through the gateway, which captures latency, token usage, model used, routing decision, and policy outcomes automatically. Application-level SDK instrumentation only covers individual apps and misses cross-model and cross-team visibility.
3. What metrics should I track for LLM applications?
The six core metrics are: request latency at p50/p95/p99, token usage per request, cost per call attributed by team or user, error rate, fallback rate (how often requests hit your fallback chain), and anomaly alerts for unusual volume or cost spikes. Track all six at the aggregate level, not just per-application.
4. How does an AI gateway provide observability?
An AI gateway sits between all your applications and all your LLM providers. Every request passes through it, so it captures the complete picture: who called which model, how long it took, how many tokens it used, what it cost, and whether it triggered any policies. No application changes required.
5. What is the difference between LLM observability and traditional APM?
Traditional APM was built for deterministic software: same input, same output. LLMs are non-deterministic. Token counts vary, responses vary, models can change via routing, and costs are consumption-based rather than fixed. LLM observability tracks these specific dimensions that standard APM tools were not designed to capture.
About the Author
Roger Howroyd is Head of Global SEO and AI at NeuralTrust, where he leads the company's search strategy across SEO, AEO, GEO, and LLM optimization. He specializes in AI-powered search, content strategy, and SEM. Connect on LinkedIn.
NeuralTrust is an AI agent security platform recognized in the Gartner Hype Cycle for Application Security 2026, the Gartner Market Guide for AI Gateways, and the KuppingerCole Leadership Compass for Generative AI Defense. ISO 27001 certified. Headquartered in Barcelona.