Last updated: September 2026
What is Claude Mythos Capybara?
Claude Mythos (codename "Capybara") is Anthropic's next-generation AI model, accidentally disclosed in early 2025 when a CMS misconfiguration made 3,000 internal assets temporarily public. Internal Anthropic documents describe it as "a step change" above Claude Opus, and assess it as "currently far ahead of any other AI model in cyber capabilities." It is the model name, and its primary security concern is its potential for offensive cybersecurity misuse by adversarial actors.
TL;DR - Key Takeaways
- Claude Mythos (codenamed "Capybara") is Anthropic's most capable AI model to date, described in leaked internal documents as "a step change" in performance that surpasses their previous Opus flagship across coding, reasoning, and cybersecurity benchmarks.
- The disclosure was accidental, not a breach. A CMS misconfiguration set approximately 3,000 digital assets to public by default, including a draft blog post describing the model in detail.
- Anthropic's own assessment is alarming: internal documents state the model is "currently far ahead of any other AI model in cyber capabilities" and could enable attacks that "far outpace the efforts of defenders."
- Claude Mythos is not a jailbreak technique. It is a model name. The actual concern is the model's offensive cybersecurity potential when misused by adversarial actors.
- The risk is industry-wide: OpenAI classified GPT-5.3-Codex under a similar "high capability" cybersecurity tier in the same period. This is not a one-company problem.
- Security teams need immediate action: gateway-layer controls, agent posture monitoring, and API access policies are the first line of defence.
In early 2025, Anthropic made an unintended disclosure. A misconfiguration in their content management system briefly set thousands of internal digital assets to public — including a draft blog post that described their next-generation model, Claude Mythos, in unusually candid terms.
The document was quickly taken down. But the contents had already been indexed, screenshotted, and circulated across the AI security community.
What it revealed was not a scandal about AI safety practices. It was something more specific: a model that Anthropic's own internal teams assessed as having cybersecurity capabilities that go beyond what current enterprise defences are built to handle.
This article covers what was actually in the leaked documents, what Claude Mythos is (and is not), the genuine security implications for enterprise teams, and what your organisation should be doing about frontier AI capabilities right now.
What Is Claude Mythos?
Claude Mythos, internally codenamed "Capybara" during development, is Anthropic's next-generation large language model, positioned as a new capability tier above their Claude Opus family. Based on the leaked internal documents, it represents what Anthropic described as "a step change" in performance rather than an incremental improvement.
The model was described across three primary capability dimensions:
- Software coding: described as "dramatically higher" than Opus, with improved performance on complex multi-file refactoring and autonomous debugging tasks
- Academic and analytical reasoning: assessed as a meaningful step forward on graduate-level reasoning benchmarks
- Cybersecurity tasks: the most consequential assessment: internal documents stated Mythos is "currently far ahead of any other AI model in cyber capabilities"
That last point is what drew significant attention from the AI security community, not because it was unexpected for a frontier model to be highly capable, but because the framing came from Anthropic's own internal risk assessment, not from an external researcher or adversarial test.
Important clarification: Claude Mythos is a model, not a jailbreak technique. If you are researching methods for bypassing Claude's safety systems, that is a separate topic covered in our analysis of constitutional classifiers and prompt injection techniques. Searches for "Claude Mythos jailbreak" are based on a misreading of what the term refers to.
How the Leak Happened?
The Claude Mythos disclosure was not a data breach. No external actor exploited a vulnerability or accessed Anthropic's internal systems. Instead, it was a CMS misconfiguration, a settings error that changed the default visibility of assets from private to public.
The result: approximately 3,000 digital assets, including draft blog posts, images, diagrams, PDFs, and audio files, became publicly accessible for a period before the error was detected and reversed.
The draft blog post describing Claude Mythos was among the exposed assets. Once indexed by search engines and surfaced on social platforms, it spread faster than Anthropic could respond.
What Was Exposed?
| Asset Type | Estimated Volume | Sensitivity |
|---|---|---|
| Draft blog posts (including Claude Mythos announcement) | Unknown | High: contained internal model assessments |
| Images and diagrams | 3,000 total assets | Low-Medium |
| PDF documents | Unknown subset | Variable |
| Audio files | Unknown subset | Low |
Why This Matters Beyond the Headline?
The security significance here is not simply "Anthropic had a data leak." It is that a CMS misconfiguration (one of the most common categories of cloud security failure) created an unplanned public disclosure of sensitive model capability information.
For enterprise security teams, this serves as a reminder that your AI providers' operational security posture directly affects your own risk profile. A vendor's misconfigured asset store can surface information about capabilities, roadmaps, or security assessments that your threat model did not account for.
Claude Mythos Capabilities: What the Benchmarks Reveal
The leaked document did not publish full benchmark scores in the format of a standard model card. What it contained were internal assessments written for a non-technical audience, which means the language used was qualitative, directional, and in some places deliberately vague.
With that caveat, here is what was described:
Performance Overview (Based on Leaked Internal Assessments)
| Capability Category | Claude Opus (Previous Flagship) | Claude Mythos / Capybara | Source |
|---|---|---|---|
| Software Coding | State-of-the-art for its generation | "Dramatically higher" | Internal Anthropic document |
| Academic Reasoning | Competitive with GPT-4 class models | "Step change" improvement | Internal Anthropic document |
| Cybersecurity Tasks | Strong but within defender range | "Far ahead of any other AI model" | Internal Anthropic document |
| Vulnerability Discovery | Capable at known pattern matching | Can "exploit vulnerabilities in ways that far outpace defenders" | Internal Anthropic document |
| General Intelligence | Anthropic's flagship tier | New tier above Opus | Internal Anthropic document |
Claude Model Family Comparison
| Model | Tier | Public Availability | Cybersecurity Risk Level |
|---|---|---|---|
| Claude Haiku | Entry | Generally available | Low |
| Claude Sonnet | Mid-range | Generally available | Low-Medium |
| Claude Opus | Flagship | Generally available | Medium |
| Claude Mythos / Capybara | Frontier, new tier | Early access (defenders first) | High - Anthropic's own assessment |
Anthropic's stated access strategy prioritises giving security researchers and defensive tooling teams early access before broader availability. This mirrors the approach taken with some previous capability releases and is consistent with their stated responsible scaling policy.
The Dual-Use Dilemma: Cybersecurity Risks of Frontier AI
The core tension that Claude Mythos makes visible is not new, but Mythos makes it impossible to ignore: the capabilities that make a frontier AI model useful for defence are structurally identical to the capabilities that make it dangerous in adversarial hands.
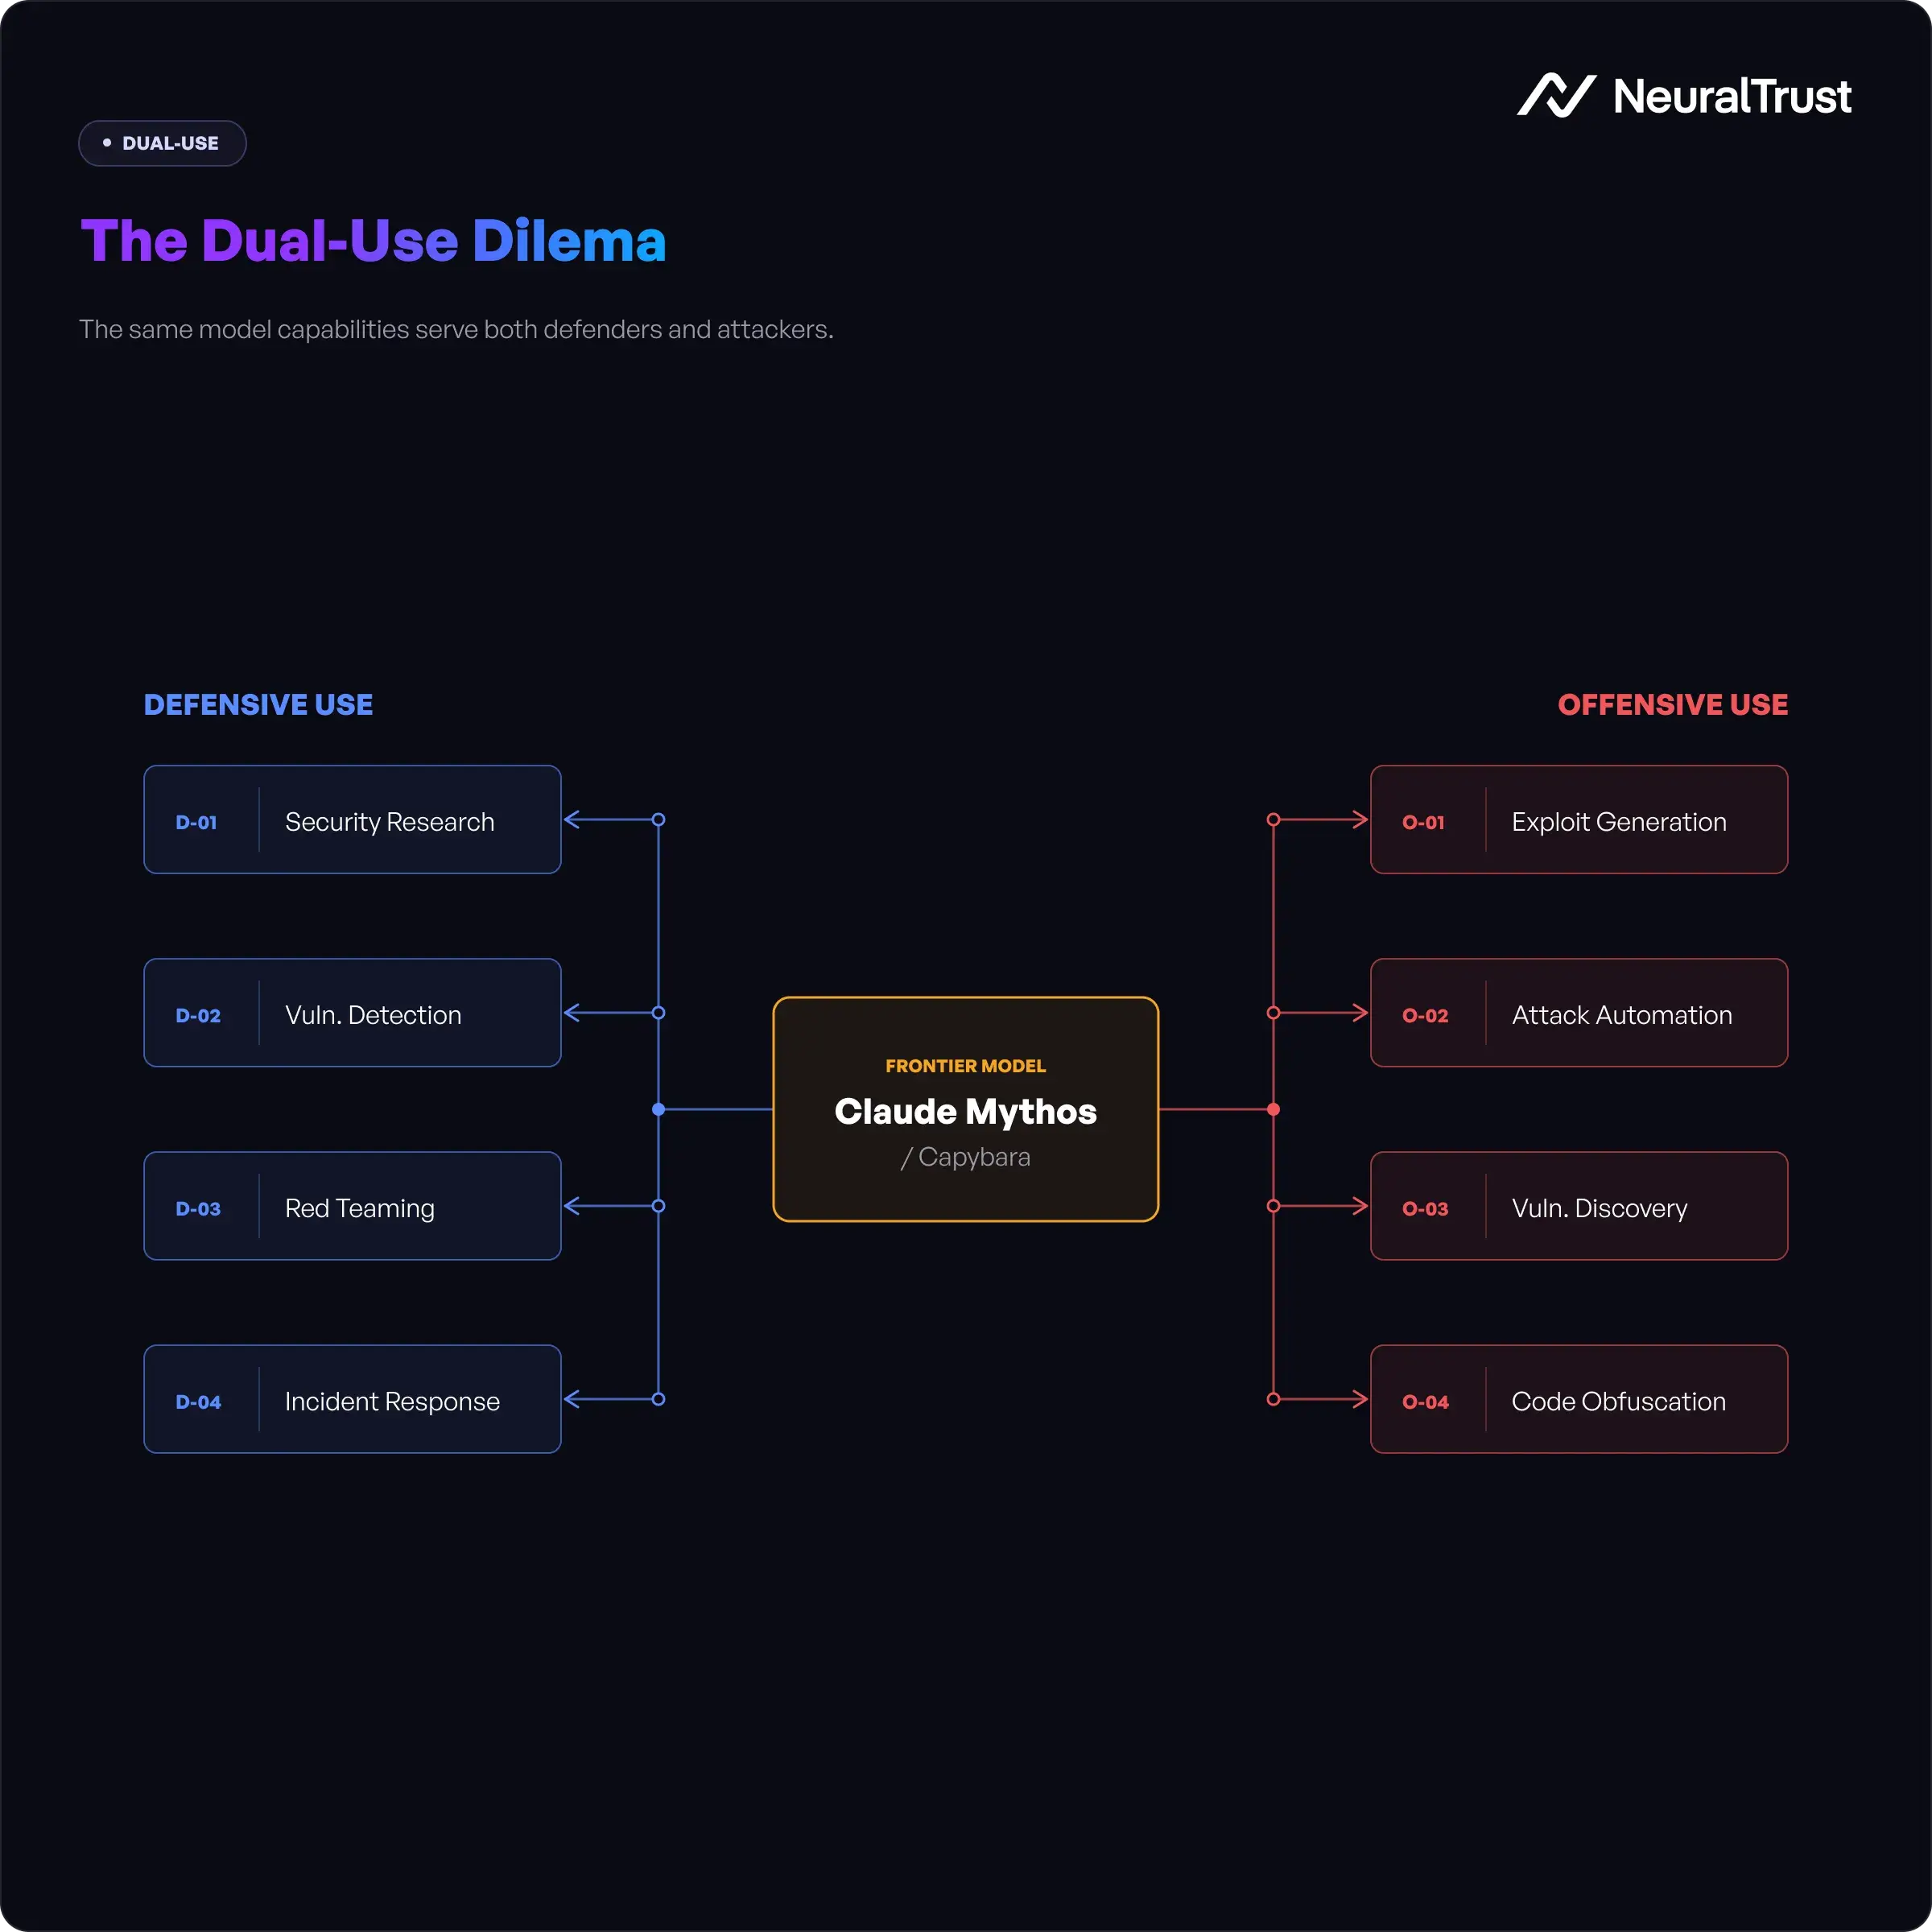
A model that can identify a vulnerability in a codebase to help a red team also identifies that same vulnerability for a threat actor. A model that can write exploit code to test a system can write exploit code to attack one. The capability is the same; the access controls and intent differ.
Anthropic's internal documents apparently acknowledged this directly, describing a scenario where Mythos-level capability could "enable attacks that far outpace the efforts of defenders." That is a significant statement to find in an internal model announcement document, it suggests Anthropic's own teams were actively wrestling with the dual-use risk at the point of release planning, not retrospectively.
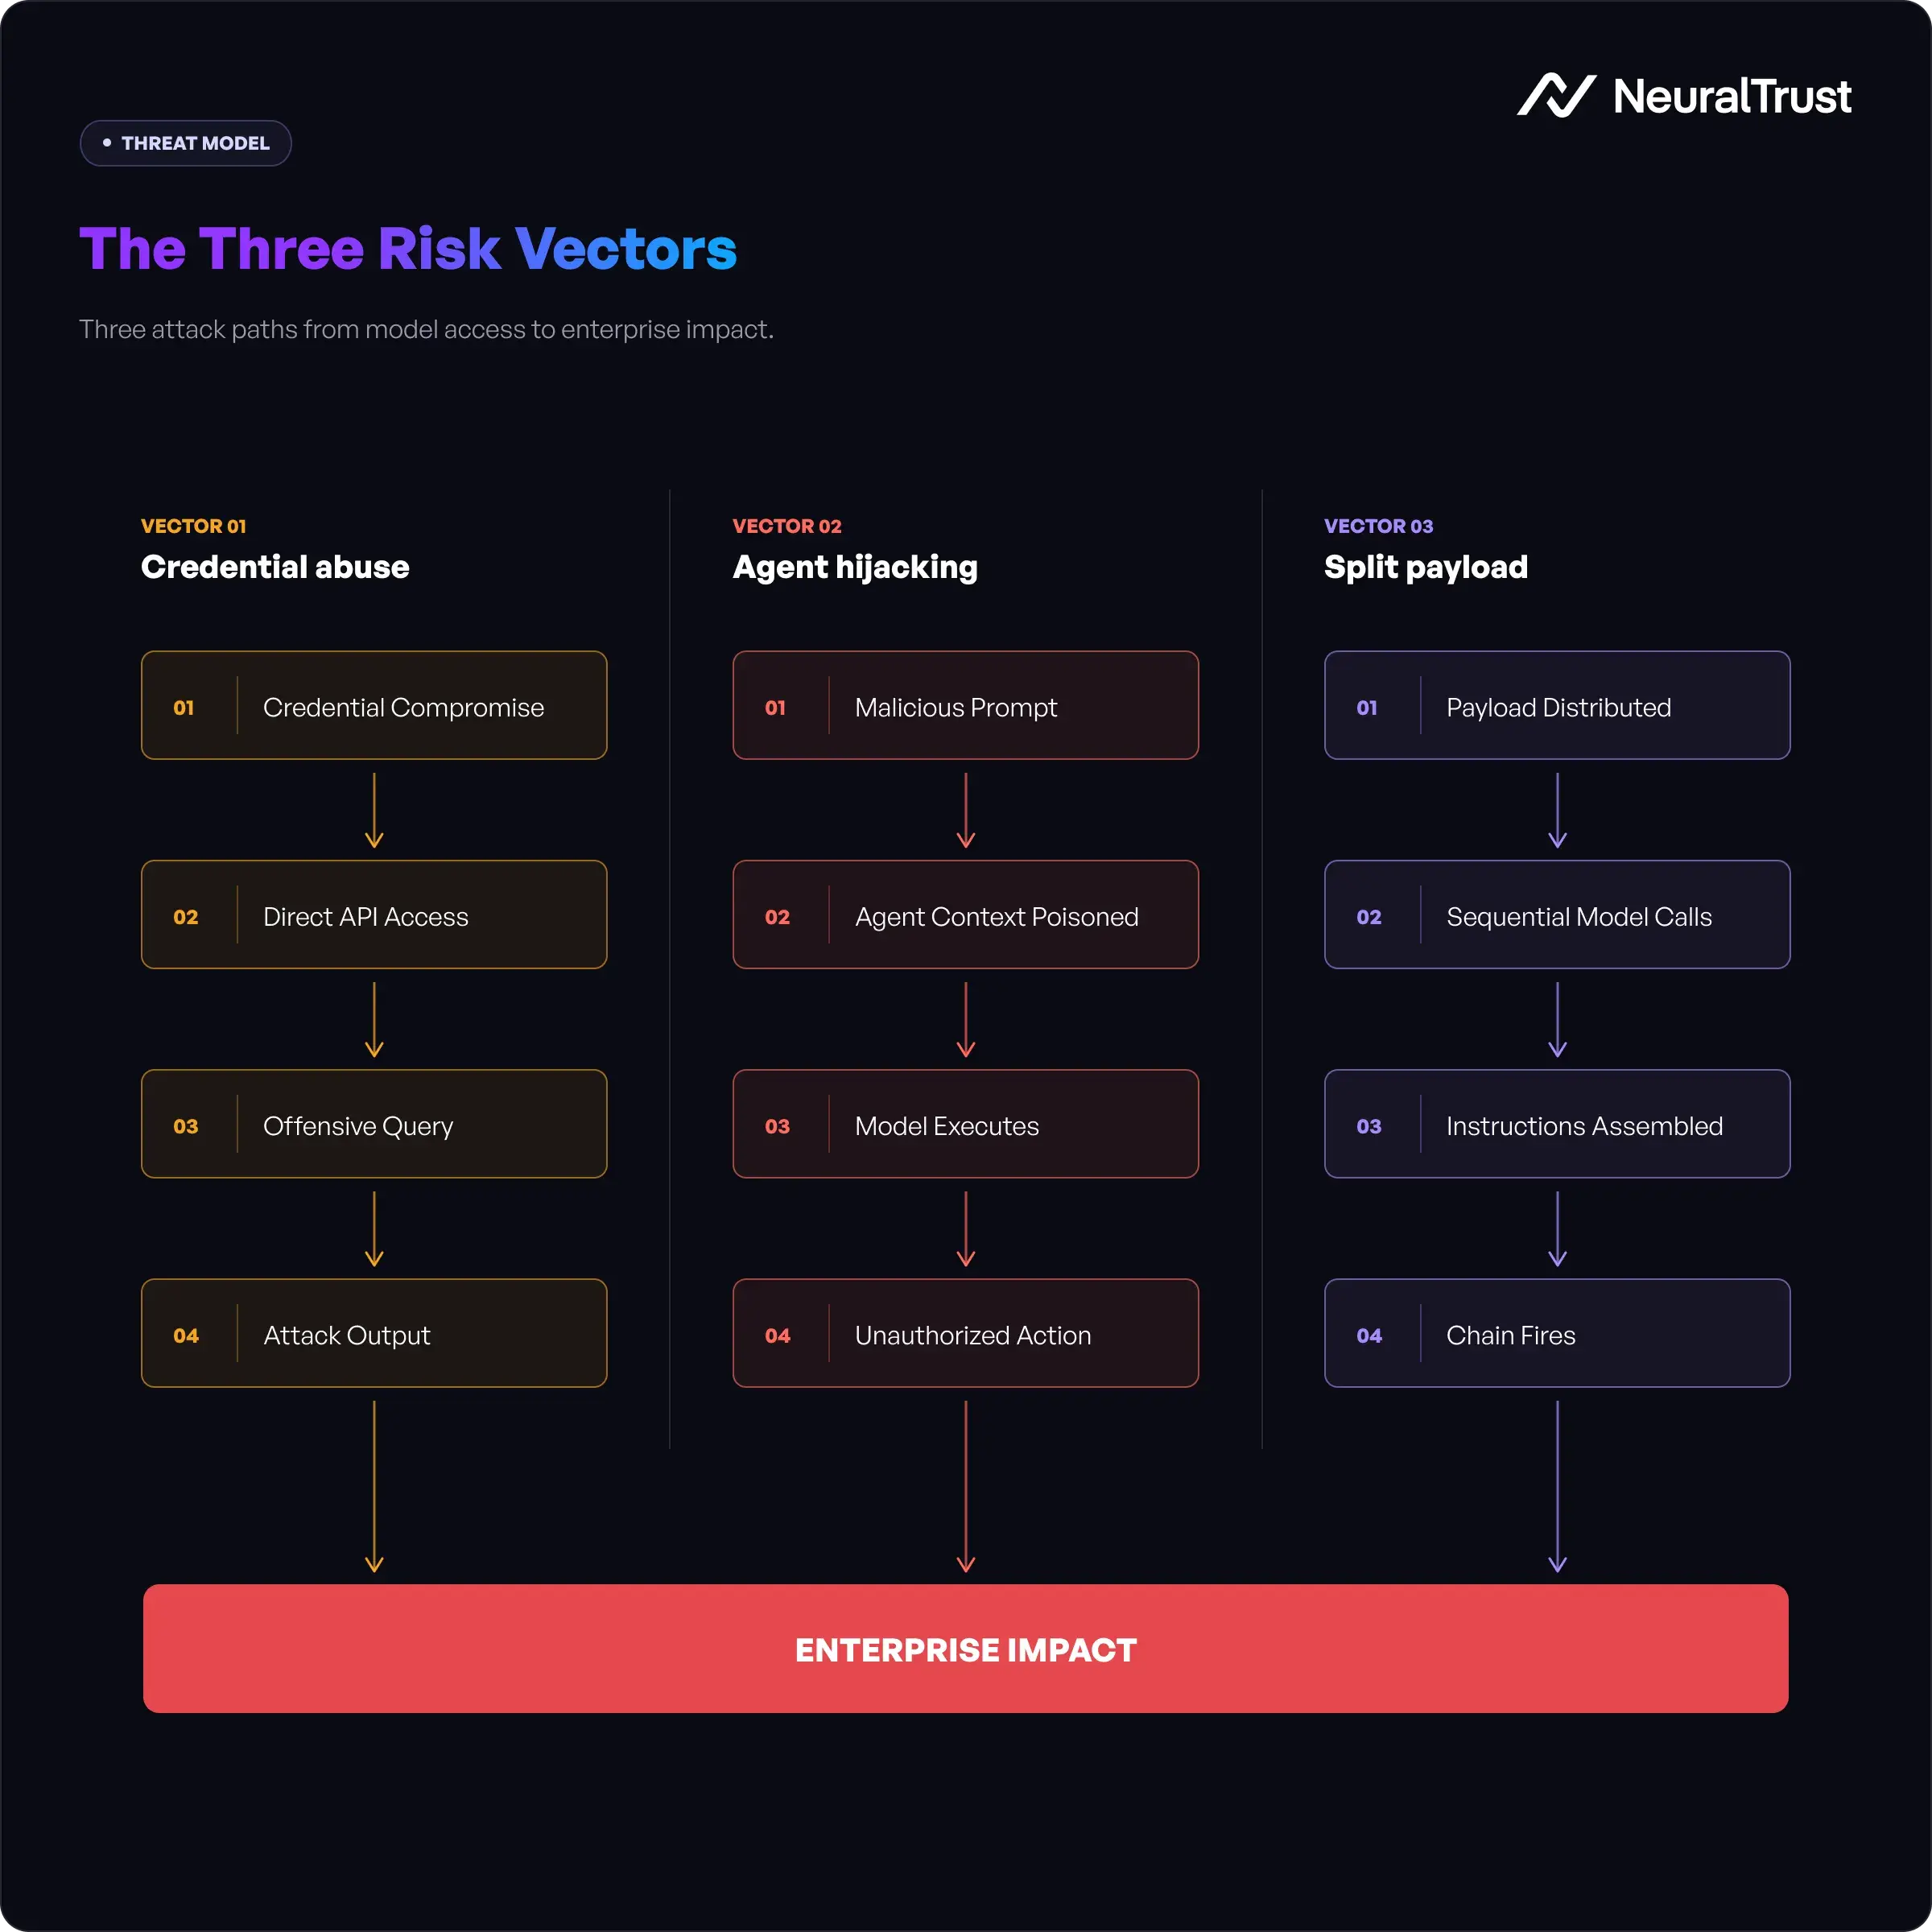
The Three Risk Vectors for Enterprise Security Teams
1. Direct API misuse
Threat actors obtaining Mythos API access — through credential theft, account compromise, or eventually through public availability — gain access to a cybersecurity capability tier that current detection systems were not designed to handle. The relevant question is not whether your perimeter blocks known attack signatures, but whether it can detect attacks generated by a model that outpaces your defenders.
2. Prompt injection via Mythos-powered agents
As Mythos-class models are integrated into autonomous agents and enterprise workflows, the attack surface for prompt injection attacks increases. A more capable model is also a more capable target: an attacker who can manipulate a Mythos-powered agent's context has access to a significantly more powerful execution environment than they would with a base Sonnet or Opus deployment.
3. Semantic chaining in multi-agent pipelines
Semantic chaining attacks — where malicious instructions are distributed across multiple model calls and only execute when assembled — become more viable as model capability increases. Mythos-level reasoning may be able to reconstruct and execute chained instructions that less capable models would fail to synthesise.
A Shared Responsibility: The Industry Is Not Alone
It is important to situate Claude Mythos within the broader trajectory of frontier AI development, not treat it as an isolated Anthropic problem.
In the same period that the Mythos documents circulated, OpenAI classified GPT-5.3-Codex under a "high capability" cybersecurity tier in their internal safety evaluations, acknowledging analogous concerns about offensive capability potential. Google DeepMind's Gemini Ultra assessments reference similar dual-use considerations in their model cards.
The pattern is consistent: as models cross certain capability thresholds, the gap between what they can do for defenders and what they enable for attackers narrows, and the risk surface expands.
This has three practical implications for enterprise security teams:
- Your AI provider's safety practices are now a third-party risk question. How Anthropic manages access to Mythos, how they monitor for misuse, and how they respond to incidents involving the model are all relevant inputs to your vendor risk assessment.
- Industry frameworks are behind the capability curve. Current AI security standards (including NIST AI RMF and OWASP LLM Top 10) were largely developed against a generation of models that predate Mythos-class capability. Your controls need to anticipate the current frontier, not the models the frameworks were written for.
- Collective early warning matters. The AI security community's rapid surfacing and analysis of the Mythos leak is the kind of shared intelligence function that enterprise teams should be plugged into.
What Security Teams Need to Do Now
The Claude Mythos disclosure is a prompt to act, not a reason to wait for regulatory guidance or vendor-provided controls. Here is where to focus:
1. Audit Your AI Gateway Configuration
Your AI gateway is the first line of control over which models your organisation can access, under what conditions, and with what logging. If your gateway was configured before Mythos-class models entered the picture, it almost certainly needs updating.
TrustGate provides policy enforcement, request filtering, and model access controls that can be scoped to your organisation's risk tolerance — including blocking access to specific model tiers or requiring additional approval workflows for frontier model access.
2. Implement Agent Posture Monitoring
If your organisation is running AI agents, you need continuous visibility into what those agents are doing, what context they are operating with, and whether their behaviour has drifted from expected parameters.
TrustLens provides agent posture management: real-time monitoring of agent behaviour, anomaly detection, and audit trails that give your security team the visibility needed to identify prompt injection attempts, semantic chaining, and unexpected agent actions before they cause damage.
3. Red Team Your AI Stack Against Frontier Capabilities
Your current AI security posture was likely tested against models and attack patterns that predate Mythos-class capability. Red teaming against yesterday's threat model gives you false confidence.
TrustTest provides AI-native red teaming that tests your models, agents, and workflows against current frontier attack techniques, including the categories of attack that Mythos-level capability makes more viable.
4. Review Your LLM Provider Agreements
Your contracts with AI providers should address three things that the Mythos incident makes newly relevant:
- Data use restrictions: confirmation that your inputs are not used to train future models, including Mythos-class systems
- Incident notification timelines: an explicit commitment to notify you within 72 hours of a security incident affecting your deployment
- Audit rights: the ability to verify that the provider's security controls meet your organisation's standards
If your current agreements do not address these points, the Mythos disclosure gives you a specific, timely reason to request updated terms.
5. Enforce Security-by-Design for All AI Deployments
Every new AI deployment should go through a security review that explicitly addresses:
- Which model tier it uses, and what that tier's known capability risks are
- What data the model can access, and whether that access is appropriately scoped
- What actions the model or agent can take, and whether those actions have appropriate guardrails
- How the deployment will be monitored for anomalous behaviour post-launch
Mythos-class capability raises the stakes on each of these questions. Deploying a frontier model without addressing them is an unmanaged risk.
FAQs about Claude Mythos
1. What is Claude Mythos?
Claude Mythos is the name used in leaked Anthropic internal documents to describe their next-generation large language model, positioned as a new capability tier above Claude Opus. It is also referred to by the internal development codename "Capybara."
2. Is Claude Mythos available to the public?
As of the time of writing, Claude Mythos has not been released for general availability. Anthropic's stated approach is to provide early access to security researchers and defensive tooling teams before broader release.
3. What is "Capybara" in relation to Claude Mythos?
"Capybara" is the internal development codename that Anthropic used for the model during its development phase. "Claude Mythos" appears to be the intended public-facing name, as described in the leaked draft blog post.
4. Is Claude Mythos a jailbreak technique?
No. Claude Mythos is a model name, not a method for bypassing Claude's safety systems. The confusion likely arises because searches for AI "jailbreak" techniques often surface results about frontier model capabilities. If you are researching Claude safety bypass techniques, see our coverage of constitutional classifiers and prompt injection.
5. How did the Claude Mythos leak happen?
A CMS misconfiguration at Anthropic temporarily set approximately 3,000 internal digital assets to public visibility, including a draft blog post describing Claude Mythos. This was not an external breach — no attacker accessed Anthropic's systems. The error was detected and reversed, but not before the content was indexed and distributed.
6. What makes Claude Mythos dangerous from a cybersecurity perspective?
According to Anthropic's own internal documents, Claude Mythos is "currently far ahead of any other AI model in cyber capabilities" and could enable attacks that "far outpace the efforts of defenders." The concern is not that the model is inherently malicious — it is that its capabilities, if accessed by adversarial actors, represent a significant upgrade to the offensive toolkit available to threat actors.
7. Have threat actors already used Claude models in attacks?
Anthropic and other AI providers have publicly disclosed instances of threat actors attempting to use their models for malicious purposes — primarily for reconnaissance, social engineering content generation, and code assistance for malware. These disclosures predate Mythos. The question of whether Mythos-class capability has been weaponised in active campaigns is not yet publicly documented.
8. How does Claude Mythos compare to OpenAI's GPT-5.3-Codex?
Both models have been classified internally by their respective developers as representing a "high capability" cybersecurity tier. OpenAI's internal evaluations for GPT-5.3-Codex acknowledged analogous dual-use concerns. Neither company has provided public benchmarks that allow a direct capability comparison. What both disclosures share is that their own developers flagged significant offensive cybersecurity potential.
9. What should enterprise security teams do in response to Claude Mythos?
Immediate priorities: audit your AI gateway configuration, implement agent posture monitoring, red team your AI stack against frontier-level attack patterns, review your LLM provider contracts, and enforce security-by-design for all new AI deployments. Longer term, ensure your AI security framework is calibrated to the current capability frontier, not the generation of models that existing standards were written for.
10. What is the dual-use dilemma in AI security?
The dual-use dilemma refers to the fact that the capabilities that make frontier AI models useful for defensive security work — vulnerability identification, code analysis, attack simulation — are structurally identical to the capabilities that make them valuable for offensive use. You cannot build a model that is excellent at finding security flaws and simultaneously useless for exploiting them. Managing this tension is one of the central challenges of responsible frontier AI deployment.
Closing Thought
The Claude Mythos leak was a configuration error. But the content it exposed describes something more consequential: a model that, by Anthropic's own internal assessment, has cybersecurity capabilities that outpace the defences of most organisations.
The question for security teams is not whether Mythos-class capability will eventually be in adversarial hands. The trajectory of AI development makes that outcome likely. The question is whether your AI gateway, your agent monitoring, and your provider agreements are in place before that happens — or after.
The organisations that treat this as a prompt to act rather than a news story to follow will be better positioned when the next disclosure arrives.
Related articles
- How Claude Mythos is Hardening Firefox at Machine Speed
- Claude Opus 5.5 Enterprise Security: Safeguards & Gaps
- Claude Opus 5 Security & Safety
- Claude Sonnet 5 Security and Safety: A System Card Analysis for Agent Deployments
- Claude Opus 4.6: Engineering AI Safety
- GPT-6 Astra Security Implications: The CISO's Guide
- OpenAI Daybreak: The Dawn of Agentic Cybersecurity
About the Author
Alessandro Pignati is Lead AI Security Researcher at NeuralTrust, where he leads research on AI and agentic security, advancing techniques to evaluate and secure large language models and autonomous AI systems. He specializes in adversarial machine learning, AI red teaming, LLM security, and AI safety, contributing to the development of secure and trustworthy AI.
NeuralTrust is an AI agent security platform, recognized in the Gartner 2025 Market Guide for AI Gateways and Guardian Agents, and the KuppingerCole 2025 Leadership Compass for Generative AI Defense. Headquartered in Barcelona with ISO 27001 certification.