Last updated: September 2026
Is Claude down right now?
Check status.claude.com, Anthropic's official status page, which reports claude.ai, the Claude API, Claude Code, Claude Cowork and the Console separately. If a component shows an incident, the problem is on Anthropic's side and retrying later is the only fix. If everything is green, the cause is usually your rate limit, your key or your network.
That answers today's outage. This guide also explains each Claude error, what to do while you wait and what September 2026's incidents looked like. Then it shows how to set up model fallback, so the next outage does not stop your team.
TL;DR: Key Takeaways
- Check first: status.claude.com lists six components: claude.ai, Claude Console, Claude API, Claude Code, Claude Cowork and Claude for Government.
- Read the error: a 529
overloaded_erroror 500api_erroris on Anthropic's side; a 429rate_limit_errorusually means your own limit, per the Claude API errors reference. - It happens to everyone: on September 3, 2026, ChatGPT, Claude and Grok had outages on the same morning, according to The Register.
- Outages are short but frequent: AI model providers resolved incidents in a 49-minute median in 2026, per StackGen's State of Reliability Report 2026, as reported by Continuity Insights.
- Fallback is the fix: the Agent Gateway (TrustGate) moves a request to the next provider on HTTP 5xx, 429, timeout or provider error, per the TrustGate routing docs.
- Watch the security gap: 49% of workers already use AI tools without approval, according to a BlackFog survey reported by CIO, and outages push more of them to unsanctioned tools.
Is Claude Down Right Now? How to Check Claude Status
The fastest way to know if Claude is down is Anthropic's own status page. It shows each product as a separate component, so you can see whether the chat app, the API or Claude Code is affected. Third-party trackers add user reports, but they cannot confirm the cause.
The official status page
status.claude.com is the only source that confirms an incident. On September 30, 2026, it listed these components:
| Component | What it covers | Who notices first |
|---|---|---|
| claude.ai | Web, desktop and mobile chat apps | Everyday users |
| Claude Console (platform.claude.com) | API keys, billing, workspaces | Admins and developers |
| Claude API (api.anthropic.com) | Every app and agent built on Claude | Product and platform teams |
| Claude Code | The agentic coding tool in terminals and IDEs | Engineers |
| Claude Cowork | Claude's agent for everyday work tasks | Business users |
| Claude for Government | The dedicated government offering | Public sector teams |
Source: Claude Status, accessed September 30, 2026.
You can subscribe to updates from the same page, and past incidents stay in the incident history.
Third-party trackers
Sites such as StatusGator and isdown mirror the official page and add crowd reports. They are useful when the official page lags behind a spike in errors. During the September 29 incident, Downdetector counted more than 11,800 reports within about 20 minutes, according to TechRadar.
Is it Claude, or is it you?
If the status page is green, check your side before you wait. A red status page plus a 5xx error means Anthropic. A green page plus a 4xx error almost always means your account, key or request.
What Each Claude Error Means
Claude's errors tell you who owns the problem. Server-side errors (500, 504, 529) are Anthropic's and clear up on their own. Client-side errors (400 to 429) come from your account, key or request, and waiting will not fix most of them.
| Code | Error type | What it means | Is Claude down? |
|---|---|---|---|
| 529 | overloaded_error | The API is temporarily overloaded by high traffic | Often yes, or close to it. Retry with backoff |
| 500 | api_error | An unexpected internal error at Anthropic | Likely, if it persists. Retry with backoff |
| 504 | timeout_error | The request timed out during processing | Sometimes. Use streaming for long requests |
| 429 | rate_limit_error | You hit a rate limit or spend cap | Usually no. Honor the retry-after header |
| 400 | invalid_request_error | Bad request, or a spend limit was reached | No. Fix the request or the limit |
| 401 / 403 | authentication_error / permission_error | Invalid key or missing permission | No. Check the key and workspace |
| 402 | billing_error | A payment problem on the account | No. Check billing in the Console |
Source: Claude API errors reference (September 2026).
Two details matter in an outage. First, Anthropic's SDKs already retry connection errors, rate limits and 5xx errors twice with exponential backoff by default, so a failing app has usually retried before you see the error. Second, tier spend-cap 429s "have no retry-after header and persist until access resumes", so a 429 that never clears is a billing problem, not an outage.
In the chat apps, the message is less specific. During the September 29 incident, users saw "Request couldn't be processed. You can try again," per TechRadar. Claude Code calls the same API, so the same error types apply to it.
What to Do When Claude Is Down
When Claude is down, the right move depends on how you use it. Chat users should wait and stay signed in. Developers should pause long agent runs or switch to a Claude deployment on another cloud. API teams should let retries and fallback handle traffic and tell their own users.
If you use claude.ai or the desktop app
- Stay signed in. During the September 29 incident, the login system itself failed, and Anthropic warned signed-in users not to log out, according to Android Authority.
- Save your work. Copy long prompts or drafts before retrying, because a failed request can lose the text you typed.
- Use an approved alternative only. If your company offers a second approved assistant, use it. Do not paste work data into a personal account on another AI tool (more on this in the security section).
If you use Claude Code
- Pause long agent runs. An agent that fails halfway can leave a half-edited repository. Commit or stash first.
- Switch to Claude on another cloud, if your company has one. Claude Code runs on Amazon Bedrock, Google Cloud and Microsoft Foundry. Anthropic "doesn't support routing Claude Code to non-Claude models through any gateway", per the Claude Code LLM gateway docs. So the Claude Code fallback is the same model on another provider.
If you run apps or agents on the Claude API
- Let retries work, then fail over. Backoff handles short blips; a fallback chain handles incidents that last longer than your latency budget.
- Tell your users. Show a status message instead of a generic error, and link to your own status page.
- Protect in-flight jobs. Queue non-urgent batch work until the incident is resolved instead of retrying in a tight loop, which raises your costs and adds load.
Claude Outage History: September 2026
Claude had at least six incidents in September 2026, most of them partial and under three hours. Several hit specific model families rather than all of Claude, which is why a fallback to another Anthropic model sometimes works. The table uses Anthropic's status page and dated press reports.
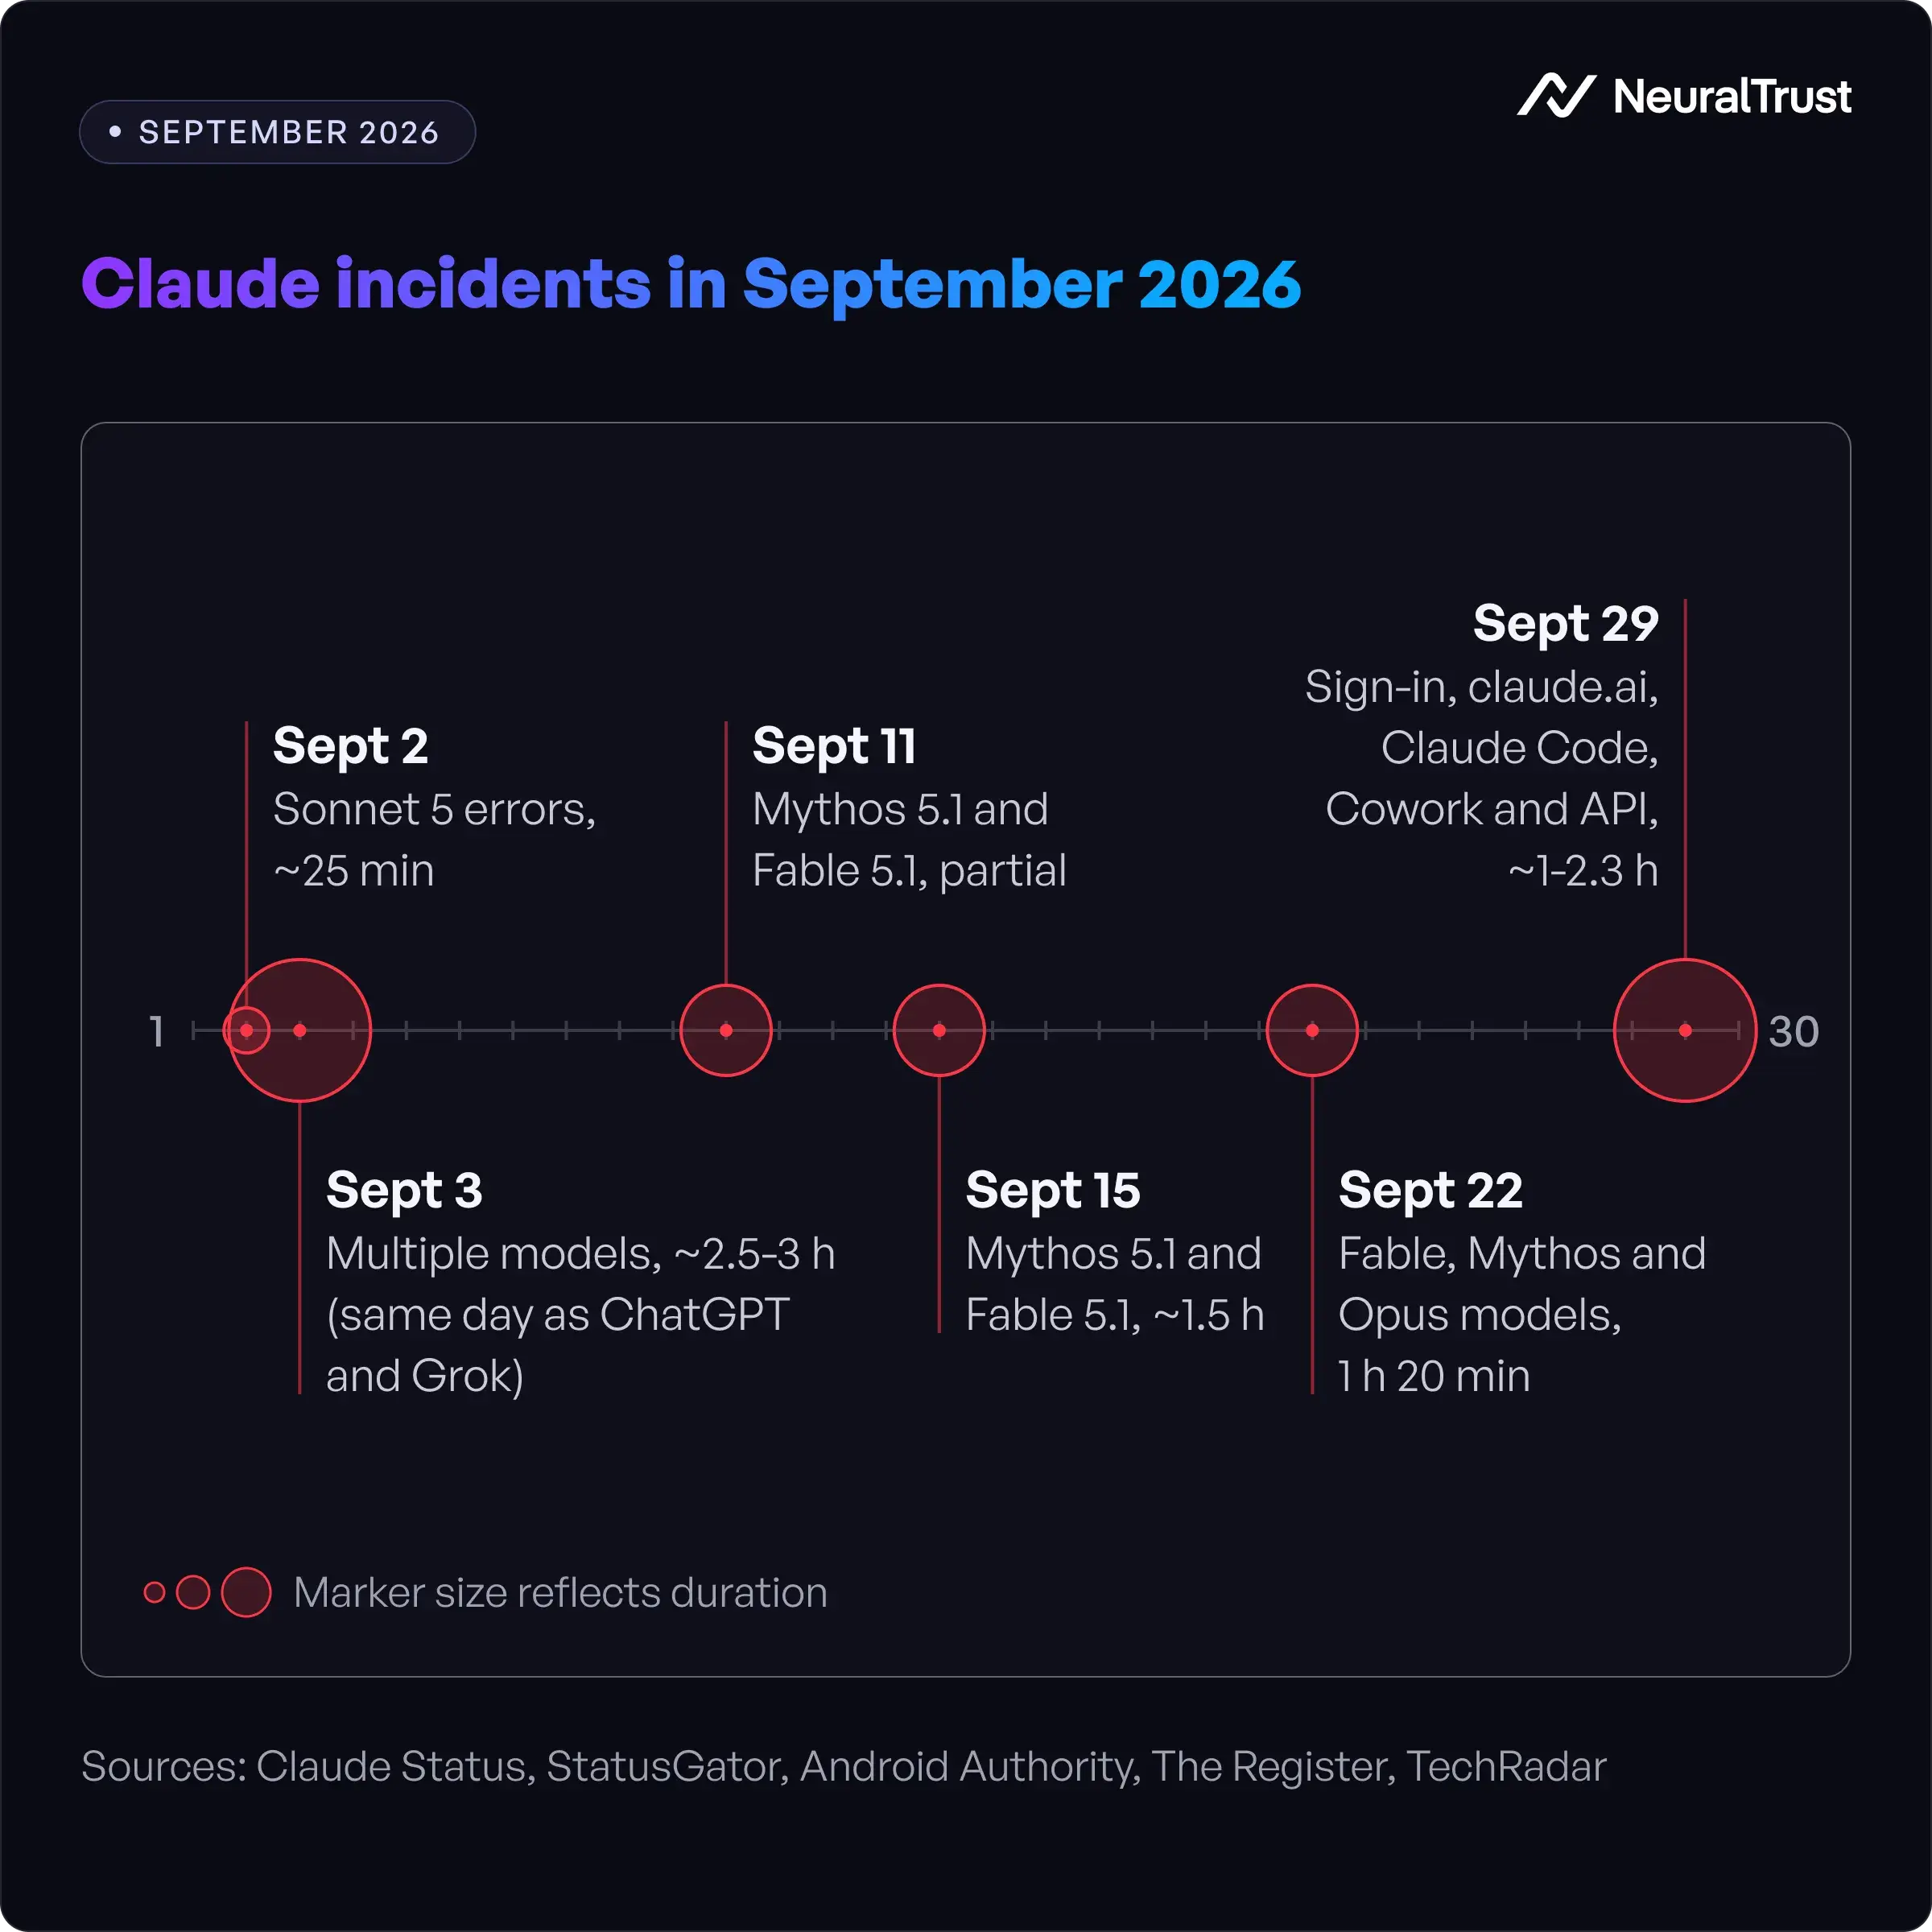
| Date | What failed | Duration | Source |
|---|---|---|---|
| Sept 2 | Brief errors on Sonnet 5 across claude.ai, the API, Claude Code and Cowork | About 25 minutes | StatusGator |
| Sept 3 | Errors on several models, including Mythos 5.1, Fable 5.1 and Opus 5, the same morning as ChatGPT and Grok outages | About 2.5 to 3 hours | Android Authority, The Register |
| Sept 11 | Errors on Mythos 5.1 and Fable 5.1, also affecting the API, Claude Code and Cowork | Partial, logged over several days | StatusGator |
| Sept 15 | Intermittent errors on Mythos 5.1 and Fable 5.1 | About 1.5 hours | StatusGator |
| Sept 22 | Errors for multiple models (Fable, Mythos and Opus versions) | 1 hour 20 minutes | Claude Status |
| Sept 29 | Sign-in, new conversations and file uploads failed on claude.ai, Claude Code, Cowork and the API | About 1 to 2.3 hours | Claude Status, TechRadar |
Sources: Claude Status; StatusGator outage history; Android Authority; The Register; TechRadar. Durations differ between sources because they measure from different start and end points.
StatusGator has logged 202 Claude incidents since January 2026. For the model-level view of the releases involved, see our Claude Opus 5.5 enterprise guide.
How we built this guide
We used only published, dated sources: Anthropic's status page and API documentation, NeuralTrust's TrustGate documentation, press coverage of each incident, one reliability report and one workforce survey. Third-party tracker durations are labeled as such. We did not run private uptime tests.
Why Depending on One AI Provider Is a Business Risk
A single AI provider is a single point of failure. When Claude stops, every workflow, agent and customer feature built only on Claude stops too. The risk is not specific to Anthropic: every major provider has outages, and some share infrastructure.
Outages are becoming a larger share of incidents
According to StackGen (2026), AI incidents rose from 1.7% of reported outages in 2023 to 10.7% in 2026, based on 178,000 public status-page records, as reported by Continuity Insights. The same report found that more than one in four incidents start at a third-party vendor. Those take about three times longer to resolve: a 247-minute median against 96 minutes for internal failures.
There is good news for the model vendors themselves. The report says AI model providers recover fastest, with a 49-minute median in 2026, down from 75 minutes in 2023. The problem is less the length of each outage than how often a single dependency interrupts work.
Correlated failures
Switching vendors is not always enough. On September 3, SpaceX attributed Grok's outage to "an outage at our Memphis compute center" and apologized to "impacted compute partners", according to The Register. When providers share compute, their outages can line up. A good fallback plan mixes providers and clouds, not just model names.
How Model Fallback Works: Three Levels
Model fallback means sending a failed request to a different target automatically, so the user gets an answer instead of an error. There are three levels, ordered from least to most behavior change: the same model on another cloud, another model from the same vendor, and a model from a different vendor.
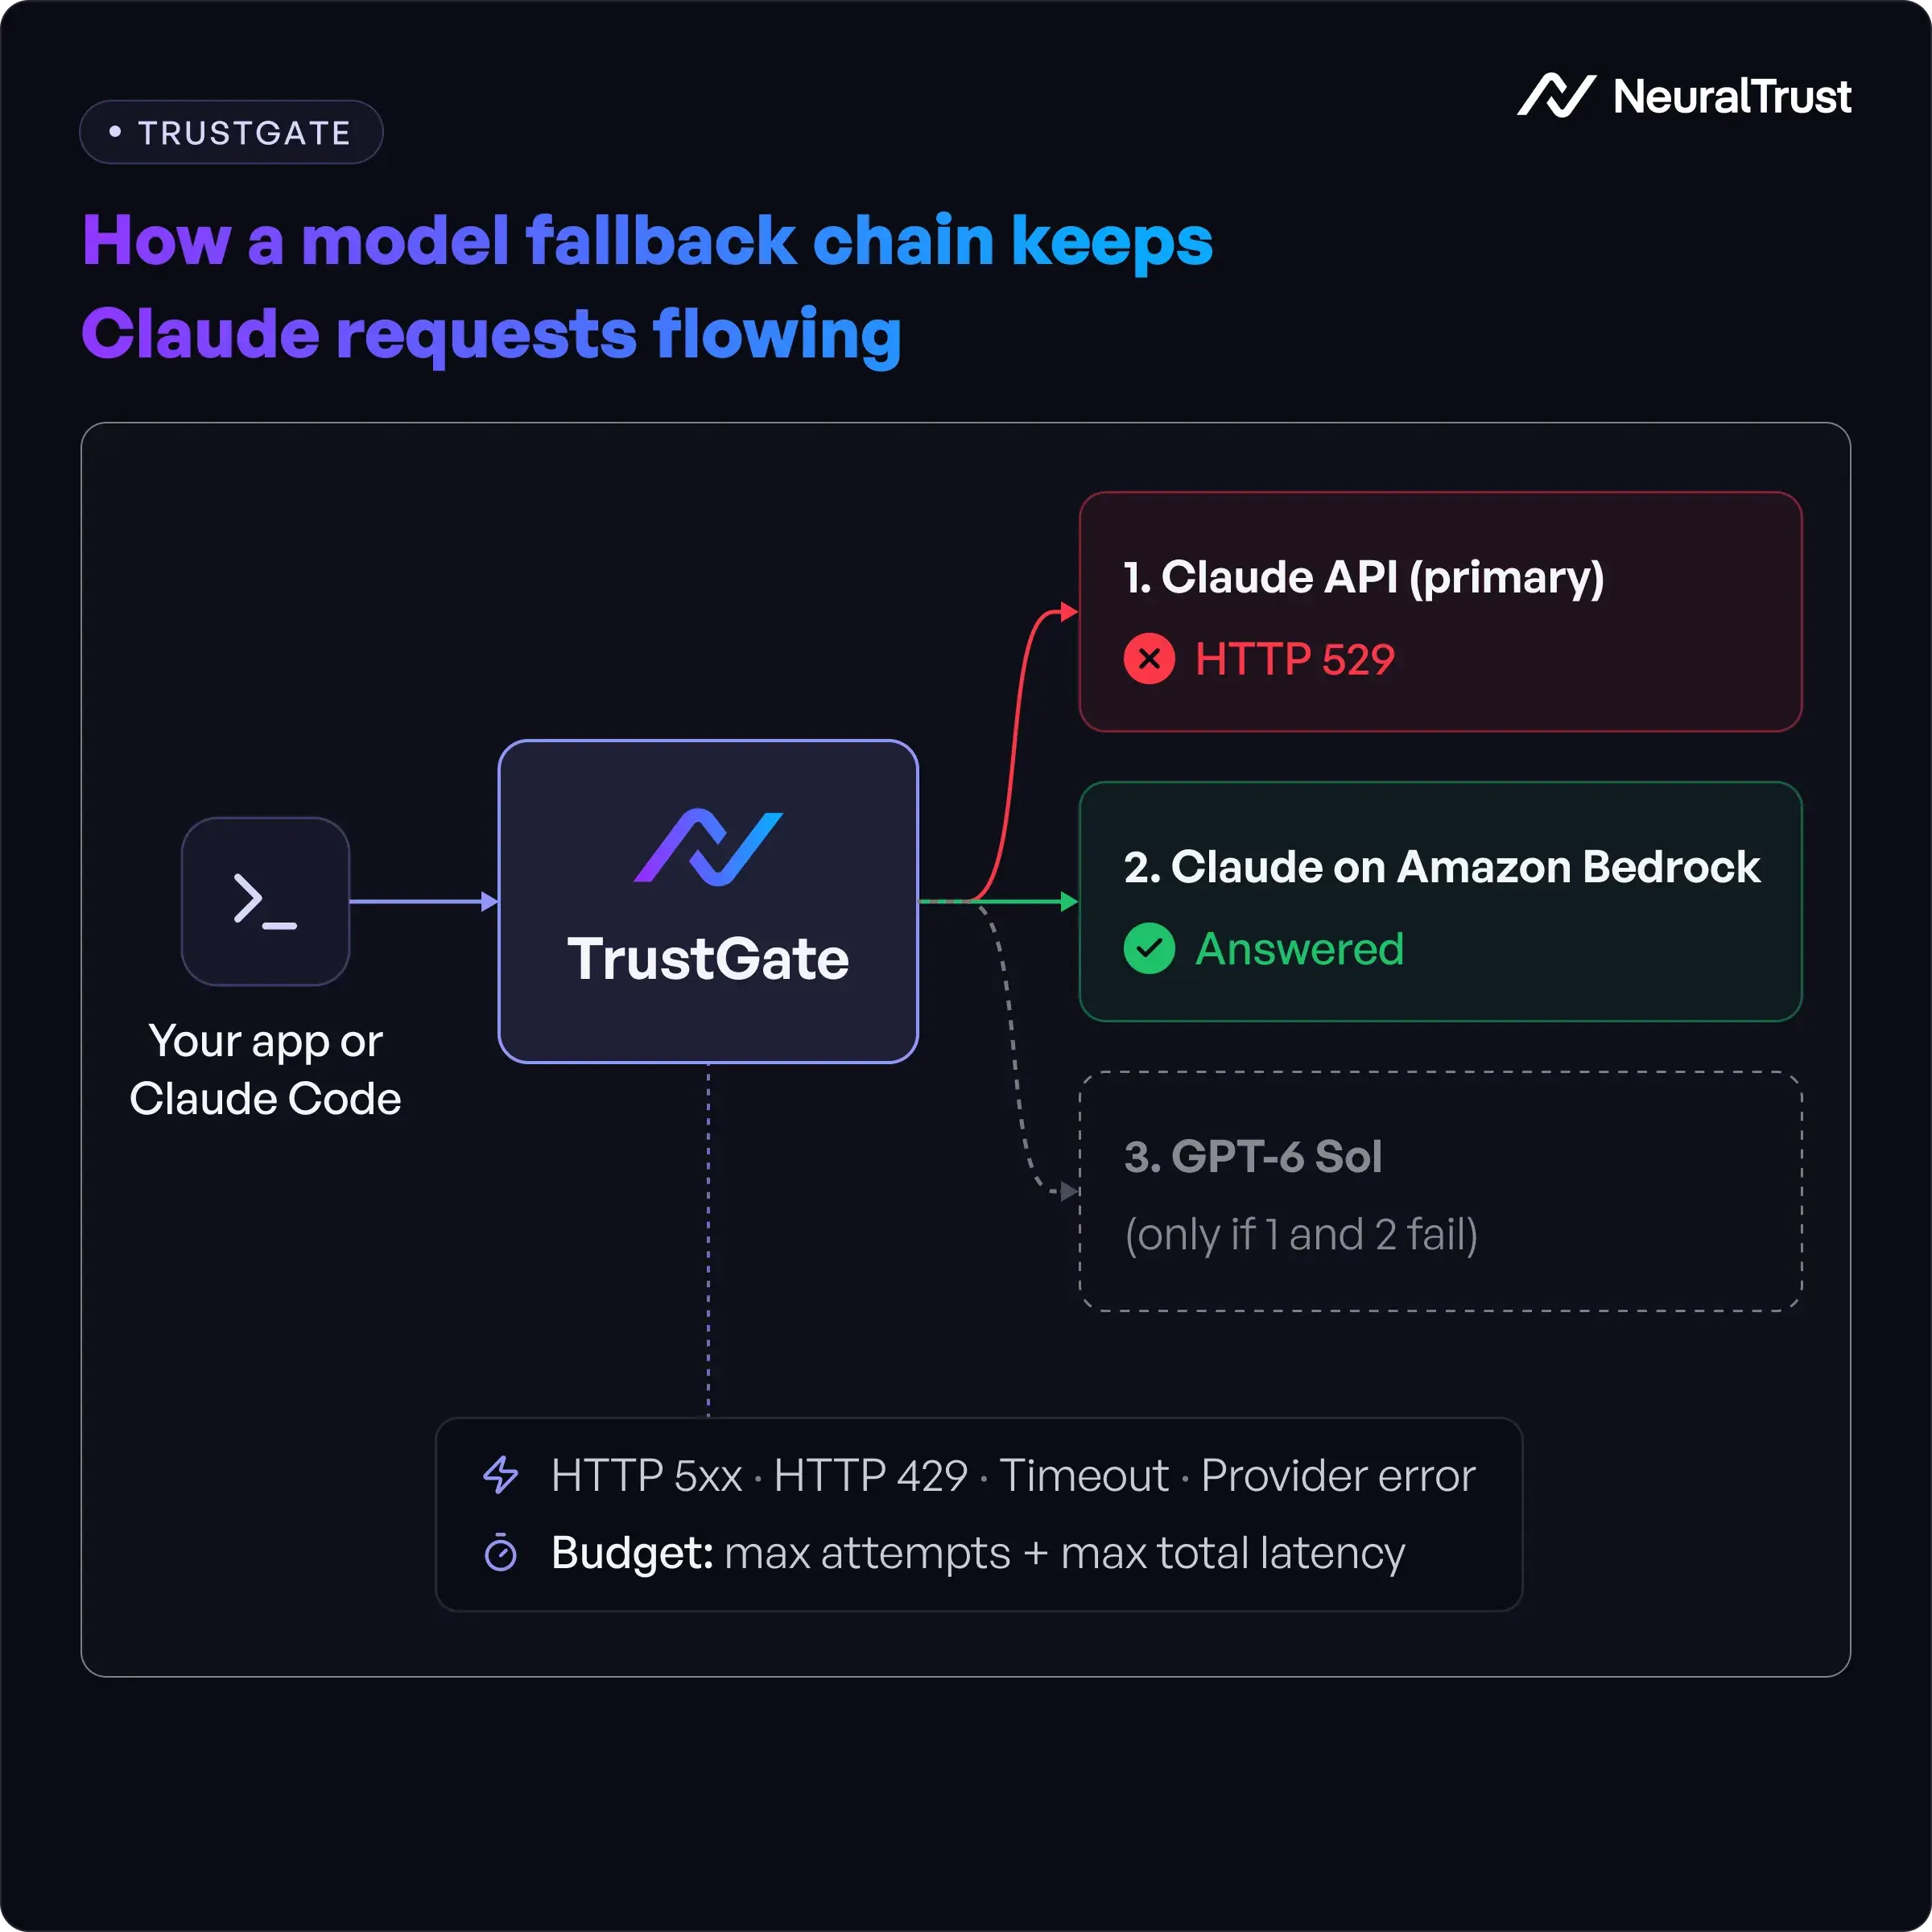
| Level | Example | Behavior change | Main trade-off |
|---|---|---|---|
| 1. Same model, another cloud | Claude Opus 5.5 on the Claude API, then on Amazon Bedrock | None: same weights, same prompts | Needs a contract and quota on the second cloud |
| 2. Another model, same vendor | Opus 5.5 to Sonnet 5.5 | Small: same API format and tool calling | Fails if the whole vendor is down |
| 3. Another vendor | Claude to GPT-6 Sol or Gemini 3.8 Flash | Larger: different prompts, formats and quirks | Needs testing and separate data terms |
Level 1: the same Claude model on another cloud
This is the cleanest fallback. Claude Opus 5.5 is available on Amazon Bedrock, Google Cloud and Microsoft Foundry, and Anthropic lists the same clouds for Claude Sonnet 5.5. The model is the same, so prompts and tool definitions keep working. It is also the only supported fallback for Claude Code.
Level 2: another Anthropic model
September's incidents often hit specific families. The September 22 incident, for example, listed Fable, Mythos and Opus models on the status page. A chain from Opus 5.5 to Sonnet 5.5 can keep work moving in that case, with the same API format. It does not help when the API itself or the login system fails, as on September 29.
Do not confuse this with Sonnet 5.5's built-in fallback. Its server-side fallbacks option routes flagged cyber requests to Sonnet 5 for safety reasons; it is not an outage feature, per Anthropic's What's new in Sonnet 5.5.
Level 3: another vendor
A cross-vendor chain survives a full Anthropic outage, but it changes behavior. Tool-calling formats, system prompt handling and output length differ between vendors, so test your prompts on the fallback model before you need it.
Pitfalls to plan for
- Thinking blocks: Sonnet 5.5 thinking blocks "work only in the account that produced them, or in an account linked to it", per Anthropic's preserved thinking docs. If a conversation moves to another account mid-session, the API drops them; the request still succeeds, but the model loses that earlier reasoning.
- Model names: TrustGate's docs warn that "the same model name has to exist on each registry you want it to reach, or the fallback stops there." Map names before an incident, not during one.
- Cost: a fallback model can cost more per token. Set budgets on the fallback path as well as the primary. Our AI token optimization guide covers the controls.
- Data terms: each provider has its own retention and training terms. Check them before a provider joins the chain.
How to Set Up Claude Fallback with TrustGate
TrustGate, NeuralTrust's AI gateway, sits between your apps and your model providers. It routes across 14 LLM providers, per the TrustGate documentation, and supports an ordered fallback chain or a load-balanced pool. Setup takes five steps.
Step 1: register your providers
Add each provider as a registry: for example the Claude API, Amazon Bedrock and, for a full-vendor fallback, OpenAI. Keep the provider credentials in the gateway. Developers and apps get gateway credentials instead, so revoking access means revoking one key.
Step 2: build an ordered fallback chain
TrustGate "forwards to the first; on a failure that matches a trigger, it moves to the next, and never re-tries a registry that already failed within the same request," per the routing docs. Put the lowest-change option first: Claude on the Claude API, then Claude on Bedrock, then another vendor.
Step 3: create use cases for alerts
Pick the failures that should move a request to the next provider. For an outage chain, use every trigger except policy rejection.
| Trigger | What it catches | Use it for |
|---|---|---|
| HTTP 5xx | "The upstream failed." Includes 500 and 529 | Outage resilience |
| HTTP 429 | "The upstream rate-limited you." | Resilience, when one provider throttles you |
| Timeout | "The upstream did not answer in time." | Hung requests during partial outages |
| Provider error | Errors reported in the provider's own terms | Resilience |
| Policy rejection | "A policy refused the request." | Degrade paths, not outage chains |
Source: TrustGate routing docs (September 2026).
The docs separate two intentions. A chain across providers is for resilience, while "a chain that goes from a flagship to a cheaper model is a degrade path, and those two intentions want different triggers."
Step 4: all the alerts visible in your SIEM
A budget sets "a maximum number of attempts including the first, and a maximum total latency across all of them." When it runs out, "the client gets the last error, not a synthesised one". Your app still sees an honest failure.
For steady traffic, a load-balanced pool is the alternative. In a pool, registries "with a health check are skipped while unhealthy and rejoin when they recover." Our LLM model routing guide compares routing strategies, and our AI gateway architecture explainer shows where the gateway sits.
Step 5: point your clients at the gateway
- Apps and agents: change the SDK base URL to your TrustGate LLM application and use the gateway key.
- Claude Code: NeuralTrust's Claude Code integration guide explains that "Claude Code can send its own model requests through an LLM application instead of straight to Anthropic", by setting
ANTHROPIC_BASE_URL. Pair it with a gateway credential: Anthropic notes that with only the base URL set, "a saved claude.ai login remains the active credential." - Test before you need it: in staging, point the first registry at an unreachable endpoint so it times out, and confirm that requests land on the second.
Security and Governance: Failing Over Without Losing Control
A fallback keeps work moving, but every new route is a new path for data. The security question during an outage is not only whether requests succeed, but whether the same policies apply on the fallback model and whether employees stay on approved tools.
The risks that appear during an outage
- Weaker controls on the fallback path. If guardrails live inside one provider's settings, a fallback to another provider can skip them. Prompt injection, ranked LLM01 by OWASP, works the same way against any model.
- Data exposure on a new provider. According to OWASP (2025), sensitive information disclosure covers "confidential business data, security credentials, and legal documents", per LLM02:2025. Each fallback provider must meet the same retention and residency terms as the primary. AWS, for example, says Bedrock offers zero data retention by default for Opus 5.5.
- Shadow AI. According to BlackFog (2026), 49% of workers admit to using AI tools without employer approval, and 58% of them use free versions. In the same survey of 2,000 workers, reported by CIO, 33% had shared enterprise research or datasets. An outage is exactly the moment people reach for a personal account.
- The gateway becomes critical. Anthropic's own guide warns that with a gateway, "the gateway becomes infrastructure your organization operates." Run it with the same availability standards as the services behind it.
How NeuralTrust keeps fallback safe
NeuralTrust's Runtime Security Mesh applies one set of controls to every provider in the chain:
- Agent Gateway (TrustGate): one policy point and one audit trail for the Claude API, Bedrock and any other vendor, with budgets and rate limits per application. TrustGate also ships with 200+ pre-built MCP servers for agent tool access.
- Agent Runtime Security (TrustGuard): inspects prompts, tool calls and responses in real time, so the same injection and data leakage checks run whichever model answers. For Claude Code, TrustGuard hooks evaluate prompts, shell commands and tool results before they run.
- Agent Posture Management (TrustLens): surfaces "every agent your employees interact with", including unregistered shadow AI, so you can see who switched tools during an outage.
- AI Red Teaming (TrustTest): tests the fallback models against injection and jailbreaks before they carry production traffic. See our indirect prompt injection guide for the attack paths.
Which Fallback Setup Should You Choose?
Most teams should start with level 1, the same Claude model on a second cloud, because it changes nothing about prompts. Add a cross-vendor model when a full Anthropic outage would cost more than the testing effort. Regulated teams should add providers only after a data-terms review.
| If you are... | Start with | Why |
|---|---|---|
| A small team on claude.ai | Status alerts and one approved backup assistant | No infrastructure to run; avoids shadow AI |
| An engineering team on Claude Code | Claude on Bedrock, Google Cloud or Foundry behind a gateway | The only supported Claude Code fallback |
| A product team running customer-facing agents | Chain: Claude API, Claude on Bedrock, then GPT-6 Sol or Gemini | Survives a full vendor outage |
| A platform team with steady volume | Load-balanced pool with health checks | Unhealthy providers are skipped automatically |
| A CISO in a regulated industry | Fallback only to providers with matching data terms | Keeps retention and residency consistent |
Conclusion
Is Claude down? Check status.claude.com first, read the error code, and stay signed in while Anthropic fixes it. Outages like September's are usually short, but they are frequent enough that a single-provider setup will stop your team again. The durable fix is a fallback chain, starting with the same Claude model on another cloud, with the same security policies on every route. That way the next outage is a status update, not a work stoppage.
Secure Claude and Its Fallbacks in Production with NeuralTrust
Route Claude, its cloud replicas and any backup model through one policy layer, with real-time protection for every prompt, tool call and MCP connection.
Related Comparisons
FAQs about "Is Claude Down?"
1. Is Claude down right now?
Check status.claude.com, Anthropic's official status page. It reports claude.ai, the Claude Console, the Claude API, Claude Code, Claude Cowork and Claude for Government separately. If a component shows an active incident, Claude is down for that product. If every component is green, the problem is more likely your rate limit, API key or network.
2. Why is Claude not working?
Either Anthropic has an incident or something on your side is failing. A 529 overloaded error or a 500 error points to Anthropic. A 429 usually means you hit a rate limit or spend cap, and 401 or 403 errors point to your API key or permissions. The status page tells you which case it is.
3. What does "Claude is overloaded" mean?
It means the Claude API returned a 529 overloaded_error: the service is temporarily overloaded by high traffic. It is on Anthropic's side, not yours. Anthropic recommends retrying with exponential backoff, and its official SDKs already retry twice by default. If 529 errors persist, a fallback to another provider keeps requests flowing.
4. How long do Claude outages last?
Most are short. In September 2026, the incidents on September 22 and September 29 lasted one to one and a half hours on Anthropic's status page. The September 3 incident lasted about two and a half to three hours. Across the industry, AI model providers resolved incidents in a 49-minute median in 2026, per StackGen's reliability report.
5. What can I use when Claude is down?
Use an alternative your company has approved, not a personal account on another AI tool. For developers, the best option is the same Claude model on Amazon Bedrock, Google Cloud or Microsoft Foundry. For apps, an AI gateway can fail over automatically to Claude on another cloud or to a model such as GPT-6 Sol or Gemini 3.8 Flash.
6. Does Claude Code work when Claude is down?
Not if the outage affects the Claude API or Claude Code component. Claude Code can run on Amazon Bedrock, Google Cloud or Microsoft Foundry instead, and a gateway can switch providers without reconfiguring each machine. Anthropic does not support routing Claude Code to non-Claude models, so the fallback must be Claude on another provider.
7. How do I set up an LLM fallback?
Put an AI gateway between your apps and your providers, then define an ordered chain, for example Claude API, Claude on Bedrock, then another vendor. Set triggers such as HTTP 5xx, 429 and timeouts, cap attempts and total latency, and map model names on every provider. Test the chain in staging before an outage.
About the Author
Roger Howroyd is Head of Global SEO and AI at NeuralTrust, where he leads the company's search strategy across SEO, AEO, GEO, and LLM optimization. He specializes in AI-powered search, content strategy, and SEM. Connect on LinkedIn.
NeuralTrust is the leading platform for securing and scaling AI agents. Named a Pioneer in the Gartner Emerging Market Quadrant for AI Application Security 2026, recognized across four Gartner Hype Cycle reports in 2026, and featured in the Gartner Market Guide for Guardian Agents 2026, the Gartner Market Guide for AI Gateways 2025 and the KuppingerCole Leadership Compass for Generative AI Defense 2025. Headquartered in Barcelona with offices in London and New York. ISO 27001 certified.
Sources
- Claude Status (September 30, 2026)
- Claude Status: Incident history (September 2026)
- Claude Docs: API errors (September 2026)
- Claude Code Docs: Other LLM gateways (September 2026)
- Claude Docs: Preserved thinking (September 2026)
- Claude Docs: What's new in Claude Sonnet 5.5 (September 2026)
- Anthropic: Introducing Claude Sonnet 5.5 (September 28, 2026)
- AWS: Claude Opus 5.5 on AWS (September 2026)
- The Register: ChatGPT, Claude and Grok outages at the same time (September 3, 2026)
- Android Authority: Claude outage, September 3 (September 3, 2026)
- Android Authority: Anthropic warns "don't log out" (September 29, 2026)
- TechRadar: Claude down, September 29 (September 29, 2026)
- StatusGator: Claude status (September 2026)
- StatusGator: Claude outage history (September 2026)
- isdown: Claude status (September 2026)
- Continuity Insights: StackGen State of Reliability Report 2026 (2026)
- CIO: BlackFog survey on unsanctioned AI tools (January 2026)
- OWASP: LLM01:2025 Prompt Injection (2025)
- OWASP: LLM02:2025 Sensitive Information Disclosure (2025)
- NeuralTrust Docs: TrustGate overview (September 2026)
- NeuralTrust Docs: TrustGate routing (September 2026)
- NeuralTrust Docs: Claude Code integration (September 2026)